# The Infinity - Full Content Knowledge Base
> This file contains the full text of our articles to aid Answer Engine Optimization (AEO) and LLM indexing.
## Negation in RAG, Measured: Most Rerankers Do Worse Than a Coin Flip
Author: Serdarcan Büyükdereli
Date: 2026-09-14
Category: DevOps Blog
URL: https://theinfinity.dev/articles/rag-negation-measured
I gave 13 local retrieval models a simple job. The query says *the backup did not complete*. Two documents are on the table: one says the backup failed, the other says it completed. Which one goes first? When the correct document used different words than the query, the average embedding model picked the wrong one **72% of the time**. The average reranker did slightly worse, at 74%. Gemma 4, running on a laptop, got all 80 decisions right.
I ran this because my own notes were wrong. I am building a fully local RAG pipeline over a mixed Turkish and English archive of technical notes, and an earlier test had convinced me that negation was an embedding problem and a reranker would fix it. I wrote that down as a requirement. Then I measured it as a ranking problem, which is what retrieval actually does, and the reranker did not fix it.
This article covers the test design, the results for 14 models in two languages, a control run that shows what is really going on, where an LLM fixes it and what that costs on a 32 GB Mac, and a small script so you can run the same test against your own models. The test set is published. None of it comes from my private notes.
> 💡 **Short answer:** Embedding models and rerankers do encode negation, but they weigh shared words more heavily. If the wrong document repeats the query's words and the right one paraphrases it, most of them rank the wrong one first. A local LLM reading both documents gets it right, so let the generation step see several chunks instead of trusting the top hit.
Scope: local models only, run through Ollama 0.34.0 and sentence-transformers on an Apple M5 with 32 GB of unified memory. 20 hand-written triplets per language, each tested in both directions, so 40 decisions per language per condition. This is a stress test for one failure mode, not a leaderboard.
## Why negation is hard for retrieval models
A bi-encoder turns a sentence into one vector before it ever sees your query. "The backup completed" and "The backup did not complete" share almost every token, so their vectors land close together. In my runs the two opposite documents had a cosine similarity between 0.71 and 0.96 depending on the model.
A cross-encoder reranker reads the query and the document together, so in theory it can see the "not". In practice most rerankers are trained to answer "is this passage relevant to this query?" A document about the backup failing is highly relevant to a question about the backup completing. Topic relevance and factual agreement are different things, and the training signal mostly rewards the first one. That is my reading of the results, not something I measured directly.
This is not a new observation. The [NevIR benchmark](https://aclanthology.org/2024.eacl-long.139/) showed in 2024 that most neural retrievers do no better than random on document pairs that differ only by negation. A [SIGIR 2025 reproduction](https://arxiv.org/html/2502.13506) extended it to newer models and found the same ordering: bi-encoders at the bottom, cross-encoders in the middle, LLMs on top. What those studies do not cover is a language where negation lives inside the word, how much of the failure comes from word overlap, and what the fix costs on local hardware.
## How the test works
Each triplet has a positive query, a negative query, and documents on both sides. It runs twice. The positive query should rank the positive document first, and the negative query should rank the negative document first. A model that always prefers the positive document scores exactly 50%, so 50% is the coin-flip line.
Here is one triplet, in the three conditions I tested:
```text
query (negative) backup did not complete
same wording right: The nightly PostgreSQL backup did not complete at 02:00 and nothing was uploaded to S3.
wrong: The nightly PostgreSQL backup completed at 02:00 and was uploaded to S3.
different wording right: Last night's PostgreSQL dump broke off before 02:00, so S3 received no file.
wrong: The nightly PostgreSQL backup completed at 02:00 and was uploaded to S3.
control right: Last night's PostgreSQL dump broke off before 02:00, so S3 received no file.
wrong: Last night's PostgreSQL dump finished successfully and the file landed in S3 at 02:00.
```
The *same wording* condition is the textbook test, and it is the one I ran first. The *different wording* condition is the one that looks like a real corpus: the document you want was written by someone else, in their own words, while a document with the opposite outcome happens to reuse your query's phrasing. The *control* removes that asymmetry. Both documents are paraphrases and only the outcome differs.
The set covers three kinds of flip. Eight triplets use an explicit marker such as *not*, *never* or *cannot*. Eight use antonyms such as *succeeded* and *failed*, or *allows* and *blocks*. Four change state: *resolved* and *still ongoing*, *all* and *none*. The Turkish set mirrors the English one, so Turkish negation shows up as a suffix (*tamamlandı* versus *tamamlanmadı*) rather than a separate word.
Models with a documented prompt format ran with it: `query:` and `passage:` for e5, the task prefixes for EmbeddingGemma, and the instruction prefix for Qwen3-Embedding. The full set is [downloadable as JSON](/images/articles/rag-negation-measured/negation-test-set.json).
## With the same wording, everything passes
When the right document repeats the query's words, every model family looks excellent. That result is the reason this failure goes unnoticed.
| Model family | Same wording | Different wording | Control |
|---|---|---|---|
| Embedding models (7) | 96% | 28% | 72% |
| Rerankers (6) | 97% | 26% | 72% |
| Gemma 4 26B-A4B, choosing A or B | 100% | 100% | 98% |
Averages across English and Turkish, 40 decisions per language per model.
If I had stopped after the first column, I would have concluded that negation is solved. The models are not reading the negation in that case. They are matching "did not complete" in the query to "did not complete" in the document. Remove the shared phrase and the picture changes completely.
## With different wording, most models pick the wrong document
When the right document paraphrases the query and the wrong one shares its words, 10 of the 13 retrieval models score below 50% in both languages, and none reaches 75% in either. They are not guessing. They are consistently choosing the document with the opposite meaning.
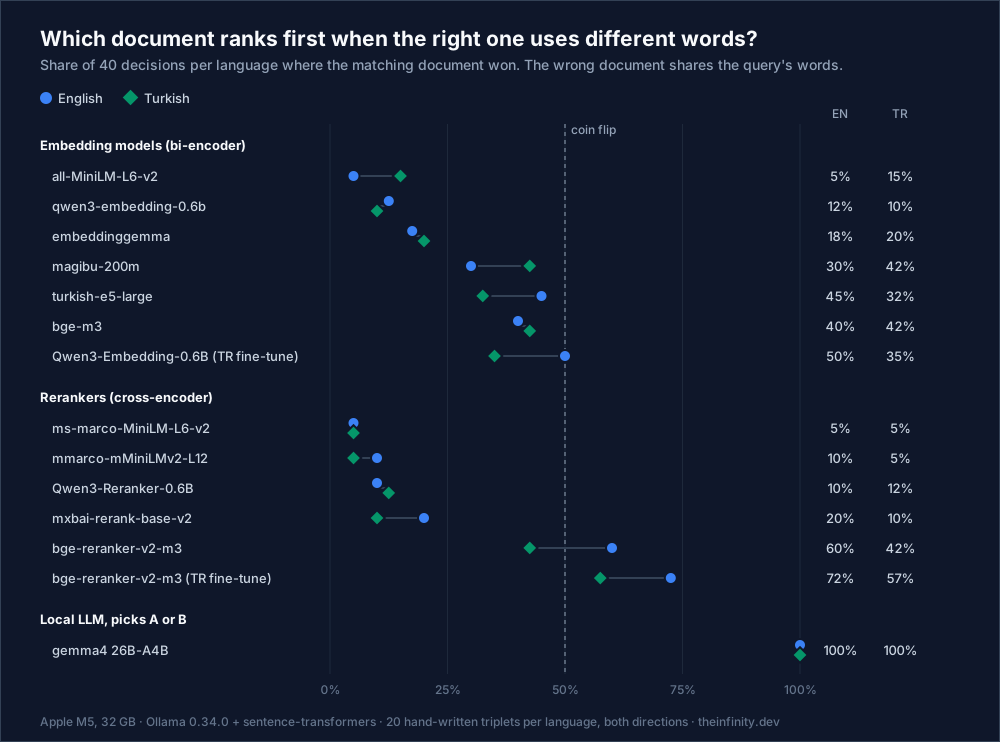
| Model | Type | English | Turkish |
|---|---|---|---|
| all-MiniLM-L6-v2 | embedding | 5% | 15% |
| qwen3-embedding 0.6B | embedding | 12% | 10% |
| EmbeddingGemma | embedding | 18% | 20% |
| magibu-200m | embedding | 30% | 42% |
| turkish-e5-large | embedding | 45% | 32% |
| bge-m3 | embedding | 40% | 42% |
| Qwen3-Embedding-0.6B, Turkish fine-tune | embedding | 50% | 35% |
| ms-marco-MiniLM-L6-v2 | reranker | 5% | 5% |
| mmarco-mMiniLMv2-L12 | reranker | 10% | 5% |
| Qwen3-Reranker-0.6B | reranker | 10% | 12% |
| mxbai-rerank-base-v2 | reranker | 20% | 10% |
| bge-reranker-v2-m3 | reranker | 60% | 42% |
| bge-reranker-v2-m3, Turkish fine-tune | reranker | 72% | 57% |
| Gemma 4 26B-A4B | local LLM | 100% | 100% |
The two tutorial defaults, all-MiniLM-L6-v2 and ms-marco-MiniLM-L6-v2, both score 5% in English. That is 38 wrong answers out of 40. If your pipeline was copied from a getting-started guide, this is the pair you are running.
The type of flip matters. Among rerankers, explicit negation was the worst case at 13%, antonyms reached 24%, and state words such as *resolved* versus *still ongoing* reached 55%. Embedding models were weakest on antonyms at 17%. Language made less difference than I expected. Turkish puts negation inside the word as a suffix, yet embedding models averaged 29% in English and 28% in Turkish. Rerankers did drop further in Turkish, from 30% to 22%.
## Is it negation, or just word overlap?
It is mostly word overlap winning over meaning. In the control condition, where both documents are paraphrases, the same models reach 72% on average, and the best ones do well: bge-m3 scores 85-88% and bge-reranker-v2-m3 scores 90% in both languages.
So the models are not blind to negation. They carry a polarity signal, and it is weaker than the signal from shared vocabulary. When the two signals point in the same direction, as in the textbook test, you get 96%. When they point in opposite directions, overlap wins most of the time.
That distinction matters for what you do about it. A model that ignored negation entirely would need replacing. A model that underweights it needs a second step that reads the documents properly, or a design that stops relying on text similarity for facts that have a yes-or-no answer.
## Does a newer or bigger reranker help?
Not reliably. Newer and higher-ranked on a leaderboard did not mean better at this test.
Qwen3-Reranker-0.6B is the newest reranker here. Its [model card](https://huggingface.co/Qwen/Qwen3-Reranker-0.6B) reports 66.36 on MMTEB-R against 58.36 for bge-reranker-v2-m3, an eight-point lead on multilingual reranking. On the different-wording test it scored 10% in English. The older bge-reranker-v2-m3 scored 60%. A Turkish fine-tune of that same bge model did best overall, at 57% in Turkish and, less expectedly, 72% in English.
The SIGIR 2025 reproduction points the same way. Its best cross-encoder was jina-reranker-v2-base-multilingual at 65.2% on NevIR, and bge-reranker-v2-m3 scored 43.5%, against a random baseline of 25% on that benchmark's stricter pairwise metric. I did not test the Jina model, because loading it requires `trust_remote_code`.
I ran into the same gap between leaderboards and reality earlier in this project. On 25 real questions against my own notes, Qwen3-Reranker-0.6B scored an MRR of 0.698 against 0.818 for bge-reranker-v2-m3, and ran four times slower. Leaderboard averages are a reasonable shortlist. They are not a substitute for testing on sentences that look like yours.
## Can a local LLM fix it, and what does it cost?
Yes, and the cost is lower than I assumed. Gemma 4 26B-A4B scored 100% on both the same-wording and different-wording tests, and 98% on the control, where it missed two Turkish decisions. Each decision took about 330 ms.
The setup was a plain A/B question, with the right document alternating between position A and B so position bias could not help:
```text
Query: backup did not complete
Document A: The nightly PostgreSQL backup completed at 02:00 and was uploaded to S3.
Document B: Last night's PostgreSQL dump broke off before 02:00, so S3 received no file.
Which document states what the query says? Answer with a single letter: A or B.
```
That does not make the LLM a good reranker. I tried exactly that on my own notes: Gemma 4 ranking 20 candidates at once returned valid JSON every time, but reached an MRR of 0.679 against 0.768 for the cross-encoder, and took 5.3 seconds per query, 17 times slower. The LLM is good at reading two documents closely. It is worse at ordering twenty.
The practical placement is the generation step, which already reads the retrieved chunks. If it gets five or ten chunks instead of one, a document with the opposite outcome sitting in first place is something it can notice and route around.
### How fast is Gemma 4 26B-A4B on a 32 GB Mac?
About 29 tokens per second of output and 600 tokens per second of prompt processing. That makes it roughly four times faster than a dense 27B model at the same quantization on the same machine.
| Model | Prompt tokens | Prefill (tok/s) | Decode (tok/s) | Total for 256 output tokens |
|---|---|---|---|---|
| Gemma 4 26B-A4B, MoE, Q4_K_M | 298 | 562 | 32.6 | 8.4 s |
| Gemma 4 26B-A4B, MoE, Q4_K_M | 1,869 | 612 | 29.4 | 11.9 s |
| Gemma 4 26B-A4B, MoE, Q4_K_M | 7,266 | 543 | 27.9 | 22.7 s |
| qwen3.8 27B, dense, Q4_K_M | 295 | 105 | 8.4 | 33.2 s |
| qwen3.8 27B, dense, Q4_K_M | 1,846 | 118 | 7.4 | 50.2 s |
| qwen3.8 27B, dense, Q4_K_M | 7,294 | 110 | 6.9 | 105.1 s |
Medians of three runs, Ollama 0.34.0, 16K context, thinking disabled, temperature 0. Each prompt started with a random nonce, because otherwise Ollama's prompt cache reuses the previous run and reports a prefill time close to zero.
Gemma 4 26B-A4B is a mixture-of-experts model: 25.8B parameters in total, about 3.8B active per token. That explains the gap. On this machine Ollama runs both models through llama.cpp with Metal, not the MLX backend, which I confirmed from the running process. The dense model had speculative decoding enabled and was still four times slower.
For RAG, a context of ten chunks at roughly 250 tokens each is about 2,500 prompt tokens, which Gemma 4 processes in around four seconds before it starts writing. That is the realistic price of letting the LLM read more than the top hit.
## Where this breaks a real pipeline
The failure only hurts when the wrong document reaches a place where nobody reads it critically. Three places are common.
The first is anything that shows or uses the top hit directly. A search box, an agent tool that returns "the most relevant note", or a pipeline that passes `k=1` to save tokens. There is no second reader in that path.
The second is documents that record changing state. Incident notes say *ongoing* and later *resolved*. Deploy logs say *failed* and then *succeeded*. Runbooks describe the broken state and the fixed state. These corpora are full of near-identical sentences with opposite outcomes, which is precisely the shape of this test.
The third is score thresholds. If you drop anything below a similarity cutoff, the paraphrased right answer can fall under the line while the word-matching wrong answer stays above it.
None of this means you should remove your reranker. On my own notes, with 25 test questions, adding a reranker on top of hybrid search raised MRR from 0.732 to 0.841 at 1,500 chunks, from 0.629 to 0.820 at 4,800 chunks, and from 0.480 to 0.688 at 20,000 chunks. Rerankers are good at ranking relevance. Relevance is simply not the same as agreement.
## What to do about it
Pick the fix that matches where the wrong document would do damage.
| Situation | What to do |
|---|---|
| An LLM writes the answer from retrieved chunks | Pass 5-10 chunks, not 1, and ask it to quote the sentence that states the outcome |
| The top hit is shown or used directly | Add an LLM check on the top candidates, or show several results |
| Documents record state that changes | Store the state as metadata, such as `status: resolved`, and filter on it instead of matching text |
| Choosing a reranker | Test your shortlist on contradiction pairs from your own domain before trusting a leaderboard |
| Non-English content | Expect the same failure; the Turkish results tracked the English ones closely |
Metadata is the most reliable of these, and the most often skipped. Whether a backup succeeded is a boolean. Asking a vector space to recover a boolean from prose is harder than storing it once when the document is written. Vector databases such as Qdrant support payload filters for exactly this.
## How to run this test on your own models
Download the [test set](/images/articles/rag-negation-measured/negation-test-set.json), then swap in your own embedding model and reranker. With the two tutorial defaults below, this script prints the same numbers reported above: 88% and 100% with the same wording, 5% and 5% with different wording.
```python
# pip install sentence-transformers
import json
from sentence_transformers import SentenceTransformer, CrossEncoder
triplets = json.load(open("negation-test-set.json"))["en"] # or "tr"
def decisions(t, condition):
"""Each triplet becomes two decisions: (query, right_doc, wrong_doc)."""
if condition == "same_wording":
return [(t["query_positive"], t["doc_positive"], t["doc_negative"]),
(t["query_negative"], t["doc_negative"], t["doc_positive"])]
# the right document is a paraphrase; the wrong one shares the query's words
return [(t["query_positive"], t["paraphrase_positive"], t["doc_negative"]),
(t["query_negative"], t["paraphrase_negative"], t["doc_positive"])]
embedder = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")
reranker = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2")
for condition in ("same_wording", "different_wording"):
rows = [d for t in triplets for d in decisions(t, condition)]
q, right, wrong = (embedder.encode([r[i] for r in rows], normalize_embeddings=True) for i in range(3))
emb_acc = ((q * right).sum(1) > (q * wrong).sum(1)).mean()
rr_acc = (reranker.predict([(r[0], r[1]) for r in rows])
> reranker.predict([(r[0], r[2]) for r in rows])).mean()
print(f"{condition:18} embedding {emb_acc:.0%} reranker {rr_acc:.0%}")
```
If your model needs a query prefix, add it to the query strings before encoding. Better still, write ten triplets from your own documents. The phrasing of your corpus is what decides how badly this bites.
## Limits of this test
The sample is small. 40 decisions per language gives a 95% confidence interval of roughly ±15 percentage points for scores in the middle of the range, so a 10-point gap between two rerankers is not a meaningful ranking. The gaps between 5% and 50%, or between 26% and 100%, are.
I wrote every sentence myself, and the different-wording condition was built to be hard. Real corpora will not always place a word-for-word opposite next to a paraphrased answer. The A/B format is also easier for an LLM than scoring documents one at a time. Everything ran on one machine, and scores from hosted embedding APIs may differ.
## FAQ
### Do embedding models understand negation?
Partly. In this test, embedding models ranked the correct document first 72% of the time when both candidates were paraphrases, so they do carry a polarity signal. When the wrong document shared the query's words, their average dropped to 28%, because shared vocabulary outweighs the negation.
### Does a reranker fix negation in RAG?
Not on its own. Six local cross-encoder rerankers averaged 26% when the right document used different words and the wrong one shared the query's words, which is worse than a coin flip. The best, a Turkish fine-tune of bge-reranker-v2-m3, reached 72% in English, so it still got more than one in four decisions wrong.
### Which reranker handles negation best?
Among local rerankers tested here, bge-reranker-v2-m3 and its Turkish fine-tune did best, at 60% and 72% on English. Qwen3-Reranker-0.6B scored 10% despite a higher MMTEB-R score. A SIGIR 2025 reproduction of NevIR found jina-reranker-v2-base-multilingual to be the strongest cross-encoder in its set. Leaderboard position did not predict negation handling.
### Can an LLM be used as a reranker to handle negation?
An LLM handles negation well when it compares documents directly. Gemma 4 26B-A4B chose correctly in 80 of 80 different-wording decisions at about 330 ms each. As a general reranker over 20 candidates it was worse than a cross-encoder, with an MRR of 0.679 against 0.768 and 17 times the latency, so it fits better at the generation step than in the ranking step.
### How fast is Gemma 4 26B-A4B on a Mac with 32 GB of memory?
On an Apple M5 with 32 GB, through Ollama 0.34.0, Gemma 4 26B-A4B at Q4_K_M generated 28-33 tokens per second and processed prompts at 540-610 tokens per second. A dense 27B model at the same quantization managed 7-8.5 tokens per second. A 1,900-token RAG prompt with a 256-token answer took 12 seconds with Gemma 4 and 50 seconds with the dense model.
### How do I test my RAG pipeline for negation errors?
Write pairs of documents from your own domain that describe the same event with opposite outcomes, and phrase one of them differently from your test query. Run both directions of the query and count how often the matching document ranks first; 50% means the model is not distinguishing them. The test set and script in this article give you a starting point in English and Turkish.
## The thing I got wrong first
My project notes said the reranker would solve negation. The evidence behind that was a similarity test: all six embedding models I had compared rated "the backup was taken" and "the backup could not be taken" as more similar than genuine paraphrases, and I reasoned that a cross-encoder, which reads both texts together, would catch the difference. It sounded right, so I wrote it down as a requirement and moved on. When I finally tested ranking, which is the operation retrieval actually performs, the reranker I was using scored 42% in Turkish.
The Gemma 4 speed number in those notes was wrong for a similar reason. I had recorded 11.7 tokens per second and concluded that the mixture-of-experts design was not paying off. That figure was output tokens divided by total time, including the processing of a 2,500-token prompt. Measured separately, decoding runs at 29 tokens per second.
Both mistakes came from measuring something near the question instead of the question itself. Similarity is not ranking, and total time is not generation speed. If you take one habit from this, make your test perform the exact operation your pipeline performs. You can see that operation step by step in the [RAG pipeline simulator](/simulators/rag-pipeline).
---
## What a Screenshot Costs an AI Agent: 25,457 Tool Results Measured
Author: Serdarcan Büyükdereli
Date: 2026-08-28
Category: DevOps Blog
URL: https://theinfinity.dev/articles/agent-tool-cost-measured
A screenshot handed to an agent cost me a median of **2,054 tokens**. Reading one file cost 2,085. That is a difference of one percent, and it is the opposite of what everybody assumes.
The assumption is understandable. Open a transcript and a screenshot looks enormous — about 123 KB of base64 sitting in the middle of your conversation, dwarfing every other line. So people avoid vision, scrape the DOM instead, and pipe text into the model because text feels cheap.
I measured 25,457 tool results across 329 sessions, six weeks of real billed work, and text is not cheap. It is *unbounded*, which is worse. A screenshot's cost is set by pixel area, so it lands in the same narrow band every time. A file read is set by how long the file happens to be, and files have no upper limit.
That difference does not show up in the average. It shows up in the tail, and the tail is what wrecks a context window.
## What a tool result actually costs
Each row below is the median growth in the prompt of the assistant turn that *follows* that kind of tool result. That is where a tool result is actually billed: not in its own line, but in every prompt after it.
| preceding result | calls | median | p90 | p99 | p90 ÷ median |
|---|---|---|---|---|---|
| search | 1,120 | 3,104 | 7,128 | 14,833 | 2.3× |
| file write | 946 | 2,990 | 10,086 | 20,874 | 3.4× |
| file read | 778 | 2,085 | 11,401 | 29,824 | 5.5× |
| screenshot | 1,345 | 2,054 | 3,588 | 6,140 | **1.7×** |
| bash | 16,293 | 1,278 | 3,556 | 9,223 | 2.8× |
| file edit | 2,167 | 928 | 2,562 | 7,253 | 2.8× |
| plain text | 2,808 | 772 | 3,224 | 12,243 | 4.2× |
Read the last column before the first. It is the ratio between a typical result and a bad one, and it separates the tools you can budget for from the ones you cannot.
## Is a screenshot expensive?
No. At the median it costs the same as reading a single file, and at the tail it costs one fifth as much. Screenshot p99 is 6,140 tokens; file read p99 is 29,824.
The mechanism is not subtle. An image is billed by area, and a screenshot of a browser window is always roughly the same area, so the cost lands between 1,800 and 3,600 tokens over and over. There is no screenshot that is fifty times larger than a normal screenshot.
Text has no such governor. `cat` a 40-line config and you pay for 40 lines. `cat` a 4,000-line lockfile and you pay for 4,000. Same tool, same call, two orders of magnitude apart — and nothing in the call site tells you which one you are about to get.
That is why screenshots came out as the **most predictable tool in the entire set**, at 1.7× between median and p90. File reads were the least predictable, at 5.5×.
## Then what is actually running up the bill?
Bash, by sheer volume. It was 64% of all tool results — 16,293 of 25,457 — at the second-lowest median in the table.
This is the same shape I found [measuring 23,968 turns of prompt-to-output ratio](/articles/agent-token-cost-measured) and again [measuring what delegation actually costs](/articles/subagent-cost-measured). The bill is not built from a few dramatic events. It is built from thousands of small ones that never get deleted, because every one of them stays in the prompt for the rest of the session.
Charging the first cache write only — the conservative floor — bash accounted for roughly $183 of about $319 across the window. Screenshots accounted for $21. The thing people avoid is six percent of the problem.
> ⚠️ **Watch out:** these figures are the *first* time a result enters the prompt. From then on it is re-read as cached context on every subsequent turn, so a result that lands early in a long session is charged far more than once. The ranking does not change; the absolute numbers are floors.
## The three traps in measuring this
Every one of these produced a confident wrong number before it was caught, and two of them would have inverted the article's conclusion.
**Base64 length is not token count.** A screenshot occupies about 123 KB of base64 in the transcript. Taking that as the cost makes an image look roughly fifty times more expensive than it is, because the model bills images by pixel area and never sees the base64 as text. This one is seductive: the raw file makes vision look catastrophic, and that matches what everybody already believes.
**Key signatures, not key guesses.** Classifying results by "does this dict contain `content`" put 635 `Write` results into the `Read` bucket alongside 605 real reads. The headline of this article is a comparison between screenshots and file reads, so a bucket that is half writes is not a rounding error — it is a different article. Classify on the exact key signature (`file` for reads, `structuredPatch`+`content` for writes, `stdout` for bash).
**Streaming repeats `message.id`.** Counting rows instead of unique message ids multiplies turns and every per-turn figure derived from them.
And one that is not a data trap but a thinking one. The first version of this measurement asked "how much more do screenshot turns cost than normal turns" and got 1.59×, below the threshold I had set for the finding to be worth publishing. The correct response was to drop the thesis, not to soften the threshold. The article you are reading exists because the answer to a *different* comparison — screenshots against file reads specifically — turned out to be interesting in the other direction.
## What to do about it
Cap the tools that have no ceiling, and stop rationing the one that does.
**Read ranges, not files.** A file read's p99 was 29,824 tokens, fourteen times its own median. Passing an offset and a limit converts an unbounded cost into a bounded one. When you only need to know whether a symbol exists, grep for it — search has a higher median than a read but a far shorter tail, 14,833 against 29,824 at p99.
**Do not read the same file twice.** In this window there were 325 redundant reads against 717 unique files, a 45% overhead on top of a tool that is already the most volatile in the set. Re-reading a file you edited is the common case, and it is almost never necessary — the edit already told you what changed.
**Take the screenshot.** It is the cheapest way to find out what a page actually looks like, it cannot surprise you by being twenty times larger than expected, and the DOM dump you were going to use instead lands in the unbounded column.
**Delegate before your context is huge, not after.** A tool result costs its listed price once and then rides along in every later prompt. Work handed to a subagent leaves nothing behind in the parent, which is why [a subagent turn cost a third of a main-loop turn](/articles/subagent-cost-measured) — it carries less, not because it is billed differently.
**Watch bash output, not bash count.** Sixty-four percent of results came from bash. A command that prints a whole file is a file read wearing a different hat, and it does not show up in anybody's mental model of "I just ran one command."
## How I measured this
Every Claude Code session writes a JSONL transcript under `~/.claude/projects/`, and every assistant record carries a `usage` block with real token counts. A tool result does not carry its own price, so the cost is derived from what happens next: the growth in the following turn's prompt.
```python
p = (u["input_tokens"] + u["cache_creation_input_tokens"]
+ u["cache_read_input_tokens"])
if prev is not None and pending_tool_kind:
delta = p - prev # what this result added to the prompt
```
Results are classified by the exact key signature of `toolUseResult`: `stdout` means bash, `file` means a read, `structuredPatch` with `content` means a write, an `image` block inside `tool_result` means a screenshot. Turns are deduplicated by `message.id`. Deltas above 400,000 tokens are dropped as session boundaries rather than tool results.
The window is 2026-07-16 to 2026-08-28: 329 sessions, 25,457 classified tool results, 1,351 screenshots. Dollar figures use list pricing with the 1.25× cache-write multiplier and count only the first write.
Three limits worth stating. This is one developer's tool mix, and a heavier browser-automation practice would shift the screenshot share well above 5.3%. Screenshot cost depends on capture resolution, so a 4K display would move that row and not the others. And the delta method attributes the whole prompt growth to the preceding tool result, which slightly overcounts when the user typed something in the same gap — that inflates every row roughly equally, so the ranking holds even though the absolute numbers are soft.
## FAQ
### How many tokens is a screenshot?
Measured across 1,345 screenshots, the median added 2,054 tokens to the prompt, with a p90 of 3,588 and a p99 of 6,140. The base64 blob in the transcript is around 123 KB, but that is storage, not billing — images are priced by pixel area, so capture resolution sets the cost.
### Is computer use expensive compared to reading files?
No. A screenshot and a single file read cost almost exactly the same at the median, 2,054 against 2,085 tokens. At the 99th percentile the file read costs nearly five times more, because an image's size is bounded by the screen and a file's is not.
### What makes an AI agent's context fill up fastest?
Volume of ordinary results, not size of dramatic ones. Bash was 64% of all tool results here, at a median of 1,278 tokens each. Nothing gets removed from a prompt once it is in, so thousands of small outputs outweigh a handful of large ones.
### Should I use screenshots or scrape the DOM for browser agents?
Screenshots, on cost grounds. A DOM dump is text with no upper bound and lands in the same category as an unbounded file read, whose p99 was 29,824 tokens. A screenshot cannot exceed roughly 6,000 tokens at the same percentile.
### Does reading a file with an offset and limit actually help?
Yes, and the size of the win is the gap between a file read's median and its tail: 2,085 tokens against 29,824 at p99. Ranged reads convert an unbounded cost into a bounded one, which matters more than the average saving.
### How do I measure this on my own machine?
Parse the JSONL transcripts under `~/.claude/projects/`, deduplicate assistant turns by `message.id`, and take each turn's prompt total minus the previous turn's. Attribute that delta to whichever tool result arrived in between, classifying by the key signature of `toolUseResult` rather than by guessing on field names.
## The part worth keeping
The instinct that images are heavy comes from looking at bytes on disk. Bytes on disk are not what you are billed for, and the tool that looks alarming in a text editor turned out to be the only one in the set whose cost you can predict before you call it.
Predictability is the property that matters when a budget is finite. A tool with a known ceiling can be planned around. A tool without one can only be regretted afterwards, and the one people reach for to avoid the expensive option is exactly that tool.
---
## Connection Pool Sizing, Measured: Why 48 Connections Beat 400
Author: Serdarcan Büyükdereli
Date: 2026-08-21
Category: DevOps Blog
URL: https://theinfinity.dev/articles/connection-pool-sizing-measured
I swept a PostgreSQL instance from 1 connection to 400 and measured throughput at every step. It peaked at **48 connections** with 18,039 transactions per second. At 400 — the configured `max_connections`, the number the pool was allowed to reach — it managed 10,992. That is 37% less work from eight times the connections, and average latency went from 2.7 ms to 36.4 ms along the way.
This matters because raising the pool size is the reflex fix. The app is slow, the pool looks saturated, somebody bumps `maximumPoolSize` from 20 to 100, and the graphs get worse. It is not a paradox and it is not bad luck. Every PostgreSQL connection is an operating system process, and once more of them are running queries than you have cores, they stop working and start taking turns.
The shape of that curve is the whole subject. You can [drag the sliders in the simulator](/simulators/connection-pool) and find where your own workload turns over — the model there is fitted to the benchmark below, not invented.
## What the curve actually looks like
Throughput climbs steeply, flattens, peaks, and then declines slowly while latency climbs without limit. Here are the measured points, each the median of three runs on the same machine:
| connections | throughput | avg latency | vs peak |
|---|---|---|---|
| 1 | 3,645 tps | 0.27 ms | 20% |
| 8 | 8,878 tps | 0.90 ms | 49% |
| 48 | 18,039 tps | 2.66 ms | 100% |
| 128 | 14,587 tps | 8.78 ms | 81% |
| 256 | 12,216 tps | 20.96 ms | 68% |
| 400 | 10,992 tps | 36.39 ms | 61% |
Notice which column punishes you first. Between 48 and 400 connections throughput fell by a bit over a third, which you might not even notice on a dashboard. Latency in the same span went up **13.3×**, which every user notices immediately.
The Universal Scalability Law describes this well. Fitted to the measured points it lands at R² = 0.94 and predicts the optimum at 45.1 connections, against a measured peak of 48:
```
X(N) = λN / (1 + σ(N−1) + κN(N−1))
N* = √((1 − σ) / κ)
λ = 1,952 σ = 0.0739 κ = 0.000456
```
One honest caveat about that fit. Its λ works out to 1,952 transactions per second for a single connection, but a single connection actually measured 3,645. USL does not describe the very-low-concurrency region well here. I tried anchoring λ to the measured single-connection number and refitting the other two parameters, and the fit got worse — R² dropped to 0.75. So the curve above is the free fit, and you should trust it in the region that matters rather than at N = 1.
## Why does a bigger pool make the database slower?
Because a connection is a process, not a handle. PostgreSQL forks a backend for every connection, and when more backends are runnable than there are cores, the kernel starts round-robining them. You pay for context switches, for the lock contention that comes from more transactions overlapping, and for the cache pressure of more working sets fighting over the same L3.
None of that shows up as an error. The database keeps answering; it just answers less per second and takes longer to do it. That is why the reflex fix survives — nothing breaks loudly enough to point at the pool.
Little's Law explains the latency side in one line. Concurrency equals throughput multiplied by response time, so if you hold 400 requests in flight against a system that can only complete 11,000 per second, response time has to be 36 ms. Adding connections does not add capacity. It adds queue.
## What about the (cores × 2) + spindles formula?
For this machine it gives 9 connections. The measured optimum was 48, more than five times higher.
The formula is not wrong so much as narrow. It assumes a connection is burning CPU for its entire life, which is true for a tight in-memory query and false for almost everything else. A transaction that waits on a WAL flush, on the network, or on a lock leaves its core free for another backend, so you need more connections in flight to keep the same number of cores busy. The `effective_spindle_count` term is meant to capture exactly that, and on modern storage nobody knows what number to put in it.
Treat the formula as a floor rather than an answer. It tells you that 400 is absurd. It does not tell you whether the right number is 20 or 60, and the gap between those two is worth measuring.
## Does the durability setting move the peak?
No — it raises the ceiling and leaves the peak where it was. I expected the opposite, so this one is worth reporting as a negative result.
My reasoning was that if part of each transaction is spent waiting on a WAL flush, then removing that wait should make connections more CPU-bound and pull the optimum down toward the formula's 9. So I re-ran the sweep with `synchronous_commit = off`, three repetitions per point.
Throughput went up roughly 10–20% at every connection count. The peak did not move meaningfully: with `synchronous_commit = on` the best median was at 32 connections, with it off the curve was essentially flat from 24 to 64. Run-to-run variance was ±10–15%, which is the same size as the effect I was looking for, so the correct conclusion is that this experiment does not support my hypothesis rather than that it refutes it.
The practical takeaway survives either way. Transaction duration sets how high the curve goes; contention sets where it turns over. Tuning durability makes each transaction faster without changing how many of them should be in flight.
## The measurement trap that cost me a curve
My first sweep was read-only, and it was measuring my own load generator.
I ran `pgbench -S` and got a beautiful curve peaking at 16 connections with 162,000 transactions per second. Then I re-ran a single point with more CPU allocated to the client container: 5 CPUs gave 129,000 tps, 8 CPUs gave 159,000. The client was the bottleneck, so the "peak" was the point where pgbench ran out of CPU, not where PostgreSQL did.
> ⚠️ **Watch out:** if your load generator shares CPU with the database, or is simply too small, you will measure the generator. Always re-run one point with more client resources and confirm the number does not move.
The read-write workload passed that check. At 16 connections, 3 client CPUs gave 13,425 tps and 5 CPUs gave 14,461; at 48 connections the smaller client actually scored slightly higher, 16,597 against 15,666. Both differences sit inside the noise, so the read-write numbers reflect the database. Everything in this article comes from that workload.
## How to size yours
Stop reading connection count and start reading queue depth. The number that tells you whether the pool is too small is how many callers are waiting for a connection, and every pooler exposes it.
In PgBouncer, `SHOW POOLS` gives you `cl_waiting`. Consistently above zero means clients are queuing for a server connection and the pool has room to grow. Consistently zero while the database is not saturated means the pool is already big enough, and adding to it moves you rightward along the curve for nothing. In HikariCP the equivalent is the pending-threads gauge.
Then work backwards to the total. Your database sees instances × pool size, not pool size, and that multiplication is where most incidents start: twenty pods with a pool of twenty is four hundred connections, which is exactly the far end of the measurement above. Autoscaling makes it worse, because the connection count scales with your traffic spike at the precise moment the database can least afford it.
Transaction pooling breaks that link. PgBouncer in `pool_mode = transaction` assigns a server connection only for the duration of a transaction, so four hundred clients can share twenty backends. The same logic is why AWS put RDS Proxy in front of Lambda: a function that scales to hundreds of concurrent executions opens hundreds of connections, a `db.t3.medium` tops out near a hundred, and pooling inside the function does not help because every new execution environment builds its own pool.
## How I measured this
PostgreSQL 17.11 in Docker, limited to 4 CPUs, with `shared_buffers=1GB` and `max_connections=400`. Data set is `pgbench -i -s 50`, which is 5 million rows and 755 MB — small enough to sit in shared buffers, so the curve reflects CPU and lock contention rather than disk.
```bash
docker run -d --name pgl-db --cpus=4 \
-e POSTGRES_HOST_AUTH_METHOD=trust -e POSTGRES_DB=bench \
postgres:17 -c max_connections=400 -c shared_buffers=1GB
docker exec pgl-db pgbench -i -s 50 -q -U postgres bench
# client in its OWN container so it does not steal the database's cores
for c in 1 2 4 8 16 32 48 64 128 256; do
docker run --rm --network pgl --cpus=5 postgres:17 \
pgbench -h pgl-db -U postgres -d bench -c $c -j 5 -T 10 -n
done
```
The full sweep ran 1 → 256 in fifteen steps; the headline points were re-run three times each and the median reported. Latency is pgbench's own average, which is end-to-end and therefore includes queueing.
Three limits worth stating. This is one workload on one machine, and pgbench's TPC-B-like transaction is write-heavy in a way your application may not be — the shape generalises, the numbers do not. Docker Desktop on macOS adds real variance, measured at ±10–15% between identical runs, so treat any difference smaller than that as nothing. And the peak location depends on core count, transaction duration and lock profile, which is precisely why the [simulator](/simulators/connection-pool) lets you move those three rather than quoting you a single number.
## FAQ
### How many connections should my pool have?
Fewer than you think, and the only reliable way to find out is to sweep it. On the 4-core PostgreSQL instance measured here the optimum was 48 connections; the widely quoted `(cores × 2) + spindles` formula predicted 9. Start from the formula as a floor, measure your own curve, and size to the peak rather than to the maximum.
### Why does adding connections make PostgreSQL slower?
Each connection is a backend process. Once more backends are runnable than you have cores, they take turns instead of running in parallel, and you pay for context switching, lock contention and cache pressure. Measured here, going from 48 to 400 connections cost 37% of throughput and multiplied average latency by 13.3.
### What causes "sorry, too many clients already"?
Your applications opened more connections than `max_connections` allows. It is almost always a multiplication problem rather than one greedy service: instances times pool size. Twenty pods with a pool of twenty is four hundred connections, and autoscaling raises that number exactly when traffic spikes.
### Does PgBouncer fix connection exhaustion?
In `pool_mode = transaction` it does, because a server connection is assigned only for the duration of a transaction rather than the life of a client session. Hundreds of clients can then share a few dozen backends. Session pooling does not help with exhaustion, since it holds a server connection for as long as the client is connected.
### Should I use RDS Proxy with Lambda?
Yes, if the function talks to a relational database with any real concurrency. Lambda scales to hundreds of simultaneous executions and each execution environment opens its own connection, while a small RDS instance allows around a hundred. Pooling inside the function does not help, because a new environment starts with an empty pool.
### What metric tells me the pool is too small?
Queue depth, not connection count or CPU. `cl_waiting` in PgBouncer's `SHOW POOLS`, or the pending-threads gauge in HikariCP. If it is consistently zero and the database is not saturated, the pool is already large enough and growing it will only cost latency.
## What I would tell my past self
The instinct that a bigger pool means more capacity comes from thinking of connections as permission slips. They are not. They are processes, and handing out more of them than the machine can run is how you turn a fast database into a queue with a fast database at the end of it.
The number that matters is not in your pool config. It is the peak of a curve you have not plotted yet — and plotting it takes about ten minutes with pgbench and a spare container.
---
## The Subagent Tax, Measured: 23,747 Turns of Real Billing Data
Author: Serdarcan Büyükdereli
Date: 2026-08-19
Category: DevOps Blog
URL: https://theinfinity.dev/articles/subagent-cost-measured
Across 34 days of my own agent work — 345 transcripts, 23,747 billed turns, $5,435 at list pricing — the subagents I spawned accounted for 12.8% of the turns and **4.6% of the bill**. A subagent turn cost $0.082. A main-loop turn cost $0.250. Delegating was three times cheaper per turn.
That is the opposite of what the internet says. The circulating number is a tax: one widely shared write-up measured a fan-out at 5.9× the tokens of doing the same job directly, another put it at 4.2×, a third at roughly 7×. There are stories of a 23-subagent run that burned $47,000.
Both sets of numbers are real. I reproduced the mechanism behind the tax in my own data, and it is not a property of subagents at all. When I hold context size and output length constant, a subagent turn costs **the same** as a main-loop turn — the ratio lands between 0.86 and 1.07 depending on the bucket. There is no delegation discount. There is no delegation penalty either.
What there is: a turn costs what it carries. Delegation is cheap when the delegate carries less, and ruinous when you hand the same heavy context to five agents at once. The agent count never enters the equation.
## What the split actually looks like
Subagents were an eighth of my turns and a twentieth of my spend. The gap is not a discount — it is the size of what each turn carried.
| | cost | share of bill | turns | $/turn | avg context | avg output |
|---|---|---|---|---|---|---|
| Main loop | $5,187 | 95.4% | 20,716 | $0.250 | 357,459 | 1,177 |
| Subagent | $248 | 4.6% | 3,031 | $0.082 | 102,936 | 90 |
Two ratios explain the third. Subagent turns carried 3.5× less context and produced 13× less output. Multiply those through the price sheet and $0.082 is roughly what you would predict.
The five most expensive sessions in the window cost $648, $549, $360, $304 and $257. Every one of them was pure main loop, zero delegation. The $648 session ran 2,167 turns in a single conversation. Nothing I delegated came close.
## Is a subagent turn actually cheaper?
No. At the same context size and the same output length, a subagent turn costs what a main-loop turn costs. The apparent discount disappears entirely once you control for both.
Here is the same data bucketed by context size, restricted to turns that emitted fewer than 200 output tokens so that output length stops confounding the comparison:
| context in the turn | main loop $/turn | subagent $/turn | ratio |
|---|---|---|---|
| 50–100k | $0.061 | $0.066 | 1.07 |
| 100–150k | $0.086 | $0.074 | 0.86 |
| 150–200k | $0.113 | $0.108 | 0.95 |
| 200–250k | $0.131 | $0.135 | 1.03 |
That is noise around 1.0. Two of the four buckets have the subagent costing slightly *more*, which makes sense — subagents get less benefit from prompt caching. Their cache-read share was 93.0% against the main loop's 98.0%, because a fresh agent has to write its cache before it can read it.
So the model does not know or care that a turn belongs to a subagent. It bills a prompt. The prompt is the whole story, which is the same conclusion I reached [measuring 23,968 turns of prompt-to-output ratio](/articles/agent-token-cost-measured) and again [measuring what a memory retrieval puts into the context window](/articles/agent-memory-measured). Three different questions, one answer.
## Then why was my subagent bill only 4.6%?
Because a subagent starts from nothing. It does not inherit the conversation that spawned it, so it never pays for the 350,000 tokens of history sitting in the parent session.
My main loop averaged 357,459 tokens of context per turn. My subagents averaged 102,936. That is not a tuning choice, it is structural: the parent hands over a task description, not a transcript. Everything the main loop accumulated — the files it read, the commands it ran, the dead ends it backed out of — stays behind.
The output side compounds it. Main-loop turns averaged 1,177 output tokens; subagent turns averaged 90. A subagent that searches four directories and reports one file path emits almost nothing. At $25 per million output tokens, 1,177 tokens is $0.029 and 90 tokens is $0.002, and that difference alone is a third of the per-turn gap.
> ⚠️ **Watch out:** these two effects are properties of *how you delegate*, not of delegation. A subagent handed the full conversation and asked to write a long report has neither advantage, and will cost exactly what the main loop would have cost.
## What is the "subagent tax" measuring, then?
It is measuring fan-out, which multiplies context instead of dividing it. Both numbers are correct because they describe opposite shapes of the same mechanism.
When you fan out to five agents on one task, each of them loads a system prompt, a tool set, and enough of the problem to be useful. The published breakdown of a 4.2× case is explicit about this: each subagent re-read a 38,000 to 69,000 token prefix, five times over, and paid for its own baseline on every turn. Nothing was shared. That is five agents each carrying a mid-sized context where one agent carried one.
When you delegate a narrow lookup out of a 300,000-token conversation, the arithmetic runs backwards. One agent carries a small context where the alternative was one agent carrying a huge one.
Same mechanism, opposite sign. The variable that moved was never the number of agents.
## When does delegating actually pay?
It depends almost entirely on how big your main conversation already is. Below about 100k tokens of context, delegation only pays for tasks that take six or more turns. Above 250k, it pays from the first turn.
Spawning is not free. A subagent's first turn cost $0.188 in my data — 2.3× its own average — because it writes about 34,000 tokens of cache before it can read any. That fixed cost has to be earned back.
Setting spawn at $0.188, each additional subagent turn at $0.082, and comparing against a main-loop turn at the measured rate for each context band:
| your current context | inline $/turn | delegation breaks even at | verdict |
|---|---|---|---|
| 50–100k | $0.101 | 5.6 turns | only for long tasks |
| 100–150k | $0.118 | 2.9 turns | 3+ turn tasks |
| 150–200k | $0.139 | 1.9 turns | 2+ turn tasks |
| 200–250k | $0.167 | 1.2 turns | almost always |
| 250–300k | $0.199 | 0.9 turns | immediately |

Take a five-turn research task. At 50–100k of context it costs $0.51 inline and $0.52 delegated — a wash. At 250–300k it costs $1.00 inline and $0.52 delegated, so delegation is 48% cheaper.
This table is generous to the inline option, in two ways. It assumes your context stays flat while you do the work, when in reality the files you read and the output you produce all land in the conversation and inflate every turn that follows. And it ignores that the inline work permanently raises the floor for the rest of the session. Delegated work leaves no trace in the parent.
## What this means for how you delegate
Delegate to shed context, not to add parallelism. The saving comes from what the delegate does not carry, so anything that fattens the subagent's prompt eats the benefit directly.
Three practical consequences fall out of the numbers.
Delegate late, not early. At 60k of context there is almost nothing to save; at 300k there is half the bill. The same task delegated at two different points in a session has completely different economics.
Keep the brief short and the report shorter. Output cost me 13× more per main-loop turn than per subagent turn, and that gap is most of the advantage. A subagent asked to return a 2,000-token summary has spent the saving before it starts.
Do not fan out to save money — fan out for latency or independence, and price it as a cost. Five agents on one task is five baselines. If they each need the same large context, you have found the expensive case, and the 4× to 6× figures in circulation are what you should expect.
## How I measured this
Every Claude Code session writes a JSONL transcript to `~/.claude/projects/`, and every assistant record carries a `usage` block with the real token counts — input, cache creation, cache read, and output. This is billing data, not an estimate of it.
```python
u = record["message"]["usage"]
context = u["input_tokens"] + u["cache_creation_input_tokens"] + u["cache_read_input_tokens"]
cost = (u["input_tokens"] * rate_in
+ u["cache_creation_input_tokens"] * rate_in * 1.25
+ u["cache_read_input_tokens"] * rate_in * 0.10
+ u["output_tokens"] * rate_out) / 1e6
```
Subagent turns carry `isSidechain: true`. That flag is what makes this measurable at all — without it, delegated work is indistinguishable from the rest.
Two traps cost me a first pass each. Streaming repeats the same `message.id` across several lines, so counting rows double-counts turns; deduplicate by message id. And subagents write to their own transcript files rather than into the parent's, so splitting by file gives you 165 files that are 100% subagent and tells you nothing. Split by record.
The window is 2026-07-16 to 2026-08-19: 345 transcripts, 23,747 turns, mostly Claude Opus 5 (18,967 turns) with Opus 4.8, Sonnet 5 and Fable 5 making up the rest. Costs use list pricing with the standard 1.25× cache-write and 0.10× cache-read multipliers.
Transcripts roll off after about a month, so this is a moving window rather than a fixed archive. That is why the totals here differ slightly from the 23,968 turns I reported three days earlier — different snapshot, same machine.
Three limits worth stating. This is one developer's usage pattern, not a benchmark — my delegation habits shaped the context sizes, and yours will differ. Because subagents live in separate files, I cannot attribute a subagent back to the session that spawned it, so there is no per-session delegation ratio here. And the breakeven table is built from bucket averages, so treat it as a shape rather than a quote.
## FAQ
### Are subagents more expensive than doing the work inline?
Not per turn. Measured across 23,747 turns, a subagent turn cost $0.082 against a main-loop turn at $0.250. But that gap comes from subagents carrying 3.5× less context and emitting 13× less output — at equal context and output the two cost the same, within noise.
### What is the subagent tax?
It is the cost of fan-out, where several agents each load their own baseline context for one task. Published measurements put it at 4.2× to 5.9× the tokens of doing the job directly. It is real, and it applies when you parallelize; it does not apply when you delegate a narrow task out of a large conversation.
### How much does spawning a subagent cost?
About $0.188 in my data, which is 2.3× a subagent's average turn. The first turn writes roughly 34,000 tokens of prompt cache before anything can be read back cheaply. That fixed cost is why short delegations from a small conversation do not pay.
### When should I delegate instead of continuing inline?
When your main conversation is already large. Below 100k tokens of context, delegation only wins on tasks of six turns or more. Above 250k it wins immediately, because a single inline turn at that size costs more than spawning an agent and running it once.
### Does prompt caching make subagents cheaper?
The opposite, slightly. Subagent turns had a 93.0% cache-read share against the main loop's 98.0%, because a fresh agent must write its cache before it can read it. Caching favors the long-running conversation, which is the one you were trying to escape.
### Do more subagents mean a bigger bill?
Not by themselves. The count of agents does not appear anywhere in the pricing; the context each turn carries does. Five agents with small contexts can cost less than one agent with a huge one, and five agents with large contexts will cost about five times as much.
## The part I did not expect
I went in expecting to confirm the tax and instead found that agent architecture is a red herring. Single agent, subagent, fan-out, orchestrator — none of it appears on the invoice. What appears is a list of prompts and how big each one was.
That reframes the question people usually ask. "Should I use subagents?" has no cost answer. "How much context does this turn need to carry?" has one, and it is the same question whether the turn belongs to an agent, a subagent, or you.
If you want to see the shape of it before you touch your own transcripts, the [agent trace cost simulator](/simulators/agent-trace-cost) walks a single agent through a task and shows the prompt growing underneath it. Delegation is what happens when you refuse to let that line keep climbing.
---
## Agent Memory, Measured: 3M Tokens on Disk, 550 in the Prompt
Author: Serdarcan Büyükdereli
Date: 2026-08-18
Category: DevOps Blog
URL: https://theinfinity.dev/articles/agent-memory-measured
My agent has about three million tokens of knowledge available to it. A typical question puts **550 of them into the prompt**, and takes 63 milliseconds to do it. There is no vector database anywhere in that path — it is a folder of markdown files, a SQLite index, and a rule about what to read first.
I went looking for numbers to compare that against and could not find any. Search for agent memory and you get comparison posts: eight frameworks ranked, Mem0 versus Zep versus Letta versus Cognee, dimension tables, verdicts. The token figures inside them come from the vendors themselves, and they are mostly aimed at each other — one publishes a critique claiming a competitor burns 600,000 tokens per conversation against its own 1,800.
Those might all be true. The problem is that none of them is a measurement you can reproduce, and none of them tells you the thing you actually need to know, which is not *which system is best* but **how many tokens one retrieval puts in your prompt.** That number is measurable on any setup, including one with no vendor in it at all. Here is mine.
## Why the retrieval number is the only one that matters
I measured [23,968 real agent turns](/articles/agent-token-cost-measured) recently and the headline was that prompt tokens outnumbered output tokens 309 to 1. The agents wrote 27 million tokens and read 8.39 billion.
If that ratio is even roughly right for your workload — and it is a property of how agent loops work, not of any particular tool — then almost your entire bill is decided by what goes *into* the prompt. Output is a rounding error. Model choice matters less than people think. What matters is retrieval discipline: when the agent needs to know something, how much does it drag in?
That reframes memory from a storage problem into a **context budget** problem. Storage is cheap and getting cheaper. Context is the expensive, scarce, quadratically-billed resource. A memory system's job is not to hold a lot; it is to hand over a little.
## What I actually built
No framework. The whole thing is:
- A folder of markdown files — notes per customer, per project, per incident
- A CLI that mutates them atomically and keeps an audit log
- A SQLite database with an FTS5 full-text index over everything
- A generated one-page **digest** per subject
- A written rule about the order you're allowed to read things in
That last one is the part people skip, and it is the part that does the work.
## The numbers
Measured on my own vault, today. Byte counts are exact; token figures are the standard characters-divided-by-four estimate, and my content is a mix of English and Turkish technical prose, which tokenizes *worse* than plain English — so the real corpus numbers are somewhat higher than shown, which only sharpens the point.
| | |
|---|---|
| Markdown files | 861 |
| Corpus | 12,056,439 bytes (~3.0M tokens) |
| SQLite + FTS index | 137,908,224 bytes |
| Index size vs corpus | **11.4×** |
| Median digest | ~549 tokens |
| Typical search result | ~490–630 tokens |
| Search latency | **63 ms** |
The index is over eleven times larger than the thing it indexes. On a storage-shaped mental model that looks like a problem. It is not, and understanding why is most of the point of this article: **the index never enters the prompt.** It lives on disk, gets consulted in 63 milliseconds, and returns half a kilobyte of text. Disk is cheap. Context is not. Spending 138 MB of disk to avoid spending 20,000 tokens of context is a trade you should take every single time.
### What summarising actually buys
The subject-level digests are the sharpest measurement I have. Across 21 subjects with 337 underlying files:
| | |
|---|---|
| Raw source material | 8,048,814 bytes |
| Generated digests | 61,326 bytes |
| Compression | **131×** |
| Most extreme case | 2.45 MB → 3.7 KB (**652×**) |
That 652× case is a subject with 63 files of accumulated history. When the agent needs to know the current state of it, reading the folder would cost roughly 600,000 tokens. Reading the digest costs about 940. Both answer the question. Only one of them is affordable, and only one of them leaves room in the context window to actually do the work afterwards.
## The rule that does the work
Having the index is not the mechanism. The mechanism is a written retrieval order that both I and the agent follow, with a hard instruction to **stop as soon as the question is answered**:
1. **Unsure which subject?** Run a finder query. It returns pointers and snippets, not documents.
2. **Exact token — a ticket ID, an IP, a domain, a hostname?** Full-text search. It goes straight to the line.
3. **Need current state of a subject?** Read the digest. About 550 tokens.
4. **Need one specific part?** Read that section by name, not the file.
5. **Still missing something?** *Then* open the single document the digest pointed at.
And an explicit list of things that are forbidden because they are token sinks:
- Reading raw chronological logs
- Reading an entire subject folder
- Handing a full document to the model when a section would do
- Reading anything *else* "to be sure" after the answer was already found
- Any unfiltered bulk scan
That last one is the most common failure in practice, and the most human. The agent finds the answer, then reads three more files to feel confident. Each of those is a permanent addition to the context for the rest of the session — and per the 309:1 measurement, everything you add gets re-sent on every subsequent turn. Confidence-reading is the single most expensive habit an agent can have.
## Where this approach is genuinely worse
I am not claiming a folder of markdown beats a purpose-built memory platform. Some honest limits:
**There are no embeddings.** Search is lexical — FTS5, not semantic. Ask for "the thing where the disk filled up" and it will miss a note that says "volume exhausted". A vector store handles that; this does not. I deferred embeddings deliberately, because lexical search turned out to answer the overwhelming majority of real questions — most of what I look up is an identifier, and identifiers are exact strings.
**Digests are generated, so they go stale.** A digest is only as good as its last regeneration. A system that updates memory continuously as the agent works does not have this problem.
**It is single-user and local.** No multi-tenant story, no shared team memory, no hosted anything. That is a feature for me and a blocker for a product.
**Nothing here is novel.** Files, a full-text index, and a summary. The interesting part is not the architecture, it is that the numbers are good enough that the architecture stops mattering.
## What to measure in your own setup
Whatever you are using — a framework, a vector store, a folder like mine — these four numbers tell you almost everything, and none of them requires a vendor's cooperation:
**Tokens per retrieval.** Take a normal question, capture what your memory layer hands the model, count it. If it is in the thousands, that cost is paid again on every subsequent turn of that session.
**Corpus-to-retrieval ratio.** Mine is roughly 3,000,000 to 550. The absolute size of the corpus should be nearly irrelevant to the cost of one question. If growing your knowledge base makes each question more expensive, retrieval is not doing its job.
**Prompt-to-output ratio over a whole session.** Mine measured 309:1. This is the number that tells you whether you have a retrieval problem at all — a high ratio means the agent is carrying history rather than doing work.
**Retrieval latency.** Mine is 63 ms, which is far below the threshold where anyone would notice. If yours is in the hundreds of milliseconds, you are paying real time on every step of every loop.
## FAQ
### How many tokens should an agent memory retrieval use?
Few hundred rather than few thousand. In this measured setup the median subject digest is about 550 tokens and a typical full-text search result is 490–630. The reason the ceiling matters is compounding: an agent turn resends the whole conversation, so anything retrieval adds is billed again on every following turn of the session.
### Do I need a vector database for agent memory?
Not necessarily, and it is worth measuring before assuming. Lexical full-text search answered the large majority of real questions in this setup, because most lookups are exact identifiers — ticket numbers, IP addresses, hostnames, domains. Embeddings earn their place when you need to match meaning rather than strings; the honest failure mode of a lexical index is that "the disk filled up" will not find a note that says "volume exhausted".
### Why is the search index larger than the data it indexes?
Because a full-text index stores tokens and their positions in addition to the source text, so a multiple of the corpus size is normal. It does not matter, because the index lives on disk and is never sent to the model. In this setup the index is 11.4× the corpus at 138 MB, and it returns roughly 550 tokens per query in 63 ms. Disk is cheap; context is not.
### What is the difference between RAG and agent memory?
In practice they are the same mechanism aimed at different content: RAG usually retrieves from a fixed document corpus to answer a question, while agent memory retrieves from knowledge that the agent itself accumulated and keeps updating. The cost question is identical for both — how many tokens does one retrieval put into the prompt — which is why it is worth measuring the same way regardless of which word you use for it.
### How do I stop an agent from reading too much context?
Write an explicit retrieval order, tell it to stop as soon as the question is answered, and name the forbidden operations — reading whole folders, reading raw logs, passing a full document where a section would do, and reading extra files "to be sure" after the answer was already found. That last one is the most common and most expensive, because everything added to context is re-sent on every later turn.
### Does compressing knowledge into summaries lose information?
Yes, and that is the trade being made deliberately. A digest that compresses 2.45 MB to 3.7 KB is discarding almost everything, and it works because the discarded part is history the agent does not need to answer the current question. The safeguard is that the digest carries pointers, so when detail is genuinely required the agent opens exactly one source document instead of the whole folder.
## The thing I got wrong first
I built the index before I wrote the rule, and for a while it changed nothing. The agent had full-text search available and kept reading whole files anyway, because nothing told it not to and reading more feels safer than reading less.
The retrieval order was the actual fix, and it is fifteen lines of plain text. The index made a cheap path *possible*; the written rule made it the *default*. If you take one thing from this, take that ordering — a retrieval mechanism nobody is required to use is a mechanism that will not be used.
That is the same shape as something I ran into [auditing my agents' guardrails](/articles/ai-agent-guardrails-audit), where five of seven rules turned out to exist only as documentation while the thing meant to enforce them had never been wired up. Writing the capability and making it the default path are two separate pieces of work, and finishing the first one feels almost exactly like finishing both.
---
## I Measured 23,968 Agent Turns. The Prompt Was 309× the Output.
Author: Serdarcan Büyükdereli
Date: 2026-08-16
Category: DevOps Blog
URL: https://theinfinity.dev/articles/agent-token-cost-measured
Across 166 real agent sessions I have run — 23,968 billed turns, $5,816 of actual spend — the agents wrote 27.2 million tokens and read 8.39 billion. That is a ratio of **309 to 1**. For every token these agents produced, 309 went back into the model.
That number is the whole story of agent cost, and it is invisible in every pricing page, because pricing pages quote a rate per million tokens and leave you to assume the token count has something to do with the work being done. It mostly does not. It has to do with how many times the conversation gets resent.
I had been treating agent spend as a black box — a number on an invoice that went up when I used it more. This is what came out when I actually looked.
## What is being measured here
Every turn an agent takes produces a `usage` block from the API: how many tokens were sent, how many were read from cache, how many were written to cache, how many the model generated. That is not an estimate. It is the billing record.
Those blocks are sitting in the session transcripts on disk. I parsed every session with 20 or more turns and priced each one at published rates — $5 per million input tokens, $25 per million output, cache writes at 1.25×, cache reads at 0.1×.
| | |
|---|---|
| Sessions | 166 |
| Billed assistant turns | 23,968 |
| Prompt tokens | 8,393,529,951 |
| Output tokens | 27,191,091 |
| Measured spend | $5,816.28 |
| Same work with no caching | $42,649.61 |
Two caveats worth stating up front. This is one engineer's workload — coding and infrastructure tasks, long sessions, heavy file reading — so the absolute numbers are mine; the shape of the curve is a property of how the API works, and that part generalises. And the sessions span four models, priced here at a single Opus-tier rate: 95% of the turns are Opus-tier already, with small tails of a more expensive model and a cheaper one that roughly cancel, so the blended error is on the order of a couple of percent. Nothing below turns on it.
## Why does turn 40 cost more than turn 4?
Because the API is stateless. There is no conversation stored on the server that you append to. Every turn resends everything: the system prompt, the tool definitions, every file the agent read, every command output, every error message, all of it, every single time.
So when an agent writes 300 tokens on turn 40, those 300 tokens ride on top of a prompt containing all 39 previous turns. The work is 300 tokens. The bill is for a quarter of a million.
This makes turn cost an increasing sequence rather than a constant, and it makes total cost grow with roughly the square of the step count. Here is the measured growth in prompt size, taking the median across all 166 sessions at each turn index:
| Turn | Median prompt | Median cost that turn |
|---|---|---|
| 1 | 56,542 | $0.3519 |
| 2 | 61,892 | $0.0743 |
| 10 | 81,468 | $0.0654 |
| 50 | 171,289 | $0.1174 |
| 100 | 258,856 | $0.1668 |
The context grows by a median of 1,368 tokens per turn — the mean is 2,071, and the spread is wide, from 411 at the tenth percentile to 4,089 at the ninetieth.
Turn 1 deserves a note, because it looks alarming and is not. It is the most expensive single turn in almost every session, six and a half times the cost of turn 3. That is not work; that is the cache being written. You pay a 25% premium once to store the prefix, then read it back at a tenth of the price for the rest of the session. It is the best money you spend all run.
## What does turn position actually cost?
Growing prompts are intuitive. What surprised me was how much the *same* turn costs depending on where it lands.
To isolate this I took only turns where the model produced between 200 and 1,000 tokens — comparable units of work — and bucketed them by position:
| Turn position | Turns measured | Median cost | vs. the first bucket |
|---|---|---|---|
| 0–9 | 603 | $0.0625 | 1.00× |
| 50–59 | 334 | $0.1089 | 1.74× |
| 100–109 | 250 | $0.1513 | 2.42× |
| 150–159 | 136 | $0.2055 | 3.29× |
| 190–199 | 112 | $0.2372 | 3.80× |
Identical work. Nearly four times the price, purely for arriving late.
This reframes a question I had been asking wrong. I used to ask what a task costs. The real question is what a task costs *at the point in the session where it happens* — and the practical consequence is that the order you do things in has a price. Front-loading the expensive reads, or answering the cheap questions before the context has grown, is not premature optimisation. It is measurable.
## What does a loop actually cost?
This is where I had to correct myself, because the obvious answer turned out to be wrong.
I flagged every session where the same tool call — same tool, same arguments — appeared three or more times. That is 79 of 166 sessions, 2,761 turns, $656 of spend. My assumption was that these turns would be individually expensive, and that the flagged spend would be disproportionate.
It is not. Repeated turns are 11.5% of all turns and 11.3% of all spend. Measured against the average turn in their own session, they cost **0.86×** — a repeated tool call is slightly *cheaper* than the turns around it, because rerunning a command produces less output than reasoning does.
So loops are not expensive because their turns are expensive. Loops are expensive for two other reasons, and both are structural.
The first is position, which the table above already prices. Loops start in the middle or the end of a session, never at the beginning. Modelling a ten-turn loop against the measured growth curve:
| Loop starts at turn | Cost of those 10 turns | vs. starting at turn 1 |
|---|---|---|
| 1 | $0.46 | 1.00× |
| 50 | $1.04 | 2.24× |
| 100 | $1.48 | 3.18× |
| 200 | $2.42 | 5.22× |
The same ten wasted turns cost five times more at turn 200 than at turn 1.
The second reason is worse, because it outlives the loop. Every turn in a loop leaves its output in the context permanently. A failing test rerun six times does not just cost six turns — it raises the price of *every* turn after it, for the rest of the session. The context that grew does not shrink back.
Which is exactly why loops hide. Nothing in a per-turn view looks wrong. There is no expensive turn to find. The damage is distributed across every turn that follows, and the only cheap way to catch it is to count repeated calls rather than to look for a spike.
## What is prompt caching actually doing?
Carrying almost the entire load, is what.
| Where prompt tokens went | Tokens | Share |
|---|---|---|
| Read from cache | 8,229,710,597 | 98.0% |
| Written to cache | 161,840,100 | 1.9% |
| Fresh input | 1,979,254 | 0.02% |
Ninety-eight percent of everything sent was served from cache at a tenth of the price. That single mechanism is the difference between $5,816 and $42,649 — a factor of **7.3**.
It is worth being precise about what caching does and does not fix. It does not make the growth linear. Every turn still resends everything; the quadratic term is still there. Caching divides its coefficient by ten. That is an enormous win and it is not a structural fix.
The practical consequence is one most people learn the expensive way: caching is a *prefix* match. One changed byte anywhere in the prefix invalidates the cache for everything after it. Putting a timestamp at the top of a system prompt, or building the tool list in a non-deterministic order, quietly moves you from the $5,816 column to the $42,649 one. Nothing errors. The bill just stops looking the way it did.
## What does compaction look like in the data?
There were 12 events where the context collapsed. The median peak was **996,345 tokens** — essentially the 1M context window — dropping to **74,949**, a 92% cut.
That is the sawtooth. Context climbs for hundreds of turns, hits the ceiling, gets summarised, and the cost curve resets almost to the floor.
It is the single largest cost event available, and it is not free. What gets summarised is gone. If the agent needs that detail later, it has to rediscover it — which means more turns, which means more context, which means climbing the same hill again. In the longest session I measured, 2,740 turns, this happened repeatedly: the prompt climbs from roughly 90K to nearly 1M, resets, and climbs again.
That session cost $881. Without caching the same work would have been $6,859.
## What should you actually watch?
Total token count tells you almost nothing, because 98% of it is cache reads that cost a tenth of list price. A cost total tells you even less: it goes up when the agent works and up when the agent flails, and it cannot distinguish the two.
Three things are worth putting on a dashboard.
**The prompt-to-output ratio.** Mine is 309:1 in aggregate. Rising means the agent is carrying more history per unit of work — a session getting heavier rather than more productive. It is the closest thing to a single health number.
**Repeated tool calls.** The same command with the same arguments appearing a third time is the earliest reliable loop signal available, it costs nothing to compute, and it fires long before the invoice moves. This is the one I would build first.
**Cache read share.** It should sit near 98%. If it drops, something in your prefix is changing between calls, and you have quietly bought a 7× price increase.
All three live at trace level. None of them appears in a monthly total, which is precisely why the monthly total is the last place the problem shows up.
## FAQ
### Why does an AI agent cost more per turn as the conversation gets longer?
Because the model API is stateless — every turn resends the entire conversation history, not just the new message. On turn 40 the agent might write 300 tokens, but the prompt carrying them includes all 39 previous turns and is billed in full. Measured across 23,968 real turns, an identically-sized turn costs 3.8× more at position 190 than at position 5.
### How much does prompt caching actually save on agent workloads?
In this measurement, 7.3×. Across 166 sessions the measured spend was $5,816 with caching against $42,649 for the same work without it, because 98% of all prompt tokens were served from cache at a tenth of list price. Caching does not change the shape of the growth — it divides the cost of that growth by roughly ten.
### Are repeated tool calls expensive?
Not individually — that is the trap. Measured against the average turn in their own session, repeated tool calls cost 0.86×, slightly less than average, because rerunning a command produces less output than reasoning does. The cost is structural: the loop adds turns where the curve is already steep, and everything it leaves in the context inflates every turn that follows.
### What is the prompt-to-output token ratio for coding agents?
309 to 1 across this dataset — 8.39 billion prompt tokens against 27.2 million output tokens. The ratio varies by workload, but the order of magnitude is a property of how agent loops work rather than of any particular tool. Watching it move is more useful than watching its absolute value.
### Does context compaction reduce agent costs?
Dramatically, and not for free. In the measured sessions the context peaked at a median of 996,345 tokens before compaction dropped it to 74,949 — a 92% cut, and the cost curve resets with it. But summarised detail is gone, and if the agent needs it later it must rediscover it, which costs turns.
### How do I detect an AI agent stuck in a loop?
Count repeated tool calls: the same tool with the same arguments appearing three or more times in a session. It is trivial to compute from the trace, and it fires far earlier than any cost alarm, because looping turns are individually cheap. Cost-based alerting finds loops only after they have already run long enough to matter.
## The part that changed how I work
I went in expecting to find an expensive model, or an expensive tool, or one pathological session that ate the budget. There wasn't one. The spend was spread evenly across thousands of ordinary turns, each of them individually reasonable, each one carrying a slightly larger copy of everything that came before it.
The mental model I had — that a task costs what a task costs — was simply wrong. A task costs what it costs *at the point in the conversation where you do it*, and that price is still climbing while you decide.
If you want to watch that curve move under your own hands, I built [an agent trace and cost simulator](/simulators/agent-trace-cost) from these measurements: step through a trace turn by turn, add a retry loop, toggle caching off, and watch the bill separate from the number of steps.
And if the broader pattern is familiar — a system where the thing you assumed was being checked turns out not to be — it is the same shape as [auditing agent guardrails that were never actually running](/articles/ai-agent-guardrails-audit). Both come down to the same habit: measure the mechanism instead of trusting the summary.
---
## I Audited My AI Agent's Guardrails. Most of Them Weren't Running.
Author: Serdarcan Büyükdereli
Date: 2026-08-14
Category: DevOps Blog
URL: https://theinfinity.dev/articles/ai-agent-guardrails-audit
A checker I had written to catch formatting mistakes in customer-facing messages had been running for weeks and reporting clean. When I finally tested it against the last 60 days of real messages, it turned out that 13 of 25 of them contained a total of 91 violations of the exact rule it was supposed to enforce. It had caught none of them.
The checker was not broken. It looked for `**bold**`, the Markdown syntax. The messages were going into a system that uses `*bold*`, the wiki syntax. The rule was written down, the enforcement was real code, and the two had never actually met.
That was one finding in an audit of my own agent setup. Seven findings came out of it, and **five were the same shape**: a rule existed, and the mechanism that was supposed to enforce it either had never been wired up or did not work the way the documentation claimed. Everything looked green. Nothing was failing loudly. The rules were simply not running.
This is a write-up of those failure modes, because every one of them is silent by design, and because "I wrote it in the config file" is the most common way engineers convince themselves an agent is constrained.
## Why is a rule in a config file not a guardrail?
Because the model decides whether to follow it. Instructions in `CLAUDE.md`, `AGENTS.md` or any equivalent are delivered as context, and context is something an LLM weighs against everything else in the prompt — not a constraint it is structurally unable to violate.
Anthropic's own documentation is explicit that these files are advisory. The practical consequences show up fast: a long instruction file loses its middle to the lost-in-the-middle effect, a rule that looks irrelevant to the current task gets skipped, and a rule that conflicts with a more recent instruction quietly loses.
There is a hard line between two categories, and most setups blur it:
| | Advisory | Deterministic |
|---|---|---|
| Examples | `CLAUDE.md`, steering docs, skill instructions | `PreToolUse` hooks, CI checks, pre-commit, wrapper scripts |
| Who executes it | The model, by choice | The harness, as code |
| Fails how | Silently, by omission | Loudly, with an exit code |
| Right for | Tone, preferences, defaults, taste | Anything that must hold every time |
Neither is better. The mistake is putting a must-hold rule in the advisory column and then believing it is enforced. "Never write a credential in plain text" is not a preference. It belongs in code that can say no.
## What does a silent failure actually look like?
It looks like success. That is the whole problem — every one of these returns exit code 0, prints nothing, and leaves no trace in a log you would think to read.
Here are the four that cost me the most time, each verified by breaking it on purpose.
### `set -e` turns a guard into a pass-through
This is the one I would put on a poster. Standard shell advice is to start every script with `set -euo pipefail`. In a guard script, the `-e` is actively harmful:
```bash
#!/usr/bin/env bash
set -euo pipefail # ← the bug
payload=$(cat)
echo "$payload" | grep -q "FORBIDDEN_PATTERN" # no match → exit 1 → script dies here
echo '{"decision":"block"}' # never runs
```
`grep` exits non-zero when it finds nothing. With `-e`, the script terminates at that line. It never reaches its blocking logic, it returns a non-error status to the harness, and the action it was supposed to stop goes through. **The guard fails open, and it fails open specifically on the input it was written to inspect.**
The same trap applies to any command that legitimately returns non-zero — `jq` on malformed input, `diff` when files differ, `test` when a condition is false. My guards now start with `set -u` or `set -uo pipefail` and handle errors explicitly:
```bash
$ for h in ~/.claude/hooks/*.sh; do
printf "%-28s %s\n" "$(basename $h)" "$(grep -m1 '^set ' $h)"
done
dangerous-cmd-guard.sh set -uo pipefail
secret-guard.sh set -u
terminology-guard.sh set -u
flag-detector.sh set -euo pipefail
```
The last one keeps `-e` deliberately: it injects context rather than blocking anything, so dying early is safe. The distinction is the point — `-e` is right for scripts that produce, wrong for scripts that police.
### A hook file in the wrong format is inert
Hook configuration that relies on a plugin-scoped variable only resolves while that plugin is installed. Uninstall the plugin and the file stays on disk, looking exactly as correct as it did before, while nothing it declares ever fires again.
There is no warning for this. The file is valid, the syntax is right, the paths look sane. It simply never runs. The only reliable check is to trigger the hook and confirm it did something.
### A field name that shifts between versions
A prompt-submit hook that reads the wrong JSON field gets an empty string, does nothing with it, and exits successfully. In my case the field was `prompt_text` while the script was reading `user_prompt`. No error, no output, no hook.
The defensive form costs nothing:
```bash
prompt=$(jq -r '.prompt_text // .prompt // .user_prompt // empty')
```
### Discovery rules are not symmetrical
I moved a folder of unused agents into an `_archive/` subdirectory, assuming it would take them out of circulation. It did not — agent discovery walks the tree recursively, so they were all still loaded. Skill discovery, in the same setup, looks exactly one level deep and *does* respect the same move.
Two similar-looking mechanisms, two different traversal rules, one wrong assumption. The archive had to move outside the scanned tree entirely.
## How do you find these before they cost you?
Try to break each rule and watch what happens. This sounds obvious and almost nobody does it, because writing the rule feels like completing the task.
The audit that produced these findings was not clever. For each rule I asked one question — *what input should this reject?* — and then fed it that input. Five of seven rules accepted it.
That question generalises well:
- For a formatting checker: give it a document that violates the rule. Does it exit non-zero?
- For a secret guard: try to write a fake credential. Does it block?
- For a dangerous-command guard: run the dangerous command in a harmless form. Does it stop?
- For a context injector: send the trigger and inspect what actually reached the model.
- For a rule file: check that the tool loads it at all, in that specific tool.
That last one caught the most embarrassing finding of the audit. My rule-precedence document — the file that decides which rule wins when two conflict — was being loaded in exactly one of the three tools I use. In the other two it had never been in context. The document explaining how rules apply was itself not applying.
## What does a guardrail test suite look like?
A plain script that exercises every enforcement point and prints one line per check. Mine runs 71 of them and takes a few seconds:
```
== Kiro hooks
OK kiro-guards.json is valid JSON
OK terminology-guard is wired
OK secret-guard is wired
OK dangerous-cmd-guard is wired
OK flag-detector is wired
OK dangerous-cmd-guard writes its reason to STDERR
== MCP parity
OK aws-pricing is defined in all three tools
OK aws-docs is defined in all three tools
...
-----------------------------
OK 71 tests passed.
```
Three properties make it worth the effort.
**It tests wiring, not just existence.** Checking that a hook file exists proves nothing. The tests assert that the hook is registered for the right event, in the right tool, and that its output reaches the place that consumes it.
**It covers parity across tools.** I use three different agents against the same repository. Most of the audit findings were cases where something was correctly configured in one tool and missing in the others. Parity is invisible until you assert it.
**Every new enforcement point adds a test.** This is the rule that keeps the suite honest. When a guard is added, a test goes with it — otherwise the next silent failure comes from the same place, and you learn about it the same way you learned about the last one: by accident, weeks later.
Run it from whatever already runs on a schedule. Mine is called by a health check, and the result lands on a dashboard where a red line is visible without me looking for it.
## Does this mean instruction files are useless?
No — they are excellent at the thing they are actually for. Tone, defaults, vocabulary, house style, which library to prefer, how to structure a response: these are judgement calls, and an LLM applying judgement to them is exactly right. Trying to enforce taste with a shell script would be worse than useless.
The split I use now is simple. If violating a rule is embarrassing, it goes in the instruction file. If violating it is expensive or irreversible, it goes in code. Credentials, destructive commands, anything that reaches a customer, anything that touches production — those are code.
And when a rule graduates from advisory to enforced, the instruction file stays. The model still needs to know the rule so it does not fight the guard. The guard exists for the times the model forgets anyway.
## FAQ
### Why does Claude Code ignore CLAUDE.md sometimes?
Because `CLAUDE.md` is delivered as context, not as a constraint the model is structurally unable to violate. The model weighs it against the rest of the prompt and can judge a rule irrelevant to the current task. Long files make this worse, since content in the middle of a long context gets less attention. For anything that must hold every time, use a hook.
### What is the difference between a hook and an instruction file?
An instruction file asks the model to behave a certain way; a hook runs as code at a fixed point in the agent's loop and can block an action regardless of what the model decided. Instructions fail silently by omission. Hooks fail loudly with an exit code, which is why they are the right home for must-hold rules.
### Why should a guard script not use set -e?
Because `grep`, `jq`, `diff` and `test` all return non-zero in perfectly normal situations. With `set -e` the script exits at that point, before reaching its blocking logic, and the harness sees a script that ended without objecting. The guard fails open exactly when it matters. Use `set -u` or `set -uo pipefail` and handle errors explicitly.
### How do I know if my hook is actually firing?
Trigger it with input it should reject and confirm the action was blocked. Existence of the file proves nothing, and neither does a clean run — a hook that never fires also produces a clean run. If you cannot observe a block, you have not observed the hook.
### How often should guardrails be tested?
On every change to the enforcement layer, and on a schedule regardless. Silent failures do not announce themselves, so the gap between breaking and noticing is bounded only by how often you check. A scheduled run turns that gap from weeks into a day.
### Do I need a test suite for two hooks?
Two hooks need two tests, and they can live in a ten-line script. The value is not in the framework, it is in the habit: adding a guard and its test in the same commit. Suites that grow to 71 checks start as three.
## What to check in your own setup
Three things, in the order that finds the most problems fastest.
Grep your guard scripts for `set -e` and decide, for each one, whether early exit means fail-open. That single line is the highest-yield check in this article.
Then take each rule you believe is enforced and feed it the input it should reject. Not a review of the code — an actual run. Count how many accept it.
Then, if you use more than one agent or more than one machine, check parity. Configuration drifts in one direction: things get added where you are working and nowhere else.
The pattern underneath all seven findings was the same, and it is worth stating plainly: **writing the rule and enforcing the rule are two different pieces of work, and finishing the first one feels exactly like finishing both.** The gap between them is silent, and it stays silent until something you assumed was impossible shows up in production.
If you want a worked example of that gap costing real traffic, the [Cloudflare Bot Fight Mode postmortem](/articles/cloudflare-bot-fight-mode-seo) is the same failure in a different layer: every dashboard green, every page indexed, and search crawlers being served a `noindex` page for five days.
---
## How Cloudflare Bot Fight Mode Quietly Killed Our Google Rankings
Author: Serdarcan Büyükdereli
Date: 2026-08-13
Category: DevOps Blog
URL: https://theinfinity.dev/articles/cloudflare-bot-fight-mode-seo
On 6 August one of the sites I run served 1,153 search impressions. On 7 August it served 119. By 12 August it was down to 16. Average position moved from 10.8 to 67.9 — from the first page of Google to the seventh.
Nothing had been deployed. The site was up the whole time, responding in under a second. Every page returned HTTP 200 in a browser. Search Console's URL Inspection said, for every URL I tested, *Submitted and indexed*. The pages were not removed, not deindexed, not penalised.
They were simply no longer being crawled, and the reason turned out to be a single toggle in Cloudflare that had been on for a while and had never caused a problem before.
This is the full diagnostic trail: what the data looked like, why the obvious explanations were wrong, the one header that settled it, and the control experiment that removed the last doubt.
## What does a crawl failure look like in Search Console?
It looks like a ranking collapse, not an indexing error — which is exactly why it is easy to misdiagnose. Here is the daily series across the break:
| Date | Impressions | Clicks | Avg. position |
|---|---|---|---|
| 4 Aug | 1,550 | 16 | 10.0 |
| 5 Aug | 1,666 | 8 | 10.7 |
| 6 Aug | 1,153 | 16 | 10.8 |
| **7 Aug** | **119** | **0** | **67.9** |
| 8 Aug | 50 | 0 | 54.4 |
| 12 Aug | 16 | 0 | 51.5 |
The device split made it look even stranger. Mobile went from 550 impressions on 6 August to **3** on 7 August. Desktop fell from 598 to 116. Tablet disappeared from the report entirely.
A drop like this has a small number of plausible causes, and I worked through them in order.
**A deploy broke something.** No deploy had happened. Git log was quiet for days on either side of 7 August.
**The pages got deindexed.** They did not. I ran URL Inspection against ten URLs — the homepage, several detail pages, a category page. Every one came back `PASS` / *Submitted and indexed*, with rich results detected. If Google had dropped them, this is where it would show.
**A manual action or algorithmic penalty.** A penalty does not usually take a site from position 10 to position 68 across every page type in one day and leave the index intact.
**robots.txt or a stray noindex.** `robots.txt` was clean and permissive — I keep explicit `Allow` blocks for the AI crawlers in there. No page carried a `noindex` in its source.
The thing that actually pointed at the answer was hiding in the URL Inspection output, in a field I nearly skipped: **last crawl date**. The most recent crawl across every URL I checked was 7 August. It was 12 August when I looked. Googlebot had not fetched a single page in five days, and the crawl had stopped on exactly the day the rankings fell.
> ⚠️ **Watch out:** *Submitted and indexed* is a statement about the past. It tells you Google has a copy of the page. It says nothing about whether Google can still reach it today. The field that tells you that is the last crawl date, and it is easy to walk straight past.
## Why was the index fine while the rankings were gone?
Because indexing and crawling fail independently. Google kept serving the pages it already had, but everything that depends on continued access — freshness, re-evaluation, the ability to confirm the page still matches the query — decayed. The URLs stayed in the index and slid down it.
That is why the shape of this failure is so misleading. Every tool that reports on *index status* says the site is healthy. The failure is in *access*, and almost nothing in Search Console reports on access directly.
## What the request actually returned
I stopped looking at dashboards and made requests. Fetching a page over `curl` returned this:
```bash
$ curl -sSI https://example.com/some-page
HTTP/2 403
cf-mitigated: challenge
server: cloudflare
server-timing: chlray;desc="a2a170726c3335c3"
```
`cf-mitigated: challenge` is Cloudflare stating, in the response itself, that it intercepted the request and served a challenge instead of the origin's content. The body confirmed it — the familiar interstitial:
```html
Just a moment...
```
There it is. **The challenge page carries `noindex,nofollow`.**
That single line explains the entire ranking collapse. A crawler that receives this page does not see your article. It sees a short HTML document with no content, no links, and an explicit instruction not to index or follow. Serve that to Googlebot repeatedly and you are telling Google, in the strongest markup available, that the URL should not be in search results.
The behaviour was not consistent, which had masked it for days. The same URL returned real content on one request and a challenge on the next. It is rate- and reputation-driven, not deterministic. A human clicking around the site would very likely never see it.
## Which Cloudflare setting causes this?
**Bot Fight Mode** — a single toggle under Security → Settings → Bot traffic, described in the dashboard as "Detect and challenges bot traffic on your domain."
The critical detail is what it does *not* do. Bot Fight Mode is the free-plan feature, and it does not carve out an exception for verified crawlers the way Super Bot Fight Mode does on paid plans. It classifies traffic as automated and challenges it, and a search engine crawler is, by every technical definition, automated traffic.
Security Events confirmed the mechanism from Cloudflare's side, with `Managed Challenge` as the action and `Bot fight mode` as the service.
There is a second-order effect worth knowing about. Because the challenge is what gets served, **every** non-browser client is affected, not just search crawlers. In my case an SEO health check flagged `ClaudeBot: HTTP 403` days before the rankings moved. I read it as an AI-crawler access question and moved on. It was the same failure, reported early, in a channel I was not treating as urgent.
> ⚠️ **Watch out:** If one bot is getting 403 from your CDN, do not scope the problem to that bot. Check the whole layer. A blocked AI crawler and a blocked Googlebot can be the same misconfiguration, and only one of them costs you traffic you can measure.
## How do you prove it was the CDN and not something else?
Run a control experiment. This is the part I would repeat on any infrastructure diagnosis, and it happened to be free here.
The affected site is not this one. It is a finance dashboard I run separately, and it happens to share everything with the site you are reading: same server, same Traefik instance, same Cloudflare account, same free plan, same DNS and certificate setup. Different Cloudflare zone.
theinfinity.dev — this site — was completely healthy throughout. Its crawl was current, its rankings were untouched. That made it an unusually clean control.
So I compared the two zones setting by setting and found exactly one meaningful difference: Bot Fight Mode was **on** for the broken site and **off** for the healthy one.
| | Broken site | Healthy site |
|---|---|---|
| Bot Fight Mode | On | Off |
| Challenge rate (47 requests) | 3 of 3 sampled | 0 of 47 |
| `cf-mitigated` header | `challenge` | absent |
| Googlebot last crawl | 5 days stale | current |
| Ranking impact | position 10 → 68 | none |
Same host, same proxy, same plan, one variable. That is as close to a controlled experiment as production infrastructure normally allows, and it is worth remembering that running two properties in one account gives you this for free.
One measurement did *not* work, and it is instructive. I filtered Cloudflare's Security Events to Google's ASN (15169) expecting to find a pile of challenged Googlebot requests. There were none. For a moment that looked like it exonerated Bot Fight Mode.
It did not — it confirmed the diagnosis. There were no challenge events from Google because **Googlebot had stopped coming**. Crawlers back off from hosts that stop returning content. By the time I went looking for the evidence, the traffic that would have produced it had already dried up. An empty log is not the same as a clean log.
## What the fix looked like
Turning Bot Fight Mode off, and replacing it with something targeted.
The reason it was on in the first place is real: one IP in Hong Kong was responsible for 1,080 requests in 24 hours, roughly a third of all traffic to the site. That is a scraper and it deserves a response — just not one that catches search engines in the same net.
A custom WAF rule does the same job with a scalpel:
```
(ip.src eq 203.0.113.10 and not cf.client.bot)
```
Action: Block. The `not cf.client.bot` clause is deliberate — if that address ever becomes a verified crawler, the rule stops applying to it rather than silently blocking a search engine.
Verification, immediately after:
```bash
# 24 requests across 4 URLs
temiz=24 challenge=0
$ curl -sSI https://example.com/some-page | grep -E 'HTTP|cf-mitigated'
HTTP/2 200
# cf-mitigated header is gone
```
And a bot sweep, since the whole point was crawler access:
| Crawler | Before | After |
|---|---|---|
| Googlebot | challenge | 200 |
| Bingbot | challenge | 200 |
| ClaudeBot | 403 | 200 |
| GPTBot | challenge | 200 |
The last step was resubmitting the sitemap to nudge the crawl back. Recovery is not instant — the rankings have to be re-earned as Google re-crawls — but the metric to watch is not position. It is the last crawl date in URL Inspection. When that starts moving forward again, the fix has landed.
## How do you tell if this is happening to you?
Four checks, in order of how quickly they give you an answer.
**Look at the response headers, not the page.** `curl -sSI https://yoursite.com/` and look for `cf-mitigated`. A browser will not show you this because a browser solves the challenge transparently. If the header is there, you have your answer in one request.
**Check the last crawl date, not the index status.** In Search Console, open URL Inspection on a few pages and read the crawl date rather than the verdict. If it is stale by days while your content is current, crawling has stopped even though indexing looks fine.
**Repeat your requests.** Challenges are probabilistic. I had URLs return real content and a challenge on consecutive requests. A single clean `curl` proves nothing — send five.
**Watch the boring bot in your monitoring.** The ClaudeBot 403 in my SEO check was the earliest signal available and it preceded the ranking loss by days. Non-browser clients are the canaries here, because they hit the challenge long before anything shows up in a search dashboard.
## FAQ
### Does Cloudflare Bot Fight Mode block Googlebot?
It can. Bot Fight Mode is the free-plan feature and it does not exempt verified crawlers the way Super Bot Fight Mode does on paid plans. When it challenges a request from a search crawler, the crawler receives an interstitial page carrying `noindex,nofollow` instead of your content.
### Why do my pages still show as indexed if Googlebot is blocked?
Indexing and crawling fail independently. Google continues to serve pages it has already indexed, so URL Inspection keeps reporting *Submitted and indexed*. The signal that reveals the problem is the last crawl date, which stops advancing.
### What does the cf-mitigated header mean?
`cf-mitigated: challenge` means Cloudflare intercepted the request and returned a challenge page rather than passing it to your origin. It appears alongside HTTP 403. It is the fastest single piece of evidence that a CDN rule, not your application, is responsible for what a client is seeing.
### Will turning off Bot Fight Mode expose my site to scrapers?
It removes one blunt layer, so replace it rather than simply deleting it. A WAF custom rule targeting the specific address, ASN or behaviour you actually want to stop does the same work without catching search engines. Adding `not cf.client.bot` to the expression keeps verified crawlers out of the rule permanently.
### How long does it take for rankings to recover?
There is no fixed number, because recovery depends on Google re-crawling the affected URLs and that happens on its own schedule. Watch the last crawl date rather than position — crawling resumes first, and rankings follow it.
### Can I keep Bot Fight Mode and still allow Googlebot?
Not reliably on the free plan, because the exemption for verified bots is a paid-plan capability. The practical options are to turn it off and write targeted rules, or to upgrade to a plan where Super Bot Fight Mode lets you allow verified crawlers explicitly.
### Does this affect AI crawlers too?
Yes, and usually first. The challenge is served to any client that fails the bot check, so GPTBot, ClaudeBot and PerplexityBot hit it the same way Googlebot does. If you have deliberately allowed AI crawlers in `robots.txt`, a CDN-level challenge silently overrides that intent.
## What to check now
If you run anything behind Cloudflare on a free plan, this takes about a minute. Send `curl -sSI` at your own site five times and look for `cf-mitigated`. Open Search Console and read the last crawl date on three URLs. Then open Security → Settings and look at whether Bot Fight Mode is on.
The failure mode here is not that something broke loudly. It is that a protective setting did exactly what it advertised — challenge automated traffic — and search crawlers are automated traffic. The site stayed up, the pages stayed indexed, the dashboards stayed green, and the traffic left anyway.
If you want the measurement discipline that surfaced this, the same approach shows up in [our cache eviction benchmark](/articles/cache-eviction-benchmark): stop reading about the behaviour and measure it, and prefer the check that can only come out one way.
---
## Cache Eviction Algorithms: FIFO vs LRU vs LFU vs S3-FIFO Benchmark
Author: Serdarcan Büyükdereli
Date: 2026-08-12
Category: DevOps Blog
URL: https://theinfinity.dev/articles/cache-eviction-benchmark
LRU scored exactly zero hits on one million requests. Not 0.4%, not "close to zero" — 0 out of 1,000,000, with a cache large enough to hold 90% of the working set.
The workload was a cyclic scan: walk 20,000 keys in order, then start over. FIFO returned zero too. So did LFU. Random replacement, the policy nobody writes blog posts about, hit 79.1% on the same trace.
That result is why I stopped reading about cache eviction and started measuring it. Almost every article on the topic explains the algorithms and then asserts a ranking. So I implemented FIFO, LRU, LFU and S3-FIFO from scratch in Python — no libraries — and ran each one over three access patterns, four cache sizes, and 1,000,000 requests per pattern. Random replacement and Belady's offline optimum are included as reference lines: one tells you how low the bar is, the other tells you how much headroom is left.
Across the 12 hit-rate cells, S3-FIFO had the best number in 8, LFU in 3, and random replacement in 1. No policy won everywhere, and the winning margins ranged from 0.02 percentage points to 24.
## What do FIFO, LRU, LFU, and S3-FIFO actually do?
They differ in one decision: which resident key to throw away when a new one arrives. FIFO evicts the oldest insertion, LRU the least recently touched, LFU the least frequently touched, and S3-FIFO splits the cache into a small probation queue and a main queue so that one-hit wonders never reach the main queue at all.
Every implementation below is the one I benchmarked, with unit-sized objects and integer keys.
### FIFO
Insertion order decides everything. A hit changes nothing, which is exactly why it is cheap.
```python
class FIFO:
def __init__(self, capacity):
self.cap = capacity
self.q = deque()
self.live = set()
def get(self, key):
if key in self.live:
return True
if len(self.live) >= self.cap:
self.live.discard(self.q.popleft())
self.q.append(key)
self.live.add(key)
return False
```
### LRU
A hit moves the key to the back of the queue. That single line is the whole difference from FIFO, and it costs a pointer update on every hit.
```python
class LRU:
def __init__(self, capacity):
self.cap = capacity
self.d = OrderedDict() # hash map + doubly linked list
def get(self, key):
if key in self.d:
self.d.move_to_end(key) # this is the entire algorithm
return True
if len(self.d) >= self.cap:
self.d.popitem(last=False)
self.d[key] = None
return False
```
### LFU
Keys live in buckets indexed by access count, and each bucket is itself ordered by recency so ties break the LRU way. Counters never decay, which is the classic weakness: a key that was hot last Tuesday can squat in the cache forever.
```python
class LFU:
def __init__(self, capacity):
self.cap = capacity
self.freq = {} # key -> count
self.buckets = defaultdict(OrderedDict) # count -> keys, LRU order
self.min_freq = 0
def get(self, key):
if key in self.freq:
f = self.freq[key]
del self.buckets[f][key]
# … promote key from bucket f to bucket f+1, fix min_freq
return True
if len(self.freq) >= self.cap:
victim, _ = self.buckets[self.min_freq].popitem(last=False)
del self.freq[victim]
# … insert key into bucket 1, min_freq = 1
return False
```
### S3-FIFO
S3-FIFO (Yang et al., SOSP '23) uses three FIFO queues and no linked-list surgery on hits. New keys land in a small queue `S` holding 10% of capacity. If a key in `S` is touched at least twice it graduates to the main queue `M`; otherwise its identifier drops into a ghost queue `G` that stores keys but no data. A miss that hits `G` skips probation and goes straight into `M`.
The paper calls these ideas quick demotion and lazy promotion. Quick demotion is the one that earns its keep: most keys in a real workload are requested once, and S discards them after 10% of the cache worth of traffic instead of 100%.
```python
class S3FIFO:
def __init__(self, capacity, small_ratio=0.10,
ghost_ratio=0.90, move_threshold=2):
self.cap = capacity
self.s_cap = max(1, int(capacity * small_ratio))
self.m_cap = max(1, capacity - self.s_cap)
self.g_cap = max(1, int(capacity * ghost_ratio))
self.move_threshold = move_threshold
self.S, self.M = deque(), deque()
self.G = OrderedDict() # ghost: keys only, no payload
self.loc, self.freq = {}, {}
self.has_evicted = False
def _evict_small(self):
while self.S:
key = self.S.popleft()
if self.freq[key] >= self.move_threshold:
self.M.append(key) # lazy promotion
self.loc[key], self.freq[key] = 1, 0
continue
del self.loc[key], self.freq[key]
self._ghost_add(key) # quick demotion
return
def _evict_main(self):
while self.M:
key = self.M.popleft()
f = self.freq[key]
if f >= 1: # FIFO-reinsertion, CLOCK-style
self.M.append(key)
self.freq[key] = min(f, 3) - 1
continue
del self.loc[key], self.freq[key]
return
def get(self, key):
if key in self.loc:
f = self.freq[key]
if f < 3: # 2-bit saturating counter
self.freq[key] = f + 1
return True
hit_ghost = key in self.G
if hit_ghost:
del self.G[key]
while len(self.loc) >= self.cap:
self._evict()
if hit_ghost or (not self.has_evicted and len(self.S) >= self.s_cap):
self.M.append(key) # ghost hit skips probation
self.loc[key] = 1
else:
self.S.append(key)
self.loc[key] = 0
self.freq[key] = 0
return False
```
This is the object-count variant, ported line by line from the reference C implementation in libCacheSim, whose defaults are `small-size-ratio=0.10`, `ghost-size-ratio=0.90`, `move-to-main-threshold=2`. The paper's own evaluation uses byte-sized objects on production traces; that is a different animal, and I am not claiming to reproduce it.
## How was this benchmark built and how do you reproduce it?
One Python file, one fixed seed, one command, about 30 seconds. Everything ran on an Apple M5 (arm64, macOS 26.6.1) under CPython 3.9.6, single-threaded, with 1,000,000 requests per access pattern and a base seed of `20260812`. There are no third-party dependencies, and reruns produce byte-identical output.
The three access patterns:
- **Zipf**, α = 0.9 over 100,000 keys, of which 91,217 appear in the trace. Popularity is skewed the way web and CDN traffic is skewed. Key IDs are shuffled so ID order carries no popularity signal.
- **Cyclic scan**, 20,000 keys visited in order, on repeat — 50 full laps. The textbook LRU pathology, included to see how bad "bad" really is.
- **Mixed**, 80% of requests from a Zipf-distributed hot set of 10,000 keys, 20% one-hit wonders from a scan that never repeats. This is the shape most production caches see, and its ceiling is 80% by construction — a fifth of the requests can never hit.
Cache sizes are a fraction of the distinct keys in each trace. The loop uses a different grid (10% to 90%) because a loop only gets interesting when the cache is close to the working set.
Before any numbers are printed, the script runs a correctness gate: every policy is checked for capacity violations, for hit-versus-residency agreement on every request, and against two identities — no online policy may beat Belady's offline optimum, and every policy with an infinite cache must return exactly `requests - distinct_keys` hits. All five pass. Two external checks back this up: Belady's loop numbers land on exactly `capacity / working_set` at steady state, and random replacement obeys the fixed-point equation `h = e^(-(W/C)(1-h))` — at C=10,000 and W=20,000 the model predicts 20.3% and the run produced 20.4%.
> ⚠️ **Watch out:** hit rates in the tables cover the whole trace, cold start included. The first `capacity` misses are compulsory and drag every policy down at large cache sizes. Where steady state tells a different story I say so.
## Which algorithm wins on Zipf-distributed traffic?
S3-FIFO and LFU win, and they win by 7.6 to 10.9 percentage points over LRU at the two smallest cache sizes. FIFO and random replacement are indistinguishable from each other and clearly last.
Hit rate %, 1,000,000 requests, Zipf α=0.9 over 91,217 distinct keys:
| Policy | cap=1,000 (1.1%) | cap=5,000 (5.5%) | cap=10,000 (11%) | cap=25,000 (27%) |
|---|---|---|---|---|
| FIFO | 30.59 | 47.42 | 56.29 | 69.97 |
| LRU | 34.17 | 51.45 | 60.38 | 73.65 |
| LFU | 44.12 | 59.09 | 66.23 | **76.64** |
| S3-FIFO | **45.03** | **59.81** | **66.73** | 76.55 |
| RANDOM | 30.64 | 47.45 | 56.36 | 70.08 |
| Belady (offline optimum) | 53.31 | 69.40 | 76.52 | 85.26 |
Two things stand out. First, FIFO and random replacement stay within 0.11 points of each other at every size. FIFO's insertion order carries almost no information on skewed traffic — it is a coin flip with extra bookkeeping. Second, LFU is not the fossil its reputation suggests. On a stationary popularity distribution, counting is close to the right thing to do, and at 27% cache size LFU edges out S3-FIFO by 0.09 points.
The gap between the policies is really a gap in how fast they discard the tail. Skew determines how much tail there is, so I reran the 10,000-key cache at three exponents:
| Policy | α=0.7 | α=0.9 | α=1.2 |
|---|---|---|---|
| FIFO | 31.29 | 56.29 | 89.84 |
| LRU | 34.58 | 60.38 | 91.46 |
| LFU | 42.13 | 66.23 | 92.54 |
| S3-FIFO | **43.15** | **66.73** | **92.63** |
| Belady (offline optimum) | 60.32 | 76.52 | 94.56 |
The result runs opposite to intuition: the flatter the distribution, the more the smart policies win. At α=0.7 S3-FIFO beats LRU by 8.6 points, at α=1.2 by 1.2. When traffic is heavily skewed the hot set is small and obvious, and any policy finds it. Quick demotion pays off precisely when the tail is fat.
## When does LRU actually lose?
On a cyclic scan, and it loses completely — 0 hits out of 1,000,000, at every cache size I tested, including one holding 90% of the working set. FIFO and LFU produce the identical zero.
Hit rate %, cyclic scan over 20,000 keys, 1,000,000 requests:
| Policy | cap=2,000 (10%) | cap=5,000 (25%) | cap=10,000 (50%) | cap=18,000 (90%) |
|---|---|---|---|---|
| FIFO | 0.00 | 0.00 | 0.00 | 0.00 |
| LRU | 0.00 | 0.00 | 0.00 | 0.00 |
| LFU | 0.00 | 0.00 | 0.00 | 0.00 |
| S3-FIFO | **8.82** | **22.05** | **44.10** | 63.93 |
| RANDOM | 0.00 | 1.94 | 20.01 | **79.14** |
| Belady (offline optimum) | 9.80 | 24.50 | 49.00 | 88.20 |
The zeros are not rounding. At the 90% cache size I printed raw counts instead of percentages: FIFO 0 hits, LRU 0 hits, LFU 0 hits, out of 1,000,000. A loop evicts each key exactly one step before it is needed again, forever, and recency order is precisely the wrong order to evict in. LFU joins them because in a pure loop no key is ever hit twice, so every counter stays at 1 and LFU degenerates into LRU.
Random replacement escapes because it is not systematic. It keeps a shrinking-but-nonzero fraction of the loop by accident, and at 90% cache size that accident is worth 79.1% — better than every policy in this article and 90% of the offline optimum.
S3-FIFO's nonzero numbers deserve honesty rather than applause. I instrumented the run: at cap=2,000 the main queue ends holding exactly 1,800 keys — its full capacity — every one admitted during warm-up. Since no key is ever hit twice, nothing is promoted out of `S`, and `M`'s eviction path only fires when `M` overflows or `S` runs empty. Neither happens. `M` freezes into a static pinned cache, and 88,200 hits is exactly 49 laps × 1,800 pinned keys. The steady-state hit rate lands on `0.9 × capacity / working_set` to the decimal at three of the four sizes.
That is faithful to the reference implementation, not a bug in my port, but it means the loop column measures accidental pinning rather than scan resistance. Real traces have repeat accesses, M churns normally, and the effect disappears. The engineering conclusion is unchanged: if your workload contains a genuine loop over a set larger than your cache, no policy in this family will save you. Shard the loop or size the cache above the working set.
## What happens when a scan pollutes a hot working set?
S3-FIFO wins where it is designed to win, by up to 9.9 points over LRU, and it gets within 1.4 points of the offline optimum. This is the pattern that matters most, because a hot working set plus a stream of one-hit wonders is what real caches see.
Hit rate %, 80% Zipf over 10,000 hot keys + 20% never-repeated keys, 210,220 distinct keys, ceiling 80%:
| Policy | cap=2,102 (1%) | cap=10,511 (5%) | cap=21,022 (10%) | cap=52,555 (25%) |
|---|---|---|---|---|
| FIFO | 44.56 | 63.81 | 70.53 | 75.75 |
| LRU | 48.87 | 68.77 | 75.51 | 78.79 |
| LFU | 58.40 | 76.86 | **78.65** | **78.96** |
| S3-FIFO | **58.73** | **77.62** | 78.63 | 78.94 |
| RANDOM | 44.55 | 63.91 | 70.70 | 76.10 |
| Belady (offline optimum) | 66.93 | 78.98 | 78.98 | 78.98 |
Read the 5% column carefully. S3-FIFO reaches 77.62 against a hard ceiling of 80 and an offline optimum of 78.98 — it is leaving 1.4 points on the table while LRU leaves 10.2. The small queue is doing exactly its job: one-hit wonders enter S, never get a second touch, and are demoted after consuming 10% of the cache instead of 100% of it.
Then look at the last two columns, where LFU takes both by 0.02 points. Once the cache is large enough to hold the hot set outright, admission control stops mattering and every frequency-aware policy converges on the ceiling. A 0.02-point difference is a tie, and anyone reporting it as a win is selling something.
I also swept S3-FIFO's small-queue ratio here, since 10% is a tuned constant rather than a law. At the 5% cache size the hit rate goes 78.01 / 77.62 / 76.47 / 75.18 / 72.25 for small queues of 5 / 10 / 20 / 30 / 50%. Smaller is monotonically better on this workload, and the published 10% default costs 0.4 points against a 5% queue. That default is a safe compromise across many traces, not the optimum for yours.
## What does eviction cost in throughput?
FIFO and LRU run 2.0x to 2.5x faster than LFU and S3-FIFO in this implementation, which sounds decisive and usually is not. Throughput here is a property of my Python code, not of the algorithms.
Thousand operations per second, single-threaded CPython 3.9.6 on an Apple M5:
| Policy | Zipf, cap=10,000 | Mixed, cap=21,022 |
|---|---|---|
| FIFO | 8,541 | 10,027 |
| LRU | 8,541 | 10,439 |
| LFU | 3,707 | 3,944 |
| S3-FIFO | 3,456 | 5,315 |
| RANDOM | 4,260 | 5,950 |
Treat these as ordering, not magnitude. A production C or Rust implementation changes all five numbers by an order of magnitude and changes their ratios too. What survives the language change is the shape of the work: LFU touches multiple dictionaries per hit, S3-FIFO's eviction path can walk several queue entries before it frees a slot, and both do more per operation than a deque append.
The argument my harness cannot settle is concurrency. LRU mutates a shared linked list on every hit, so it needs a lock on the read path — the reason production systems reach for CLOCK or sharded approximations. S3-FIFO only increments a per-object counter, one atomic operation with no list surgery. That is the scalability claim in the SOSP paper, and single-threaded numbers can neither confirm nor refute it.
## Which one should you actually use?
S3-FIFO, if you are choosing today and your traffic looks anything like the mixed pattern. It led 8 of 12 hit-rate cells, it never lost to LFU by more than 0.09 points, and it beat LRU by 8.4 to 10.9 points wherever the workload had a fat tail. The implementation above is roughly 70 lines of Python and needs no locks on the read path. Its only real defeat was to random replacement on the loop, by 15.2 points — a pattern where you have a sizing problem, not a policy problem.
The more useful finding is how much of the received wisdom did not survive contact with a benchmark. FIFO is not meaningfully better than random replacement on skewed traffic — the two stayed within 0.11 points at every size. LFU is not obsolete; it won three cells and was within a rounding error in four more. Random replacement is not a joke policy; it was the best online policy in this article on the one pattern where the others returned literal zeros. And S3-FIFO's advantage narrows to nothing exactly when your cache is big enough to hold the hot set, which is the case where the decision was never going to matter.
If you take one operational habit from this, take the size question first. On both realistic patterns, every policy at the largest cache size beat every policy at the smallest, by margins no eviction algorithm came close to. Replacing LRU with S3-FIFO bought 9.9 points on the mixed pattern. Growing the same cache from 1% to 5% of the key space bought 18.9. Tune the cheap knob before the clever one.
## FAQ
### Is S3-FIFO always better than LRU?
No. S3-FIFO beat LRU in every cell I measured — by 0.15 to 10.9 points on the two realistic patterns, and by more on the loop, where LRU sits at zero. But the margin collapses as the cache grows past the hot working set: at 25% cache size on the mixed pattern the gap was 0.15 points. On a pure cyclic scan both are effectively useless and random replacement wins.
### Why did LRU get exactly zero hits on a loop?
A cyclic scan over a working set larger than the cache evicts every key one step before it is needed again. LRU always discards the key that has waited longest, which in a loop is always the next key requested. The failure is systematic, so the hit count is exactly 0 rather than merely low.
### Does LFU still make sense in 2026?
Yes, for stationary popularity distributions. LFU had the highest hit rate in 3 of my 12 cells and stayed within 1 point of S3-FIFO in most of the rest. Its real weakness is not accuracy but adaptation: counters that never decay let yesterday's hot keys squat in the cache, and my traces have no popularity shift to expose that.
### What cache size should I use?
Larger than your hot working set, if you can afford it. In my mixed-pattern run, growing the cache from 1% to 5% of the key space gained S3-FIFO 18.9 points of hit rate — roughly twice what switching from LRU to S3-FIFO gained at a fixed size. Sizing dominates policy until the hot set fits.
### Is random replacement a serious option?
For loop-heavy workloads, yes. Random replacement hit 79.1% on a cyclic scan where FIFO, LRU and LFU all hit exactly 0%, and it obeys a clean analytic model: `h = e^(-(W/C)(1-h))`. It is also lock-free and needs no metadata. On Zipf traffic it trailed S3-FIFO by 6 to 14 points, so it is a pattern-specific answer, not a general one.
### How do these results compare to the SOSP '23 paper?
They agree on direction, not magnitude, and the setups differ. The paper evaluates S3-FIFO against 6,594 production traces with byte-sized objects; I ran three synthetic patterns with unit-sized objects. My numbers are my own measurements — quote them as such.
### What is Belady's optimum doing in the tables?
It is the ceiling, not a candidate. Belady's MIN evicts the key whose next use is farthest in the future, which requires knowing the future, so no online cache can implement it. Its value is calibration: on the mixed pattern at 5% cache size it shows S3-FIFO's remaining headroom is 1.4 points while LRU's is 10.2.
## References
- Juncheng Yang, Ziyue Qiu, Yazhuo Zhang, Yao Yue, K. V. Rashmi. *FIFO queues are all you need for cache eviction.* SOSP '23. [doi.org/10.1145/3600006.3613147](https://dl.acm.org/doi/10.1145/3600006.3613147)
- [s3fifo.com](https://s3fifo.com/) — the authors' summary of quick demotion and lazy promotion.
- Reference S3-FIFO implementation in libCacheSim: [S3FIFO.c](https://github.com/1a1a11a/libCacheSim/blob/develop/libCacheSim/cache/eviction/S3FIFO.c). My Python port follows its defaults and control flow.
- L. A. Belady. *A study of replacement algorithms for a virtual-storage computer.* IBM Systems Journal, 1966. The origin of the offline optimum used as the ceiling here.
---
## S3 Storage Class Cost: The Break-Even Math Behind Every Tier
Author: Serdarcan Büyükdereli
Date: 2026-08-12
Category: DevOps Blog
URL: https://theinfinity.dev/articles/s3-storage-class-break-even
S3 Standard-IA costs 45% less per GB than S3 Standard in Frankfurt: $0.0135 against $0.0245 per GB-month. That number moves a lot of data into lifecycle rules, and a good share of those rules make the bill go up rather than down.
The reason is that the GB-month rate is one of four charges, and the other three run in the opposite direction. Standard-IA adds a retrieval fee, nearly doubles the PUT price, multiplies the GET price by 2.3, pads every object under 128 KB up to 128 KB, and bills you for 30 days even if the object lives for two. Whether you save money depends on how those pull against each other for *your* object size and *your* access rate.
This article works out the crossover points. Every price came out of the AWS Price List Query API on 12 August 2026 (price list version `20260807185915`, rates effective 1 August 2026) for `eu-central-1` and `us-east-1`. Every break-even is calculated from those prices, and the formula is shown so you can rerun it with your own numbers. If you want the exam-level tour of what each class *is*, that is the companion piece: [Amazon S3 for the SAA-C03 exam](/articles/amazon-s3-saa-c03-exam-guide). This one is about which one is actually cheaper.
## What actually determines the cost of an S3 storage class?
Four charges decide it: storage per GB-month, retrieval per GB, requests per thousand, and two structural penalties — the minimum billable object size and the minimum storage duration. Only the first gets quoted in comparison tables.
Here are the storage rates, straight from the Pricing API:
| Storage class | eu-central-1 $/GB-mo | us-east-1 $/GB-mo | Retrieval $/GB | GET per 10,000 (eu) |
|---|---|---|---|---|
| S3 Standard (first 50 TB) | 0.0245 | 0.023 | none | 0.0043 |
| S3 Intelligent-Tiering (Frequent) | 0.0245 | 0.023 | none | 0.0043 |
| S3 Standard-IA | 0.0135 | 0.0125 | 0.01 | 0.01 |
| S3 One Zone-IA | 0.0108 | 0.01 | 0.01 | 0.01 |
| S3 Glacier Instant Retrieval | 0.005 | 0.004 | 0.03 | 0.10 |
| S3 Glacier Flexible Retrieval | 0.00405 | 0.0036 | 0.012 (Standard tier) | 0.0043 |
| S3 Express One Zone | 0.118 | 0.11 | 0.000645 | 0.000323 |
Two things in that table are easy to miss. Glacier Instant Retrieval's GET requests cost 23 times a Standard GET, not 23 percent more. And Intelligent-Tiering's Frequent Access tier is priced *identically* to Standard — the class only saves money once objects actually tier down, which takes 30 days of no access.
The structural penalties come from the [S3 storage class comparison table](https://docs.aws.amazon.com/AmazonS3/latest/userguide/storage-class-intro.html) in the AWS documentation:
| Storage class | Minimum storage duration | Minimum billable object size |
|---|---|---|
| S3 Standard | none | none |
| S3 Intelligent-Tiering | none | none (objects under 128 KB are not monitored) |
| S3 Standard-IA | 30 days | 128 KB |
| S3 One Zone-IA | 30 days | 128 KB |
| S3 Glacier Instant Retrieval | 90 days | 128 KB |
| S3 Glacier Flexible Retrieval | 90 days | 40 KB metadata per object |
| S3 Glacier Deep Archive | 180 days | 40 KB metadata per object |
## How often can you read data before Standard-IA stops saving money?
Once a month, roughly. In Frankfurt, Standard-IA stops being cheaper than Standard once you retrieve about 104% of the dataset per month with 1 MB objects. If your data is read more than once a month on average, Standard-IA costs more.
The math is one line. Let `f` be the fraction of the dataset you retrieve per month — `f = 0.25` means you read a quarter of your bytes every month. Per GB stored:
```text
Standard cost = 0.0245
Standard-IA cost = 0.0135 + f × 0.01 (retrieval)
+ f × n × (GET_ia − GET_std) (n = objects per GB)
```
Setting them equal and solving for `f`:
```text
f = (0.0245 − 0.0135) / (0.01 + n × (0.000001 − 0.00000043))
```
With 1 MB objects there are 1,024 objects per GB, so the GET delta adds $0.000584 per GB read:
```text
f = 0.0110 / (0.01 + 0.000584) = 0.0110 / 0.010584 = 1.039
```
Object size shifts that number more than people expect, because the request delta scales with object count:
| Object size | Break-even reads/month (eu-central-1) | Break-even reads/month (us-east-1) |
|---|---|---|
| 8 MB | 1.09 | 1.04 |
| 1 MB | 1.04 | 0.99 |
| 128 KB | 0.75 | 0.70 |
| Requests ignored | 1.10 | 1.05 |
Now look at what that means against AWS's own guidance. The documentation describes Standard-IA as suited to data accessed "once a month". Read your data exactly once a month at 1 TB of 1 MB objects and the yearly numbers are $306.47 for Standard against $301.35 for Standard-IA — a saving of $5.12, or 1.7%. You took on a retrieval fee, a 30-day minimum and a 128 KB floor to save under two percent.
Standard-IA only earns its complexity well below the break-even. At one read every four months (`f = 0.25`), the same terabyte drops to $199.75 a year against Standard's $302.41 — a 34% cut. That is the band worth targeting.
> ⚠️ **Watch out:** the retrieval fee is charged per GB *retrieved*, not per unique GB. Reading the same 10 GB file five times bills 50 GB of retrieval. A cache miss storm or a re-run backfill job can produce a month's worth of retrieval charges in an afternoon.
## When does Glacier Instant Retrieval beat Standard-IA?
When you read less than about 29% of the data per month with 1 MB objects, or 42.5% if your objects are large enough that request costs disappear. Below that, Glacier Instant Retrieval wins; above it, Standard-IA does.
Glacier Instant Retrieval is cheaper to store ($0.005 vs $0.0135 in Frankfurt) and much more expensive to touch: retrieval is $0.03/GB instead of $0.01, and GETs are $0.10 per 10,000 instead of $0.01. Same structure as before:
```text
0.0135 + f × (0.01 + n × 0.000001) = 0.005 + f × (0.03 + n × 0.00001)
```
With 1,024 objects per GB:
```text
0.0085 = f × (0.04024 − 0.011024) = f × 0.029216
f = 0.291
```
A curiosity worth noting: this break-even is *identical* in both regions. The storage gap is $0.0085/GB-month in Frankfurt and in N. Virginia alike, and the retrieval prices are the same in both. Regional price differences cancel out here even though they do not for the Standard comparison.
Object size swings this one hard, because Glacier Instant Retrieval's GET price is what makes small objects expensive there:
- 8 MB objects: GIR wins below 40.2% per month, one full read every 2.5 months
- 1 MB objects: below 29.1% per month, one full read every 3.4 months
- 128 KB objects: below 9.1% per month, one full read every 11 months
AWS positions Glacier Instant Retrieval for data "accessed once a quarter". For 1 MB objects the crossover lands at one read every 3.4 months, so quarterly access sits marginally on the wrong side of it — at exactly quarterly, Standard-IA is a few percent cheaper. Step one notch further apart, to a full read every four months, and the gap opens properly: $185 a year for a terabyte in Glacier Instant Retrieval against $200 in Standard-IA and $302 in Standard.
## When does Intelligent-Tiering stop making sense?
Below roughly 238 KB per object in Frankfurt (250 KB in N. Virginia), the monitoring fee costs more than the tiering saves. Intelligent-Tiering charges $0.0025 per 1,000 objects per month, which is a fixed cost per object while the saving scales with object size.
The monitoring fee is $0.0000025 per object per month, in both regions. An object that ages into the Infrequent Access tier saves the gap between the Frequent and Infrequent rates, $0.0110 per GB-month in Frankfurt. Break even where those meet:
```python
monitoring = 0.0025 / 1000 # per object per month
saving = 0.0245 - 0.0135 # per GB-month, FA -> IA
size_gb = monitoring / saving # 0.00022727 GB
size_kb = size_gb * 1048576 # 238.3 KB
```
If objects eventually reach the Archive Instant Access tier after 90 days without access, the saving grows to $0.0195/GB-month and the threshold falls to 134 KB. That is the most generous case, and it still sits above the 128 KB line where AWS stops monitoring at all.
So the window where Intelligent-Tiering costs you money is narrow but real: objects between 128 KB and roughly 240 KB get monitored, get charged, and do not save enough to cover it. A bucket of 50 million 200 KB thumbnails pays $125 a month in monitoring fees to save less than that in tiering.
The other failure mode has nothing to do with size. Intelligent-Tiering only saves money when objects go 30 days untouched. Data that is read weekly never leaves the Frequent Access tier, which is priced identically to Standard — so the monitoring fee is pure loss no matter how big the objects are.
> ⚠️ **Watch out:** Intelligent-Tiering has no retrieval fee and no minimum storage duration. That is what makes it the safe default for genuinely unpredictable access. The fee is the price of not having to guess, and for objects of a few megabytes it is negligible — $0.0000025 against $0.02 of storage.
## What does the 128 KB billing floor really cost?
It flips the discount into a penalty below a specific size. In Frankfurt, any object smaller than 70.5 KB costs *more* in Standard-IA than in Standard, before a single byte is retrieved. The formula is clean:
```text
break-even size = 128 KB × (class rate / Standard rate)
```
Standard-IA in Frankfurt: `128 × 0.0135 / 0.0245 = 70.5 KB`. One Zone-IA: 56.4 KB. Glacier Instant Retrieval, whose rate is far lower, only turns bad below 26.1 KB.
A worked example makes the size of the mistake obvious. Take 10 million objects of 32 KB — a fairly ordinary thumbnail or telemetry-fragment bucket:
- Real data: 10,000,000 × 32 KB = **305.2 GB**
- Billed in Standard-IA: 10,000,000 × 128 KB = 1,220.7 GB
- Standard-IA: 1,220.7 × $0.0135 = **$16.48/month**
- Standard: 305.2 × $0.0245 = **$7.48/month**
The lifecycle rule that "saved 45%" doubled the bill. Nothing in the S3 console warns you about this, and the usage line item that carries it — `TimedStorage-SIA-SmObjects` — reads like a normal storage charge.
## How long does an object have to live to be worth moving?
Longer than the minimum duration suggests. In Frankfurt an object must sit in Standard-IA for 16.5 days just to match what Standard would have cost — and that is with zero retrievals. The 30-day minimum means anything deleted before then is billed for the full 30 days anyway.
```text
0.0245 × (D / 30) = 0.0135 → D = 16.53 days
```
Write a terabyte to Standard-IA and delete it on day five and you pay $13.82. The same terabyte in Standard for five days costs $4.18. The early-delete charge is not a flat penalty; it is the class's own rate applied to the days you did not use, which is why it lands as a separate `EarlyDelete-SIA` line.
The transition request is the second cost people forget. Moving objects into Standard-IA costs $0.01 per 1,000, which is trivial per gigabyte and brutal per object:
- 8 MB objects: saves $0.0000859 a month each, transition pays back in 0.12 months
- 1 MB objects: $0.0000107 a month, payback 0.93 months
- 256 KB objects: $0.0000027 a month, payback 3.72 months
- 128 KB objects: $0.0000013 a month, payback 7.45 months
- Under 70.5 KB: the saving is negative, so the transition never pays back
Transitions into the archive classes cost more: $0.02 per 1,000 into Glacier Instant Retrieval, $0.036 into Glacier Flexible Retrieval, $0.06 into Glacier Deep Archive (Frankfurt). For a bucket of a hundred million small objects, a single lifecycle transition into Deep Archive is a $6,000 one-off charge.
> ⚠️ **Watch out:** the AWS Price List Query API does not return a GB-month SKU for S3 Glacier Deep Archive in either region — only `TimedStorage-GDA-Staging`, which is staging storage, not the class rate. If you are scripting cost models against the Pricing API, that field will silently come back empty. Read Deep Archive's storage rate from the bulk price list file or the pricing page instead of assuming a value.
## The whole thing in one table
Same terabyte, 1 MB objects, twelve months, `eu-central-1`, varying how much of it you read each month. Storage, retrieval and GET requests included; transitions excluded.
| Reads per month | S3 Standard | S3 Standard-IA | Glacier Instant Retrieval |
|---|---|---|---|
| 0 (write once, never read) | $301.06 | $165.89 | **$61.44** |
| 0.1 | $301.60 | $179.43 | **$110.89** |
| 0.25 | $302.41 | $199.75 | **$185.06** |
| 0.5 | $303.76 | **$233.62** | $308.67 |
| 1.0 | $306.47 | **$301.35** | $555.91 |
| 2.0 | **$311.88** | $436.81 | $1,050.38 |
Standard's line barely moves — from $301 to $312 across a twentyfold change in read volume — because it has no retrieval fee and cheap GETs. That flatness is the actual product. You pay a premium per GB to make access free, and the premium is worth it the moment access is anything but rare.
## What to do
Do not write a lifecycle rule based on the GB-month rate. Pull your object count and total size per prefix from S3 Storage Lens or an S3 Inventory report, divide to get mean object size, and check it against the floor first. Under 70.5 KB mean size, stop — no infrequent-access class will help you, and the fix is packing objects together, not tiering them.
Above that, get an access rate before you get an opinion. S3 Server Access Logs or CloudTrail data events for a fortnight will tell you what fraction of bytes actually gets read per month. Then use the numbers above: over roughly one full read a month, stay on Standard. Between about a quarter and a full read, Standard-IA. Under a quarter, Glacier Instant Retrieval. If you genuinely cannot measure it and objects are comfortably over 240 KB, Intelligent-Tiering is worth its fee — that fee buys you the right not to know.
And rerun the prices. Everything here is dated 12 August 2026 for two regions. Retrieval and request prices vary by region far less than storage prices do, which quietly moves the break-even points around:
```bash
# --region is the Pricing API endpoint, NOT the region being priced.
# The region being priced is the regionCode filter.
aws pricing get-products \
--region us-east-1 \
--service-code AmazonS3 \
--filters Type=TERM_MATCH,Field=productFamily,Value=Storage \
Type=TERM_MATCH,Field=regionCode,Value=eu-central-1 \
| jq -r '.PriceList[] | fromjson
| [.product.attributes.usagetype,
(.terms.OnDemand[].priceDimensions[].pricePerUnit.USD)]
| @tsv'
# The Intelligent-Tiering monitoring fee sits under its own usage type,
# and is not part of the Storage product family.
aws pricing get-products \
--region us-east-1 \
--service-code AmazonS3 \
--filters Type=TERM_MATCH,Field=usagetype,Value=EUC1-Monitoring-Automation-INT
```
## FAQ
### Is S3 Standard-IA always cheaper than S3 Standard?
No. Standard-IA is cheaper only when objects average more than about 70 KB and you retrieve less than roughly one full copy of the data per month. Below 70.5 KB the 128 KB billing floor makes it more expensive in Frankfurt even with zero retrievals, and above one read per month the $0.01/GB retrieval fee overtakes the storage saving.
### How much does S3 Intelligent-Tiering monitoring cost?
$0.0025 per 1,000 objects per month, which is $0.0000025 per object, and it is the same price in eu-central-1 and us-east-1. Objects smaller than 128 KB are not monitored and are not charged the fee. For the fee to pay for itself through tiering, an object needs to be larger than about 238 KB in Frankfurt.
### What is the 128 KB minimum billable object size in S3?
S3 Standard-IA, One Zone-IA and Glacier Instant Retrieval bill every object as if it were at least 128 KB. A 20 KB object in Standard-IA is charged as 128 KB. S3 Standard, S3 Express One Zone and Intelligent-Tiering have no minimum billable size.
### What happens if I delete an object before the minimum storage duration?
You are charged for the full minimum period. Standard-IA and One Zone-IA require 30 days, Glacier Instant Retrieval and Glacier Flexible Retrieval 90 days, and Glacier Deep Archive 180 days. AWS bills the normal storage charge plus a pro-rated charge for the remaining days, at that class's own rate.
### Which S3 storage class is cheapest for data that is never read?
S3 Glacier Deep Archive, followed by Glacier Flexible Retrieval at $0.00405/GB-month in Frankfurt — about $50 a year per terabyte against Standard's $301. Check the transition request cost before committing, though: moving many small objects into an archive class can cost more than a year of the storage it saves, and both Glacier archive classes add 40 KB of billed metadata per object.
### Does S3 Intelligent-Tiering charge retrieval fees?
No. Intelligent-Tiering has no retrieval fees and no minimum storage duration, which is what separates it from Standard-IA. You pay the per-object monitoring fee instead, and objects in the optional Archive Access and Deep Archive Access tiers still need a `RestoreObject` call before they can be read.
### Are S3 break-even points the same in every AWS region?
Not for the Standard comparison. Storage prices vary by region — Standard is $0.0245/GB-month in Frankfurt and $0.023 in N. Virginia — while retrieval prices are often identical. The Standard-IA against Glacier Instant Retrieval break-even happens to land at exactly 42.5% in both regions because the storage gap is $0.0085 in each, but that is coincidence, not a rule. Rerun the numbers for your region.
---
## WebSocket vs SSE vs Long Polling: The Real Cost of 1,000 Events
Author: Serdarcan Büyükdereli
Date: 2026-08-12
Category: DevOps Blog
URL: https://theinfinity.dev/articles/websocket-vs-sse-vs-polling
Delivering 1,000 events of roughly 117 bytes each costs 119,692 bytes over a WebSocket and 884,698 bytes over long polling. Same server, same event schedule, same payload. Long polling moved 7.4 times the traffic to deliver identical data.
Nearly two thirds of that long-polling total — 569,890 bytes — was HTTP request headers, re-sent 1,000 times. A single session cookie accounted for more of it than the events themselves.
This comparison usually gets decided from a table that says "bidirectional: yes/no" and nothing else. So I built the three transports in Node, put a byte-counting TCP proxy between client and server, and ran the same event stream through each. Every number below came out of that harness. Where I could not measure something, I say so.
The conclusion is not "use WebSockets." For most server-to-client feeds, SSE costs 10% more bytes than a WebSocket, gives you reconnection for free, and needs no new operational surface. That is usually the right trade.
## What does each transport cost on the wire?
Delivering the same 1,000 events costs 119,692 bytes over a WebSocket, 131,596 over SSE, and 884,698 over long polling with realistic browser headers. The gap is framing, not payload — every scenario carried the same ~116.9 KB of JSON.
| Transport | Total wire bytes | Bytes per event | × payload | TCP connections | HTTP requests |
|---|---|---|---|---|---|
| WebSocket (HTTP/1.1) | 119,692 | 119.7 | 1.02 | 1 | 0 |
| SSE (HTTP/1.1) | 131,596 | 131.6 | 1.13 | 1 | 1 |
| SSE (HTTP/2) | 134,534 | 134.5 | 1.15 | 1 | 1 |
| Long polling (HTTP/2) | 182,475 | 182.5 | 1.56 | 1 | 1,000 |
| Long polling (HTTP/1.1, keep-alive) | 884,698 | 884.7 | 7.57 | 1 | 1,000 |
| Long polling (HTTP/1.1, no keep-alive) | 851,691 | 851.7 | 7.29 | 1,000 | 1,000 |
| WebSocket + permessage-deflate | 30,434 | 30.4 | 0.26 | 1 | 0 |
The WebSocket number matches the spec arithmetic. [RFC 6455](https://www.rfc-editor.org/rfc/rfc6455#section-5.2) gives a server-to-client frame a 2-byte header for payloads up to 125 bytes, and my measured server-to-client overhead was 2.1 bytes per message — the extra tenth is the handful of messages whose timestamp pushed them past 125 bytes into a 4-byte header. There is nothing else on the wire: no headers, no status line, no cookie.
SSE costs 14.2 bytes per event. Eight of those are the wire format itself — `data: ` plus the blank-line terminator. The remaining six are HTTP/1.1 chunked transfer encoding, which wraps every write in a hex length and two CRLFs. That is the entire price of using a plain HTTP response instead of a binary frame.
Long polling pays 570 bytes of request headers and 198 bytes of response headers for each 117-byte event. Strip the browser headers down to what a bare Node client sends and the total falls to 406,710 bytes — better, but still 3.5× the payload, because the response headers and the request line never go away.
> ⚠️ **Watch out:** the no-keep-alive row looks cheaper (851,691 vs 884,698 bytes) only because `Connection: close` is a shorter string than `Connection: keep-alive`. It opened 1,000 TCP connections instead of 1, and my proxy counts TCP payload bytes only — not the SYN/ACK and FIN exchanges, and not a TLS handshake per connection. On HTTPS it is the most expensive row by a wide margin.
For a refresher on what a connection setup costs at the packet level, the [TCP/UDP visualizer](/simulators/tcp-udp-visualizer) walks through the handshake step by step.
## Does HTTP/2 fix long polling?
Mostly, yes. Moving long polling to HTTP/2 cut per-request header bytes from 570 to 36 — a 15.6× reduction — and the total from 884,698 bytes to 182,475. HPACK compresses the repeated header set down to references after the first request, so the cookie and user-agent stop being re-sent literally.
That changes the decision. Long polling on HTTP/2 costs 1.56× the payload, against 1.13× for SSE and 1.02× for a WebSocket. It is no longer absurd, merely mediocre. If you already terminate HTTP/2 at the edge and your event rate is low, the byte argument against long polling largely evaporates.
HTTP/2 does not make SSE cheaper, though — it made it slightly worse, 134,534 bytes against 131,596, because each DATA frame carries a 9-byte header where chunked encoding used about 6. The reason to run SSE over HTTP/2 is the connection limit, not bandwidth.
Browsers cap HTTP/1.1 at six connections per origin, and [MDN is blunt about what that does to SSE](https://developer.mozilla.org/en-US/docs/Web/API/Server-sent_events/Using_server-sent_events): the limit "is per browser and is set to a very low number (6)," shared across every tab pointed at the same domain. A user with seven tabs open has one tab that silently never connects. Over HTTP/2 the ceiling becomes the negotiated stream limit, which [RFC 9113 recommends](https://www.rfc-editor.org/rfc/rfc9113.html#name-defined-settings) be no smaller than 100. This is the most common way a working SSE implementation fails in production.
I could not measure WebSocket over HTTP/2 ([RFC 8441](https://www.rfc-editor.org/rfc/rfc8441) Extended CONNECT), because Node's built-in `http2` server does not implement it. That row is absent rather than estimated.
## Is WebSocket actually faster per message?
No. At one event every 100 ms over a simulated 50 ms round trip, all three transports delivered in about 26.5 ms — the difference between them was under 0.3 ms. Long polling only falls behind when events arrive faster than a round trip.
| Scenario (50 ms simulated RTT) | Mean | p50 | p95 | Max | Events per HTTP response |
|---|---|---|---|---|---|
| WebSocket, 1 event / 100 ms | 26.46 ms | 26.47 | 26.84 | 27.66 | — (frames) |
| SSE, 1 event / 100 ms | 26.52 ms | 26.56 | 26.91 | 27.10 | — (one stream) |
| Long polling, 1 event / 100 ms | 26.75 ms | 26.86 | 27.28 | 28.05 | 1.0 |
| WebSocket, 1 event / 20 ms | 26.16 ms | 26.25 | 26.82 | 27.40 | — (frames) |
| SSE, 1 event / 20 ms | 26.29 ms | 26.38 | 27.00 | 30.03 | — (one stream) |
| Long polling, 1 event / 20 ms | 52.44 ms | 51.95 | 76.96 | 80.37 | 2.5 |
The mechanism is a gap, not a protocol tax. A long-poll client is only listening while its request is parked on the server. The moment the server answers, the client is deaf for one full round trip while the response travels down and the next request travels back up. Events produced inside that window queue up and ship on the next poll. At one event per 100 ms the gap almost never catches one; at one event per 20 ms it catches two or three every cycle.
That batching is what saves long polling from collapsing — the client delivers in bursts instead of falling permanently behind. If your product tolerates bursts, a notification bell or an order status or a build log, long polling is not slow. If it does not, a cursor position or a trading tick, it is structurally wrong and no tuning fixes it.
Loopback hides all of this. Without the injected delay every transport measured well under a millisecond and long polling looked free. Benchmark real-time transports on localhost and you will conclude they are identical, right up until you deploy.
## What does a connection cost the server?
Holding 500 idle connections cost the Node server about 13 KB of RSS per WebSocket, 23 KB per SSE stream, and 21 KB per parked long-poll request. Across four repeat runs each figure varied by 1 KB per connection or less.
WebSockets came out cheapest, which surprised me and is worth stating plainly: 6.2-6.7 MB for 500 connections, against 11.0-11.2 MB for SSE and 10.3-10.9 MB for long polling. Once the `ws` library takes the socket over, Node's HTTP machinery is out of the picture. An open SSE response, by contrast, keeps an `IncomingMessage`, a `ServerResponse` and the HTTP parser state alive for as long as the stream lives.
Read that as a Node result, not a law of nature — a Go or Rust server would produce different ratios. What transfers is the shape of the problem: all three hold one open connection per client, so the file-descriptor and memory ceiling is the same order of magnitude. Long polling does not save you connections. A correct implementation parks the request server-side, which is exactly as open as an SSE stream.
## When is SSE enough?
SSE is enough whenever the data flows server to client, is text, and the client does not need to send anything back over the same channel. That covers notifications, live dashboards, progress and log streams, LLM token streaming, and price feeds — most of what people reach for WebSockets to build.
What you get for that 10% byte premium is reconnection you do not have to write. The [HTML specification](https://html.spec.whatwg.org/multipage/server-sent-events.html) requires `EventSource` to reconnect on its own, and to send the last received `id` back as a `Last-Event-ID` request header. Your server reads that header and resumes from the right point. The server can tune the delay by sending a `retry:` field. With a WebSocket, you write the reconnect loop, the backoff, the resume cursor and the duplicate suppression yourself — every time.
The limits are real and worth knowing before you commit:
- **One direction only.** MDN states it flatly: "This is a one-way connection, so you can't send events from a client to a server." Client-to-server messages go over ordinary `fetch` calls, which is fine for low-rate actions and bad for high-rate ones.
- **UTF-8 text only.** The spec requires event streams to be encoded as UTF-8. Binary means base64, which costs 33% before any framing.
- **No custom request headers.** `EventSource` takes a URL and `withCredentials`; there is no header option. Bearer-token auth needs a cookie, a query parameter, or a `fetch`-based polyfill.
- **Six connections per origin** under HTTP/1.1, as covered above.
```javascript
// The whole client, including resume-after-disconnect.
const es = new EventSource('/events', { withCredentials: true });
es.addEventListener('trade', (e) => {
render(JSON.parse(e.data));
});
// No reconnect handler needed: the browser retries and replays
// the last id back as the Last-Event-ID request header.
```
```javascript
// Server side: emit an id so the browser can resume, and tell it how
// long to wait before retrying.
res.writeHead(200, {
'Content-Type': 'text/event-stream',
'Cache-Control': 'no-store',
'X-Accel-Buffering': 'no', // nginx buffers proxied responses by default
});
res.flushHeaders();
res.write('retry: 2000\n\n');
function send(event, id, data) {
res.write(`id: ${id}\nevent: ${event}\ndata: ${JSON.stringify(data)}\n\n`);
}
```
An `id:` line costs about 11 more bytes per event at five-digit ids. On my numbers that moves SSE from 14.2 to roughly 25 bytes of overhead per event — still a fraction of long polling's 768.
## What breaks these in production?
Idle timeouts break them, and they break SSE and WebSocket alike because both depend on a connection nobody is talking on. An [Application Load Balancer defaults to a 60-second connection idle timeout](https://docs.aws.amazon.com/elasticloadbalancing/latest/application/edit-load-balancer-attributes.html) — "the period of time an existing client or target connection can remain inactive, with no data being sent or received, before the load balancer closes the connection" — configurable from 1 to 4,000 seconds. [Cloudflare](https://developers.cloudflare.com/network/websockets/) supports WebSockets on all plans and likewise "will close a WebSocket connection when no data is transmitted in either direction for a period of time."
The fix is a heartbeat, and the SSE spec spells out the cheap version: send a comment line starting with `:` every 15 seconds or so. A line starting with a colon is ignored by the client and costs a handful of bytes. WebSockets have protocol-level ping/pong frames for the same job. Note that ALB documents one gap here: it "does not support HTTP/2 PING frames. These do not reset the connection idle timeout."
The second classic failure is buffering. Nginx ships with [`proxy_buffering on` by default](https://nginx.org/en/docs/http/ngx_http_proxy_module.html#proxy_buffering), which means it collects the response before forwarding it. An SSE stream behind default nginx config arrives all at once, at the end, or never. The response header `X-Accel-Buffering: no` disables it per response, which is why it is in the snippet above.
> ⚠️ **Watch out:** these two failures look identical from the browser — a stream that connects and then goes quiet. Check the proxy before you rewrite the application. A stream that dies at a suspiciously round interval (60 s, 100 s) is a timeout; a stream that delivers everything in one burst at the end is buffering.
The third is fan-out. All three pin a client to one server process, so an event produced on instance B has to reach a client connected to instance A. That means Redis pub/sub, a message bus, or sticky routing — and it is the same problem for all three. Choosing long polling to dodge it does not work, because a parked request is just as pinned.
## Which one should you actually pick?
Pick by the direction and rate of your data, not by which protocol sounds most modern.
| Requirement | Choose | Why |
|---|---|---|
| Server → client, text, any rate | **SSE** | 1.13× payload, reconnect and resume are free |
| Client → server at high rate (cursors, presence, collab editing, games) | **WebSocket** | SSE cannot send upstream; a `fetch` per keystroke is worse than long polling |
| Binary frames (audio, video, protobuf, CBOR) | **WebSocket** | SSE is UTF-8 only, base64 costs 33% |
| Bandwidth-critical, high message rate | **WebSocket + permessage-deflate** | Measured 30,434 bytes for the same 1,000 events, 0.26× payload |
| Under ~1 event/second, HTTP/2 edge already in place | **Long polling** | 1.56× payload, no new operational surface, works through anything |
| Intermediary strips `Upgrade` headers | **SSE or long polling** | Both are ordinary HTTP responses |
| Many tabs, HTTP/1.1 only | **WebSocket** | SSE hits the six-connection cap |
| Per-request auth headers required | **WebSocket or fetch-based polyfill** | `EventSource` cannot set headers |
The honest default for a server-to-client feed is SSE. The 10% byte premium over a WebSocket buys reconnection, resume, plain-HTTP debuggability and no second protocol in your stack. Reach for a WebSocket when you genuinely need the upstream channel or binary frames — and if you find yourself building a reconnect-with-resume loop over a WebSocket for a one-way feed, you have reimplemented SSE badly.
## How I measured this
Everything above came from one harness, run locally on an Apple M5 (32 GB) under macOS 26.6.1, Node v26.6.0, `ws` 8.21.3. No remote servers were involved.
One Node process serves the same event stream three ways: a `ws` WebSocket endpoint, a `text/event-stream` response, and a `/poll?cursor=N` endpoint that parks the request until an event exists. A control port on a separate socket starts each run and reports server-side counters, so control traffic never pollutes the measurement.
**Byte counting.** A TCP proxy sits between client and server and counts every byte in both directions. These are real wire bytes at the TCP payload level: request lines, headers, chunked-encoding markers, WebSocket frame headers. Not counted: TCP/IP packet headers, ACKs, handshake and teardown packets, and TLS. Those exclusions all favour long polling, so its numbers here are optimistic.
**Event stream.** 1,000 events, one every 3 ms, each a JSON object averaging 116.9 bytes (`{"id":7,"ts":...,"type":"trade","sym":"ADAUSDT","px":60009.59,...}`). Varied rather than filler text, so the permessage-deflate result is not fake. Server compression was off; at ~117-byte bodies gzip usually costs more than it saves.
**Header profiles.** Every transport ran twice — once with a bare `Accept: */*`, once with the header set a real Chrome tab sends, cookie and user-agent included. Both profiles hit all three transports, so WebSocket and SSE pay the same handshake cost. They just pay it once.
**Latency.** The cross-process clock problem is solved with `performance.timeOrigin + performance.now()`, a high-resolution epoch timestamp comparable across processes on one host. The server stamps each event at emit, the client subtracts on receive. The proxy injects a fixed 25 ms one-way delay in each direction to emulate a 50 ms round trip.
**Memory.** 500 idle clients, no events flowing, server RSS after two forced GC passes with `--expose-gc`, repeated four times. Only the server process is measured.
**Reproducibility.** An independent re-run of the byte benchmark landed within 0.1% on every row — the largest gap was 317 bytes out of 406,710. That residual comes from the timestamp field changing digit count between runs, not from the transports.
**What I did not measure:** CPU under load, throughput ceilings, behaviour past 500 connections, TLS handshake cost, HTTP/3, WebSocket over HTTP/2, real WAN jitter and packet loss (my delay is fixed and lossless), mobile radio wake-up cost, and anything at all about browser-side performance. The latency figures come from a simulated network, not a real one — treat the shape as transferable and the absolute numbers as not.
## FAQ
### Is SSE slower than WebSocket?
No. In my measurements SSE delivered events in 26.29-26.52 ms mean against WebSocket's 26.16-26.46 ms over a simulated 50 ms round trip — a difference of well under half a millisecond. SSE costs about 10% more bytes on the wire, but the per-message delivery delay is effectively the same.
### Can SSE send data from client to server?
Not over the same connection. SSE is one-way by design; the client sends data with ordinary `fetch` or `XMLHttpRequest` calls. That is fine for occasional actions like a button click, and a poor fit for high-rate upstream data like cursor positions or keystrokes, where a WebSocket is the right tool.
### Does long polling still make sense in 2026?
Yes, in two situations. If your event rate is below roughly one per second and you already terminate HTTP/2 at the edge, it costs 1.56× the payload and needs no new operational surface. It is also the fallback that survives intermediaries that strip `Upgrade` headers or buffer streaming responses.
### Why does my SSE stream arrive all at once at the end?
Something in the path is buffering the response. Nginx enables `proxy_buffering` by default, so it collects the proxied response before forwarding. Send the `X-Accel-Buffering: no` response header from your application, or set `proxy_buffering off` for that location.
### Why does my SSE connection die after exactly 60 seconds?
An idle timeout is closing it. AWS Application Load Balancer defaults to 60 seconds of no data in either direction, and Cloudflare closes idle WebSocket connections on a similar principle. Send a comment line (`:heartbeat\n\n`) every 15 seconds or so; the SSE spec designed comment lines for exactly this, and the client ignores them.
### How many SSE connections can a browser hold?
Six per origin under HTTP/1.1, shared across all tabs. That limit applies to all HTTP/1.1 connections to the domain, not just SSE, so a user with several tabs open will find one that silently never connects. Serving over HTTP/2 raises the ceiling to the negotiated stream limit, which RFC 9113 recommends be at least 100.
### Does permessage-deflate make WebSockets always better?
It made the same 1,000 events cost 30,434 bytes instead of 119,692 in my run, a 74% reduction — but that is a property of compressible JSON, not of WebSockets. An SSE stream with gzip enabled should compress comparably, though I did not measure that. Compression also costs CPU and per-connection memory for the deflate context, which matters more than bandwidth at high connection counts.
## The part worth remembering
The byte table is the interesting result, and it does not point where people expect. Long polling on HTTP/1.1 is genuinely bad — 7.4× the payload, two thirds of it request headers re-sent a thousand times. But on HTTP/2 that collapses to 1.56×, and at a low event rate its latency was indistinguishable from a WebSocket. Most of what long polling gets blamed for is HTTP/1.1's header handling, not the polling pattern.
And WebSocket's win over SSE is 10% of bytes. That is the whole margin. Against it you are trading a protocol your proxies understand for one they might not, a `Last-Event-ID` header that resumes for free against a reconnect loop you maintain, and a curl-able endpoint for a binary frame you cannot read in a terminal. Ten percent does not buy that.
Build the SSE version first. Move to WebSockets the day you need to send something upstream, and not before.
---
## Amazon S3 for the Solutions Architect Exam: What Actually Gets Tested
Author: Serdarcan Büyükdereli
Date: 2026-08-07
Category: DevOps Blog
URL: https://theinfinity.dev/articles/amazon-s3-saa-c03-exam-guide
SAA-C03 has four domains: secure architectures (30%), resilient architectures (26%), high-performing architectures (24%) and cost-optimized architectures (20%). S3 is the one service that can plausibly appear in all four. It is a security question when it is about bucket policies and encryption, a resilience question when it is about versioning and replication, a performance question when it is about multipart uploads and prefixes — and, more than anything else, a cost question.
Work through any large set of practice questions and roughly one in four will involve S3 somewhere in the scenario, usually alongside EC2, Lambda, CloudFront or a VPC. Of those, the clear majority end with some variation of *most cost-effective* or *least operational overhead*.
That is the reason studying S3 as a feature list does not work. The exam rarely asks what S3 *is*. It asks which class, which rule, which endpoint, which key. Then it makes the difference between two answers that both look correct come down to a number: 30 days, 128 KB, 5 GB, 15 minutes.
This guide walks those decisions in roughly the order the exam presents them. Then it covers something no practice test can teach you: the S3 defaults that changed in 2025 and 2026, long after SAA-C03 was written.
## All of S3, one sentence at a time
Before the decisions, the map. S3 is no longer a single thing with a few pricing tiers — there are four kinds of bucket and eight storage classes, and knowing which is which stops half the confusion.
**The four bucket types:**
- **General purpose bucket** — the classic S3 bucket, unlimited objects, every storage class available; this is what an exam question means when it says "an S3 bucket".
- **Directory bucket** — the bucket type behind S3 Express One Zone, holding data in a single Availability Zone with a hierarchical namespace for the lowest possible latency.
- **Table bucket** — stores Apache Iceberg tables as a managed resource, with compaction and snapshot maintenance handled by S3 itself.
- **Vector bucket** — stores and queries embedding vectors natively, built for semantic search and for giving AI agents long-term memory.
**The eight storage classes:**
- **S3 Standard** — frequently accessed data across at least three AZs, with no minimum duration and no retrieval fee.
- **S3 Intelligent-Tiering** — Standard's durability plus automatic movement between tiers, for data whose access pattern you cannot predict.
- **S3 Standard-IA** — millisecond access for data read roughly once a month, trading a 30-day minimum and a retrieval fee for cheaper storage.
- **S3 One Zone-IA** — the same economics in a single AZ, about 20% cheaper, and safe only for data you can recreate.
- **S3 Glacier Instant Retrieval** — archive pricing with millisecond reads, for data touched a few times a year, with a 90-day minimum.
- **S3 Glacier Flexible Retrieval** — cheaper archive storage where a restore takes anywhere from 1–5 minutes to 12 hours.
- **S3 Glacier Deep Archive** — the lowest storage price S3 offers, with a 180-day minimum and restores measured in 12 to 48 hours.
- **S3 Express One Zone** — single-digit-millisecond storage in one AZ, for workloads that read the same data over and over.
The exam lives almost entirely in the general purpose bucket and the first seven classes. The rest is what you will meet at work.
## What the exam actually asks about S3
Almost every S3 question is one of three shapes. Recognising which one you are looking at before you read the answer options cuts the list in half.
- **"Data is written once, read rarely, must be kept for N years — cheapest option?"** A storage class plus a lifecycle rule. The trap is always a minimum storage duration or a retrieval fee that the cheap-looking option quietly carries.
- **"The bucket must not be reachable from the internet."** Block Public Access, a bucket policy, and usually a gateway VPC endpoint. The trap is an answer that solves it with an ACL or with a NAT gateway.
- **"An on-premises system produces X TB and it has to land in S3."** DataSync, Storage Gateway, Snowball, or Transfer Family. The trap is bandwidth arithmetic the question expects you to do.
Underneath all three sits the same instruction, phrased two ways: *most cost-effective* and *least operational overhead*. When both appear in the same question, managed beats self-built, and per-GB-month beats per-request — unless the access pattern makes retrieval fees dominate.
## Which S3 storage class does the question want?
Start from access frequency, not from price. The class you pick determines the minimum storage duration you get billed for, and that minimum is what most cost questions actually turn on.

The numbers behind the tree, which are worth memorising verbatim:
| Storage class | AZs | Min. duration | Min. billable size | First byte |
|---|---|---|---|---|
| S3 Standard | ≥3 | none | none | milliseconds |
| S3 Intelligent-Tiering | ≥3 | none | 128 KB | ms (archive tiers: min/hrs) |
| S3 Standard-IA | ≥3 | 30 days | none | milliseconds |
| S3 One Zone-IA | 1 | 30 days | none | milliseconds |
| S3 Glacier Instant Retrieval | ≥3 | 90 days | 128 KB | milliseconds |
| S3 Glacier Flexible Retrieval | ≥3 | 90 days | none | 1–5 min to 12 h |
| S3 Glacier Deep Archive | ≥3 | 180 days | none | 12–48 h |
| S3 Express One Zone | 1 | 1 hour | none | single-digit ms |
Two traps the exam likes:
**One Zone-IA is not "cheaper IA".** It stores data in a single Availability Zone. If that AZ is lost, the data is gone. It is the right answer only when the data can be regenerated — thumbnails, transcoded renditions, secondary copies. If the question says "critical" or "cannot be recreated", One Zone is a distractor no matter how attractive the price.
**Intelligent-Tiering is the answer to "unknown or changing access pattern"**, not to "cheapest". It charges a small monitoring fee per object and moves objects between tiers automatically, with no retrieval fee for the frequent and infrequent tiers. For a known, stable pattern, a lifecycle rule to a fixed class is cheaper.
For restores, know the tiers: Expedited gets objects under 250 MB back in **1–5 minutes** from Glacier Flexible Retrieval, Standard takes **3–5 hours**, and Bulk **5–12 hours**. Deep Archive has no Expedited option at all: Standard is within **12 hours**, Bulk within **48 hours**. When a question offers "restore in minutes" for Deep Archive, that option is wrong by definition.
## Lifecycle: the rule most cost questions turn on
A lifecycle rule moves objects **down** the cost ladder on a schedule and deletes them at the end. It never moves them back up — a "restore" from Glacier produces a temporary copy, and putting an object back in Standard permanently means rewriting it as a new object.

```json
{
"Rules": [{
"ID": "logs-archive-and-expire",
"Filter": { "Prefix": "logs/" },
"Status": "Enabled",
"Transitions": [
{ "Days": 30, "StorageClass": "STANDARD_IA" },
{ "Days": 90, "StorageClass": "GLACIER" },
{ "Days": 365, "StorageClass": "DEEP_ARCHIVE" }
],
"Expiration": { "Days": 2555 },
"AbortIncompleteMultipartUpload": { "DaysAfterInitiation": 7 }
}]
}
```
Four things that go wrong in real accounts and in exam answers:
**Early deletion still costs.** Move an object to Standard-IA on day 30 and delete it on day 40, and you pay for 30 days of IA storage anyway. A rule that transitions data with a shorter real lifetime than the class minimum makes the bill go up, not down.
**Small objects get more expensive.** Glacier Instant Retrieval and Intelligent-Tiering bill objects under 128 KB as if they were 128 KB. Archiving millions of tiny files is a classic own goal — aggregate them first.
**Versioning needs its own rule.** With versioning on, the rule you wrote applies to current versions. Noncurrent versions keep accumulating until you add `NoncurrentVersionTransition` and `NoncurrentVersionExpiration`. This is one of the most common sources of "why is my bucket 4× the size of my data".
**Incomplete multipart uploads are invisible and billable.** Failed uploads leave parts behind that do not show up in a normal object listing but do show up on the bill. `AbortIncompleteMultipartUpload` with 7 days belongs in every bucket policy you ever write. S3 Storage Lens will point at buckets that lack it.
## Who is allowed to read the bucket?
Access to an S3 object is evaluated across several layers, and the order matters: an explicit `Deny` anywhere wins, and Block Public Access overrides everything that would grant public access.
- **Block Public Access** — on by default for new buckets, at the account and bucket level. When a question describes an accidentally public bucket, BPA is almost always part of the answer.
- **Bucket policy** — resource-based, attached to the bucket. This is where cross-account access, `aws:SecureTransport`, VPC endpoint conditions and IP restrictions live.
- **IAM identity policies** — what a principal in *your* account is allowed to do.
- **VPC endpoint policies, SCPs, RCPs** — organisational guardrails on top.
- **ACLs** — disabled by default since April 2023 under the *bucket owner enforced* setting. Modern buckets manage access with policies only. If an answer option hands out permissions with an object ACL, treat it with suspicion.
Two mechanisms come up constantly and are worth being precise about:
**Presigned URLs** grant temporary access to a single object using the credentials of whoever generated the URL. This is the answer for "let a user download a private file without giving them an AWS identity". The expiry is bounded by the credentials that signed it — up to 7 days with IAM user credentials, but only as long as the session for temporary credentials.
**CloudFront with Origin Access Control (OAC)** is the answer for "serve private S3 content globally through a CDN". OAC replaced Origin Access Identity (OAI); OAI still appears in older questions and still works, but nothing new should use it. The bucket stays private, and the bucket policy trusts the CloudFront distribution.
### Gateway endpoint or interface endpoint?
The phrase "traffic must not traverse the internet" turns up constantly, and for S3 the cheapest correct answer is a **gateway endpoint**: it adds a route table entry, costs nothing, and keeps S3 traffic on the AWS network.
An interface endpoint (PrivateLink) also works, and it is the right answer when the traffic comes from on-premises over Direct Connect or VPN, or when you need a private IP inside the VPC — but it is billed per hour and per GB. When both appear as options and the question emphasises cost with no on-premises component, gateway is the answer.
## Encryption: four server-side options, one of them already on
Every S3 bucket has encryption at rest by default. Since January 2023, **SSE-S3 (AES-256) is applied automatically** to every new object with no configuration and no extra cost. Any answer option that presents "enable encryption at rest" as the work to be done is describing something S3 already did.
| Option | Key management | When it's the right answer |
|---|---|---|
| SSE-S3 | AWS, invisible | Default. No compliance requirement about key custody |
| SSE-KMS | Your KMS key | Audit trail of key usage, key rotation, per-key access control |
| DSSE-KMS | Your KMS key, two layers | Explicit dual-layer requirement (some regulated workloads) |
| SSE-C | You send the key per request | Rare. You must hold the key; AWS services cannot read the object |
| Client-side | You, before upload | Data must be encrypted before it ever reaches AWS |
The exam's tell for **SSE-KMS** is any mention of auditing key usage, rotating keys, or restricting who can decrypt independently of who can read the object. Its trap is throttling: every object read triggers a KMS call. Enable **S3 Bucket Keys** and those calls drop by up to 99%, which is also the answer to "KMS request costs are too high".
> ⚠️ **New in April 2026:** S3 now disables SSE-C by default on all new general purpose buckets, and on existing buckets in accounts that have no SSE-C objects. Requests that specify SSE-C get a 403. It must be enabled deliberately. Exam questions still treat SSE-C as a freely available option.
## Keeping data safe: versioning, Object Lock, replication
**Versioning** keeps every variant of an object. It is a prerequisite for replication and for Object Lock, and it is the answer to "recover from accidental deletion" — a delete on a versioned bucket writes a delete marker rather than removing data.
**MFA Delete** requires a second factor to permanently delete a version or to suspend versioning. It can only be enabled by the bucket owner using root credentials, which is exactly the detail questions test.
**Object Lock** implements write-once-read-many. Two modes, and the difference is the whole question:
- **Governance mode** — users with the `s3:BypassGovernanceRetention` permission can remove the lock. Protection against accident.
- **Compliance mode** — nobody can shorten the retention or delete the object, including the root user, until the period expires. Protection against a regulator. When a question says "not even an administrator", the answer is compliance mode.
**Replication** copies objects to another bucket, asynchronously, in the same Region (SRR) or across Regions (CRR). Both buckets need versioning. Replication is not retroactive: existing objects need S3 Batch Replication. If the requirement includes a time guarantee, that is **Replication Time Control** — 99.99% of objects within 15 minutes, backed by an SLA.
## Performance answers you can memorise
- **Multipart upload** — recommended above 100 MB, required above 5 GB. Maximum 10,000 parts, each 5 MiB to 5 GiB. It also enables parallel and resumable uploads. Any question about improving upload throughput for large files starts here.
- **S3 Transfer Acceleration** — routes uploads through the nearest CloudFront edge location. The answer for "users worldwide upload to one bucket and it's slow". Not for downloads, and not for traffic already inside AWS.
- **Byte-range fetches** — parallel ranged GETs to speed up downloads, and to read just the header of a large object.
- **Request rates** — 3,500 PUT/COPY/POST/DELETE and 5,500 GET/HEAD per second **per partitioned prefix**, with no limit on prefix count. Spreading keys across prefixes scales the rate linearly. (The old "randomise your key prefix" advice is obsolete — S3 has handled sequential keys fine since 2018.)
- **S3 Express One Zone** — single-digit millisecond latency in one AZ via directory buckets, for workloads that hammer the same data repeatedly. Rare in current questions; increasingly common in real architectures.
## Getting data in: the on-premises questions
Moving data from a datacentre into S3 is a whole question family. Three services, three distinct signals:
| Signal in the question | Answer |
|---|---|
| Recurring or one-off transfer over the network, keep metadata, verify integrity | **AWS DataSync** |
| Applications must keep using NFS/SMB while data lands in S3 | **Storage Gateway (File Gateway)** |
| Petabytes, limited bandwidth, "would take months over the network" | **AWS Snowball** |
| SFTP/FTPS clients that cannot be changed | **AWS Transfer Family** |
Do the arithmetic when bandwidth is given: 100 TB over a 1 Gbps link that is fully saturated takes roughly 9 days. Question writers pick numbers where the network option is obviously absurd or obviously fine.
## What changed after the exam was written
SAA-C03 launched in 2022, and the study material built around it is older still. Several S3 facts that are treated as correct answers are no longer true of the service you would build on today.

The ones worth knowing, with dates:
- **Maximum object size is 50 TB**, up from 5 TB, announced 2 December 2025 and supported in every storage class.
- **S3 Select is closed to new customers** as of 25 July 2024. AWS points you at Athena. S3 Object Lambda followed, limited to existing customers from 7 November 2025. Older material still presents S3 Select as the answer for "run SQL against a single object".
- **The default bucket quota is 10,000 per account**, not 100. Above that, `ListBuckets` must be paginated.
- **ACLs are disabled and encryption is on** for new buckets, as covered above.
- **S3 has grown a data platform**: S3 Tables (managed Apache Iceberg), S3 Metadata (queryable object metadata), S3 Vectors (vector storage at up to 90% lower cost, GA at re:Invent 2025), and S3 Files (buckets mounted as file systems, announced April 2026). None of this is on the exam. All of it will come up in an interview.
> 💡 **How to hold both:** answer the exam question the way SAA-C03 expects, and note the modern answer separately. Studying without that split teaches you facts you will have to unlearn on your first real project.
## The S3 cheatsheet: phrase in, answer out
Exam questions reuse a small vocabulary. Once you can hear the phrase, the answer usually follows without much reasoning. These are the ones worth recognising on sight — the wording on the left is close to how the exam actually writes it.
**Choosing where the data lives**
| The question says | Answer | Why |
|---|---|---|
| object storage · static website hosting · data lake · durable and virtually unlimited | Amazon S3 | Eleven nines of durability, no capacity planning |
| access pattern is unknown or changes over time | S3 Intelligent-Tiering | Automatic tiering, no retrieval fee in the main tiers |
| rarely accessed · retrieval in minutes to hours · lowest cost · retain for 7 years | Glacier Flexible Retrieval or Deep Archive | Deep Archive is cheapest; 12–48 h restore |
| accessed a few times a year but must return instantly | Glacier Instant Retrieval | Archive pricing, millisecond reads, 90-day minimum |
| reproducible data · cost matters more than an AZ failure | One Zone-IA | Single AZ, ~20% cheaper, only for recreatable data |
| move to a cheaper tier after 30/90 days, then delete | S3 Lifecycle policy | Age-based transitions beat manual housekeeping |
| high performance computing · ML training data · linked to an S3 bucket | FSx for Lustre | POSIX throughput with an S3 link |
**Protecting and restricting it**
| The question says | Answer | Why |
|---|---|---|
| cannot be deleted or overwritten · WORM · compliance or governance mode | Object Lock + versioning | Compliance mode blocks even the root user |
| recover from accidental deletion or overwrite | Versioning | Deletes write a marker, not a hole |
| without traversing the public internet | Gateway VPC endpoint | Free, route-table based, S3 and DynamoDB only |
| serve private content globally with low latency | CloudFront + OAC | Bucket stays private, distribution is trusted |
| let one user download one private file, no AWS account | Presigned URL | Time-bounded, signed with the creator's credentials |
| audit who used the key · rotate keys · restrict decrypt separately | SSE-KMS (+ S3 Bucket Keys) | CloudTrail visibility; Bucket Keys cut KMS calls up to 99% |
| encrypted before it ever reaches AWS · end-to-end | Client-side encryption | AWS never sees plaintext or the key |
| discover PII or credit card data sitting in S3 | Amazon Macie | Managed sensitive-data discovery |
| replicate to another Region for compliance or DR | CRR (versioning on both sides) | Same Region is SRR; add RTC for the 15-minute SLA |
**Getting data in and querying it**
| The question says | Answer | Why |
|---|---|---|
| terabytes · fast internet available · uploads from around the world | Transfer Acceleration + multipart | Edge locations absorb the distance |
| petabytes · limited bandwidth · would take months over the network | AWS Snowball | Physical shipping beats the link |
| on-premises NFS/SMB share · applications keep using it | Storage Gateway (File Gateway) | Local cache, S3 backend, no app changes |
| scheduled or incremental copy from on-premises, keep metadata | AWS DataSync | Purpose-built transfer with verification |
| managed SFTP/FTPS · partners upload files directly into S3 | AWS Transfer Family | Protocol front end, S3 storage |
| replace physical tape backup · virtual tape library | Storage Gateway (Tape Gateway) | VTL interface, Glacier behind it |
| near real-time delivery of streaming data into S3 | Kinesis Data Firehose | Buffered managed delivery, no shard management |
| run SQL directly on data in S3 · serverless · pay per data scanned | Amazon Athena | The current answer; S3 Select is closed to new customers |
| retain logs long term at low cost and query them later | Export to S3, query with Athena | Cheap storage plus on-demand SQL |
**Four traps that look right and are not**
- **Snowball when the link is fast.** Snowball is the answer for *limited bandwidth*. With a healthy internet connection, Transfer Acceleration or DataSync is faster and simpler.
- **EC2 and a load balancer for static content.** Static files are an object storage problem: S3 plus CloudFront, no servers.
- **One Zone-IA for anything critical.** The price looks best right up until the AZ is gone.
- **"Enable encryption at rest" as the work item.** It has been on by default since January 2023 — if that is the whole answer, the answer is doing nothing.
## FAQ
### How much of the SAA-C03 exam is about S3?
AWS does not publish a per-service breakdown, but S3 touches all four exam domains — security, resilience, performance and cost — and storage appears in the task statements of each. In practice, around a quarter of practice questions involve S3 somewhere in the scenario, which makes it one of the two or three services you cannot afford to be shaky on, alongside VPC networking and EC2.
### Which S3 storage class is cheapest?
S3 Glacier Deep Archive has the lowest per-GB storage price, but it has a 180-day minimum storage duration and restores take 12 to 48 hours. Cheapest *for a workload* depends on how long objects live and how often they are read — an object read weekly costs far more in Deep Archive, once retrieval fees are counted, than it does in Standard.
### What is the difference between S3 Standard-IA and One Zone-IA?
Both are for infrequently accessed data with millisecond retrieval and a 30-day minimum duration. Standard-IA stores data across at least three Availability Zones; One Zone-IA uses a single AZ and costs about 20% less. Use One Zone-IA only for data you can recreate.
### Do I need to enable encryption on an S3 bucket?
No. Since January 2023 all new objects are encrypted with SSE-S3 by default in every bucket. You configure encryption only to choose a different mode — SSE-KMS for key auditing and access control, DSSE-KMS for dual-layer requirements, or client-side encryption.
### When should you use Intelligent-Tiering instead of a lifecycle rule?
Use Intelligent-Tiering when the access pattern is unknown or changes over time; it moves objects between tiers automatically and charges no retrieval fee for the frequent and infrequent tiers. Use an explicit lifecycle rule when the pattern is predictable — it avoids the per-object monitoring charge.
### Is S3 Select still the right answer for querying S3 data?
Not for anything new. S3 Select has been closed to new customers since 25 July 2024, and AWS recommends Amazon Athena. Older exam material still keys S3 Select, so answer it that way on the exam and use Athena in production.
## How to study S3 for SAA-C03
Memorise the numbers that decide questions — 30 / 90 / 180 day minimums, the 128 KB billing floor, the 5 GB multipart threshold, 3,500 and 5,500 requests per prefix, the 15-minute RTC SLA. These are what separate two answer options that otherwise read identically.
Then build one bucket and watch it work: enable versioning, write a lifecycle rule with a noncurrent expiration, upload a 200 MB file and observe the multipart parts, turn on a gateway endpoint and confirm the traffic leaves the internet route. An hour of that fixes more wrong answers than a day of flashcards.
And be careful with practice questions from unofficial sources. Where a keyed answer and the community consensus disagree, the question is usually ambiguous or out of date rather than hard — verify anything that matters against the AWS documentation instead of memorising a disputed key.
Keep the two mental models separate: what SAA-C03 expects, and what S3 does in 2026. The exam rewards the first. Your next architecture review rewards the second.
---
## Self-hosting DeerFlow 2.0: a complete setup guide
Author: The Infinity Team
Date: 2026-03-27
Category: Open Source
URL: https://theinfinity.dev/articles/self-hosting-deerflow-2-complete-setup-guide
## Self-hosting DeerFlow 2.0: a complete setup guide
DeerFlow 2.0, released by ByteDance on March 25, 2026, hit #1 on GitHub Trending within 48 hours. It gives your AI agent an actual computer to work in: an isolated Docker sandbox with a shell, a browser, a persistent filesystem, and the ability to spawn sub-agents for long-horizon tasks. If you've been watching n8n and OpenClaw and wondering what comes next, this is the tool worth your weekend.
This guide covers the full self-hosted setup — Docker deployment, model provider configuration, and the architectural decisions that will save you hours of debugging. No managed cloud account required.
---
## What DeerFlow 2.0 actually does
Most "AI agent" tools are wrappers around a single LLM with tool access. DeerFlow operates as a SuperAgent harness: a coordinator that plans tasks, spawns sub-agents to handle discrete parts, and executes everything inside a sandboxed environment rather than on your host machine.
The sandbox is the key distinction. Each agent session gets its own Docker container with a full filesystem, a bash terminal, and a browser. When DeerFlow runs a coding task, the code executes inside that container — not on your server. That isolation matters if you're running untrusted tasks, processing user-submitted data, or just want clean rollback behavior.
DeerFlow is built on LangGraph and LangChain. It ships with a planning layer, a memory system for multi-session context, a skill registry for reusable capabilities, and a message gateway for coordinating between sub-agents. The web interface runs on port 2026 locally — but under the hood, each message kicks off an agent workflow, not a single LLM call.
### The architecture in three layers
| Layer | What it does | Key components |
| --- | --- | --- |
| Orchestration | Plans and coordinates tasks across agents | Planner, sub-agent spawner, task queue |
| Execution | Runs code, shell commands, browser actions | Docker sandbox per session |
| Memory & Tools | Retrieves context, calls APIs, performs search | Memory store, Tavily search, MCP integrations |
The repo gained approximately 12,000 stars in the 48 hours following the March 25 release. ([byteiota.com](https://byteiota.com/deerflow-2-0-bytedance-ai-agent-framework-hits-1-github/))
---
## Hardware and prerequisites
DeerFlow is not a lightweight tool. The sandbox spins up Docker containers per session, and if you're running models locally via Ollama, you need enough VRAM to keep the planner model loaded while sub-agents execute.
Minimum tested setup:
- 16 GB RAM (24 GB recommended for local models)
- Docker and Docker Compose
- Python 3.12+, Node.js 22+
- Tavily API key (free tier covers personal use)
- At least one LLM API key: OpenAI, Anthropic, DeepSeek, or a local Ollama endpoint
Running a 14B planner and a 7B sub-agent model puts peak usage around 20 GB. For cloud API users, DeepSeek V3 at $0.0014 per 1,000 input tokens is approximately 50× cheaper than GPT-4o — with no meaningful quality gap on factual research tasks.
---
## Self-hosted DeerFlow 2.0 setup with Docker
### Clone and configure
```bash
git clone https://github.com/bytedance/deer-flow.git
cd deer-flow
make config
```
`make config` generates `config.yaml` and `.env`. Minimal `config.yaml`:
```yaml
llm:
model: gpt-4o
api_key: ${OPENAI_API_KEY}
tools:
search:
provider: tavily
api_key: ${TAVILY_API_KEY}
sandbox:
enabled: true
image: ghcr.io/bytedance/deer-flow-sandbox:latest
```
Set credentials in `.env`:
```bash
OPENAI_API_KEY=sk-...
TAVILY_API_KEY=tvly-...
```
### Choose your model provider
| Provider | Planner model | Cost per 1K tokens | Notes |
| --- | --- | --- | --- |
| OpenAI | gpt-4o | $0.005 | Best instruction-following |
| Anthropic | claude-sonnet-4-6 | $0.003 | Strong at long-context reasoning |
| DeepSeek | deepseek-v3 | $0.0014 | Best price-to-quality ratio |
| Ollama (local) | qwen2.5:32b | $0 | Requires 24 GB+ VRAM |
### Initialize and launch
```bash
make docker-init # pulls sandbox images (~2–5 min first run)
make docker-start # starts all services
```
Open `http://localhost:2026`. The task decomposition sidebar — showing which sub-agent handles which slice in real time — is the best diagnostic tool in the UI.
To stop: `make docker-stop`. Logs: `make docker-logs`.
---
## DeerFlow 2.0 vs. alternatives: where it fits
The self-hosted agent space has three archetypes:
1. **Visual workflow builders** (n8n, Dify) — repeatable processes, low technical floor
2. **Local LLM runners** (Ollama + Open WebUI) — chat and simple tool use, minimum infra
3. **SuperAgent harnesses** (DeerFlow) — complex, long-horizon tasks that need real execution
DeerFlow is overkill for "summarize this document." It is exactly right for "research this topic, write the code to analyze it, run the analysis, and produce a report."
Versus AutoGen or CrewAI: both require custom Python code per workflow. DeerFlow ships as a complete system with UI, sandbox, and pre-built skills — you trade flexibility for speed to first result. For most engineers, that's the right trade. ([VentureBeat](https://venturebeat.com/orchestration/what-is-deerflow-and-what-should-enterprises-know-about-this-new-local-ai))
---
## Real trade-offs to know before you commit
**Sandbox startup latency.** Cold start adds 8–15 seconds before the first agent action. Container pool management doesn't exist yet in the current release — it's an active community gap.
**Memory persistence is per-session by default.** Cross-session continuity requires a Redis or SQLite-backed memory backend. It's documented but not enabled by default.
**API key sprawl.** At minimum you need an LLM key and a Tavily key; with MCP integrations, you're managing 5–6 keys in a `.env` file. Use a proper secrets manager (Vault, Doppler) from day one for anything beyond a single machine.
These are solvable. They're not reasons to avoid the tool — they're reasons to plan for them.
---
## What to run first
The best first task is one where you already know the expected output. Try this: give it a GitHub repo URL and ask it to summarize the codebase, identify the three most complex functions, and write a unit test for one of them. You'll see the browser tool, the code sandbox, and the sub-agent spawner all activate — and you can evaluate the output against your own knowledge of the repo.
Once you've confirmed function, the research-to-report workflow is where DeerFlow earns its keep. A prompt like "Research the three best open-source alternatives to Datadog for Kubernetes monitoring, compare resource overhead, and write a markdown comparison table" takes 4–6 minutes and produces output that would take an engineer 45–60 minutes manually.
---
## Getting it into your regular workflow
DeerFlow 2.0 is worth the setup if you do research-heavy engineering work — tool evaluations, technical comparisons, codebase documentation, analysis pipelines. The self-hosted version gives you data privacy that cloud agents can't match, and the sandbox model keeps agent failures contained.
If you've already set up the Ollama + Open WebUI stack, DeerFlow sits naturally on top of it: point `config.yaml` at your Ollama endpoint and keep the same models. Same hardware, significantly more capable task orchestration.
Try it this week, while the community is active and the documentation is fresh.
---
## Sources
- [DeerFlow GitHub Repository](https://github.com/bytedance/deer-flow)
- [DeerFlow 2.0: ByteDance's New Open-Source SuperAgent Tool — AIToolly](https://aitoolly.com/ai-news/article/2026-03-25-bytedance-releases-deerflow-20-an-open-source-superagent-for-research-coding-and-creative-tasks)
- [What is DeerFlow 2.0 — VentureBeat](https://venturebeat.com/orchestration/what-is-deerflow-and-what-should-enterprises-know-about-this-new-local-ai)
- [DeerFlow 2.0: ByteDance AI Agent Framework Hits #1 GitHub — byteiota](https://byteiota.com/deerflow-2-0-bytedance-ai-agent-framework-hits-1-github/)
---
## The Infinity Tech XXVIII
Author: The Infinity Team
Date: 2026-03-01
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxviii
## 🚀 **Happy Sunday!**
**Welcome to The Infinity Tech!**
This week, we're welcoming 87 **new members** to our growing tech community. Let's dive into this week's highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
**🛸 This week’s highlights:**
🔹 Human brain cells on a chip learned to play Doom in just one week
🔹 Anthropic vs Pentagon: AI safeguards dispute escalates into supply-chain risk designation
🔹 Paramount set to acquire Warner Bros. Discovery after Netflix backs out of bidding
🔹 SANDWORM_MODE npm worm hijacks CI workflows & poisons AI toolchains
🔹 LLMs used tactical nuclear weapons in 95% of AI war game simulations
## Tech Orbit
---
> 1️⃣ **Human brain cells on a chip learned to play Doom in a week**
> A clump of human brain cells on a neuron-powered computer chip has learned to play the classic game Doom, showcasing significant advancements in biological computing. This development, achieved using Python programming, indicates that biological systems can handle complexity and real-time decision-making, bringing us closer to practical applications such as controlling robotic arms. Although the chip's performance is still below that of human players, it learns faster than traditional silicon-based systems and demonstrates the potential of living neural systems in computing.
> [https://www.newscientist.com/article/2517389-human-brain-cells-on-a-chip-learned-to-play-doom-in-a-week/](https://www.newscientist.com/article/2517389-human-brain-cells-on-a-chip-learned-to-play-doom-in-a-week/)
> 1️⃣ **GPU pricing, a bellwether for AI costs, could help IT leaders at budget time**
> The article examines the rising costs of GPU usage in data centers as AI becomes a standard utility expense for businesses. It highlights the challenges IT leaders face in budgeting for AI due to fluctuating GPU prices and availability, while also exploring efforts to reduce costs through smaller data centers and alternative hardware solutions. Additionally, it addresses the increasing impact of energy consumption on GPU pricing and the sustainability concerns related to expanding AI infrastructure.
> [https://www.computerworld.com/article/4104332/gpu-pricing-a-bellwether-for-ai-costs-could-help-it-leaders-at-budget-time.html](https://www.computerworld.com/article/4104332/gpu-pricing-a-bellwether-for-ai-costs-could-help-it-leaders-at-budget-time.html)
> 1️⃣ **The Industrialization of Exploit Generation, macOS EDR Evasion, Hacking the AWS Console**
> The content delves into the generation of 0-day exploits using advanced tools like Opus 4.5 and GPT-5.2, highlighting vulnerabilities in macOS EDRs and a supply chain vulnerability that allowed for the compromise of the AWS Console. It discusses the implications of these exploits on security practices, particularly in the context of evolving threats and the integration of AI technologies in security measures.
> [https://tldrsec.com/p/tldr-sec-312#39c3](https://tldrsec.com/p/tldr-sec-312#39c3)
> 1️⃣ **Corey Quinn Crashes Out**
> The podcast episode covers new developments from AWS, including the introduction of Amazon Route 53 Global Resolver for secure DNS resolution, AWS Lambda Managed Instances for serverless flexibility, and enhancements to Amazon EC2 with the release of UltraServers. It also highlights AWS Transform for AI-powered code modernization and updates on Amazon S3's capabilities, such as increased maximum object size and new storage classes. The episode provides insights into the latest features and improvements that aim to streamline cloud operations and enhance service efficiency.
> [https://www.lastweekinaws.com/podcast/aws-morni](https://www.lastweekinaws.com/podcast/aws-morni)[ng-brief/corey-quinn-crashes-out](https://www.lastweekinaws.com/podcast/aws-morni%20ng-brief/corey-quinn-crashes-out)
> 1️⃣ **AWS re:Invent 2025: A transformative moment for healthcare and life sciences**
> The AWS re:Invent 2025 event highlighted significant advancements in healthcare and life sciences, showcasing how organizations leverage AWS solutions for drug discovery, clinical workflow improvement, and enhanced patient experiences. Key announcements addressed challenges like data privacy and security, clinical efficiency, and AI development, with innovations such as AWS Clean Rooms for synthetic data generation and new AI capabilities in Amazon Connect aimed at transforming patient engagement.
> [https://aws.amazon.com/blogs/industries/aws-reinvent-2025-a-transformative-moment-for-healthcare-and-life-sciences](https://aws.amazon.com/blogs/industries/aws-reinvent-2025-a-transformative-moment-for-healthcare-and-life-sciences)
> 1️⃣ **Semgrep Secure 2026: Code Security Rebuilt for the AI Era**
> Semgrep Secure 2026 is an upcoming virtual keynote event on February 25, 2026, focusing on the evolution of application security in the age of AI. The keynote will introduce a new multimodal AppSec engine that combines traditional analysis with large language model reasoning to enhance vulnerability detection and reduce false positives, addressing the challenges posed by modern code generation methods.
> [https://semgrep.dev/events/semgrep-secure-2026-virtual-keynote](https://semgrep.dev/events/semgrep-secure-2026-virtual-keynote)
> 1️⃣ **SANDWORM_MODE: Shai-Hulud-Style npm Worm Hijacks CI Workflows and Poisons AI Toolchains**
> An emerging npm supply chain attack, named SANDWORM_MODE, is leveraging typosquatting tactics to infiltrate repositories, steal CI secrets, and compromise AI toolchains through at least 19 malicious npm packages. The attack employs sophisticated methods such as GitHub API exfiltration, DNS tunneling, and the injection of rogue dependencies into CI workflows, posing a significant threat to developers and their environments.
> [https://socket.dev/blog/sandworm-mode-npm-worm-ai-toolchain-poisoning](https://socket.dev/blog/sandworm-mode-npm-worm-ai-toolchain-poisoning)
> 1️⃣ **Raptor Finds Root Cause of Cline’s Supply-Chain Compromise**
> The article details a security incident involving a supply chain compromise at Cline, where an unauthorized npm publication led to credential theft through prompt injection. A tool called Raptor was utilized to quickly identify the malicious user and the compromised commit, highlighting a significant vulnerability and the ongoing investigation into the incident. The initial access was confirmed to have occurred through a specific GitHub issue that exploited the vulnerability before a public disclosure was made.
> [https://www.mbgsec.com/posts/2026-02-18-raptor-finds-cline-compromise](https://www.mbgsec.com/posts/2026-02-18-raptor-finds-cline-compromise)
> 1️⃣ **‘Unbelievably dangerous’: experts sound alarm after ChatGPT Health fails to recognise medical emergencies | Study finds ChatGPT Health did not recommend a hospital visit when medically necessary in more than half of cases**
> A study has found that ChatGPT Health failed to recommend hospital visits in more than half of medical emergencies, raising concerns about potential harm and even death. The AI platform under-triaged cases and struggled to detect suicidal ideation, with experts emphasizing the need for stronger safety standards and independent oversight. This performance highlights significant risks, as users may receive false reassurances during critical health situations.
> [https://www.theguardian.com/technology/2026/feb/26/chatgpt-health-fails-recognise-medical-emergencies](https://www.theguardian.com/technology/2026/feb/26/chatgpt-health-fails-recognise-medical-emergencies)
> 1️⃣ **LLMs used tactical nuclear weapons in 95% of AI war games, launched strategic strikes three times**
> A study by Professor Kenneth Payne revealed that three AI models, GPT-5.2, Claude Sonnet 4, and Gemini 3 Flash, used tactical nuclear weapons in 95% of simulated nuclear crisis games, raising concerns about AI decision-making in military contexts. The models, acting as leaders of nuclear powers during Cold War-like scenarios, frequently opted for tactical nuclear options, indicating a troubling normalization of such strategies. This development highlights the potential risks associated with AI systems influencing real-world military decisions, echoing fears of unintended escalations in nuclear conflicts.
> [https://www.tomshardware.com/tech-industry/artificial-intelligence/llms-used-tactical-nuclear-weapons-in-95-percent-of-ai-war-games-launched-strategic-strikes-three-times-researcher-pitted-gpt-5-2-claude-sonnet-4-and-gemini-3-flash-against-each-other-with-at-least-one-model-using-a-tactical-nuke-in-20-out-of-21-matches](https://www.tomshardware.com/tech-industry/artificial-intelligence/llms-used-tactical-nuclear-weapons-in-95-percent-of-ai-war-games-launched-strategic-strikes-three-times-researcher-pitted-gpt-5-2-claude-sonnet-4-and-gemini-3-flash-against-each-other-with-at-least-one-model-using-a-tactical-nuke-in-20-out-of-21-matches)
### Tech Articles
> 1️⃣ **Renovate**
> Mend Renovate is a platform that automates dependency updates for developers by scanning for newer package versions and generating pull requests directly in the application code. It provides tools for managing open source security, application security, and compliance, while also offering integration with various repository services to streamline the update process and improve overall security. The platform includes different versions tailored for individual developers, communities, and enterprises, each with varying features and support options.
> [https://www.mend.io/renovate](https://www.mend.io/renovate)
> 1️⃣ **Consistent Hashing in a Nutshell**
> Consistent hashing is a technique used to distribute keys uniformly across a cluster of nodes, minimizing the number of keys that need to be relocated when nodes are added or removed. It involves hashing keys and nodes to positions on a circular ring and allows for scalability and load balancing through the use of virtual nodes. This method is commonly applied in distributed systems, caching, and content delivery networks to ensure efficient data management.
> [https://newsletter.systemdesigncodex.com/p/consistent-hashing-in-a-nutshell](https://newsletter.systemdesigncodex.com/p/consistent-hashing-in-a-nutshell)
> 1️⃣ **Scaling long-running autonomous coding**
> The article explores the challenges and strategies of scaling autonomous coding by coordinating multiple agents to collaborate on complex projects. It highlights the importance of role differentiation between planners and workers, and the effectiveness of using separate responsibilities to enhance productivity and manage large codebases. The insights emphasize that while current systems are functional, there is still room for improvement in multi-agent coordination and efficiency.
> [https://cursor.com/blog/scaling-agents](https://cursor.com/blog/scaling-agents)
> 1️⃣ **7 key lessons**
> The content outlines key lessons learned from the architect behind C# and TypeScript, emphasizing the importance of fast feedback loops, the necessity of accommodating diverse coding styles for scalability, and the value of maintaining visibility in open-source development. It also highlights the significance of making incremental improvements rather than drastic changes and discusses the impact of AI on programming workflows, stressing the need for accurate and reliable tools in AI-assisted environments.
> [https://github.blog/developer-skills/programming-languages-and-frameworks/7-learnings-from-anders-hejlsberg-the-architect-behind-c-and-typescript](https://github.blog/developer-skills/programming-languages-and-frameworks/7-learnings-from-anders-hejlsberg-the-architect-behind-c-and-typescript)
> 1️⃣ **work at Amazon**
> The content outlines a 10-step guide for building autonomous AI agents that can manage tasks such as ticket handling and coding without constant human input. It emphasizes the transition from manual prompting to fully automated systems, highlighting the importance of understanding manual processes, creating specialized agents, and defining the role of humans in overseeing these systems to enhance productivity.
> [https://strategizeyourcareer.com/p/the-10-step-guide-to-building-your-own-ai-agent](https://strategizeyourcareer.com/p/the-10-step-guide-to-building-your-own-ai-agent)
> 1️⃣ **supermarket checkout lines**
> The content explores how supermarket checkout lines serve as an analogy for message queues in software systems, highlighting the FIFO (First-In-First-Out) ordering and the importance of managing demand through scaling servers. It discusses the mechanics of queuing, the impact of line length on performance, and introduces concepts like priority queues to improve processing efficiency while also noting their complexities.
> [https://newsletter.systemdesign.one/p/what-is-a-message-queue](https://newsletter.systemdesign.one/p/what-is-a-message-queue)
> 1️⃣ **How I Use Claude Code**
> The content outlines a structured workflow for using Claude Code as a primary development tool, emphasizing the importance of separating research, planning, and implementation phases. The approach involves thorough research followed by a detailed planning process, with an iterative annotation cycle to refine the plan before executing code, ensuring better control and quality in software development.
> [https://boristane.com/blog/how-i-use-claude-code](https://boristane.com/blog/how-i-use-claude-code)
> 1️⃣ **Code is cheap. Show me the talk**
> The article explores the transformative impact of large language model (LLM) coding tools on software development, asserting that traditional coding practices are fundamentally changed. It highlights the ease of generating high-quality code quickly, which diminishes the value of human-written code and emphasizes the growing importance of critical thinking and problem-solving skills over syntax knowledge in the new development landscape.
> [https://nadh.in/blog/code-is-cheap](https://nadh.in/blog/code-is-cheap)
> 1️⃣ **mquire: Linux memory forensics without external dependencies**
> mquire is a new tool for analyzing Linux memory dumps without requiring external debug symbols, addressing a common challenge in memory forensics. By extracting type information and symbol addresses directly from memory dumps, it enables reliable analysis of unknown or custom kernels, facilitating incident response and forensic investigations. The tool features an interactive SQL interface for querying memory data, making it easier to explore and analyze system information.
> [https://blog.trailofbits.com/2026/02/25/mquire-linux-memory-forensics-without-external-dependencies](https://blog.trailofbits.com/2026/02/25/mquire-linux-memory-forensics-without-external-dependencies)
## Asteroid Ventures
---
> 1️⃣ **Anthropic to Pentagon: Autonomous weapons could hurt US troops and civilians**
> Anthropic has refused the US Department of War's demand to remove restrictions on its AI technology, citing concerns that fully autonomous weapons and mass surveillance capabilities could endanger civilians and military personnel. CEO Dario Amodei emphasized that current AI systems lack the reliability required for safe deployment in military applications, and expressed willingness to collaborate on improving these technologies. The situation highlights a conflict between military objectives and ethical considerations regarding AI use in warfare.
> [https://www.theregister.com/2026/02/27/anthropic_pentagon_response/?td=rt-3a](https://www.theregister.com/2026/02/27/anthropic_pentagon_response/?td=rt-3a)
> 1️⃣ **Pentagon moves to designate Anthropic as a supply-chain risk**
> In response to a public dispute with the Department of Defense, President Trump directed federal agencies to cease using all products from Anthropic, designating the company as a supply-chain risk to national security. Secretary of Defense Pete Hegseth supported this directive, emphasizing that no contractor or supplier to the military could engage with Anthropic due to the company's refusal to allow its AI models to be used for mass surveillance or autonomous weapons. The situation has led to OpenAI stepping in to secure a deal with the Pentagon that aligns with the principles Anthropic upheld.
> [https://techcrunch.com/2026/02/27/pentagon-moves-to-designate-anthropic-as-a-supply-chain-risk/](https://techcrunch.com/2026/02/27/pentagon-moves-to-designate-anthropic-as-a-supply-chain-risk/)
> 1️⃣ **Anthropic is somehow both too dangerous to allow and essential to national security**
> Anthropic has faced backlash from the Department of Defense (DOD) after imposing restrictions on its AI model, Claude, which are seen as inappropriate by military leadership. The DOD is now considering invoking the Defense Production Act to compel Anthropic to comply with military demands, raising concerns about the implications for AI regulation and the relationship between tech companies and the government. This situation highlights the tension between national security needs and ethical considerations surrounding AI development.
> [https://www.theargumentmag.com/p/anthropic-is-somehow-both-too-dangerous](https://www.theargumentmag.com/p/anthropic-is-somehow-both-too-dangerous)
> 1️⃣ **CNN’s Jake Tapper Breaks News of Paramount Buying Network’s Parent Company WBD Live on Air: "It Affects Everybody I’m Looking at Right Now in the Studio"**
> CNN's Jake Tapper announced live on air that Paramount Skydance is poised to acquire Warner Bros. Discovery, CNN's parent company, following Netflix's decision not to match Paramount's $111 billion bid. This development is significant as it could lead to substantial changes at CNN, with Paramount's CEO hinting at sweeping reforms if the acquisition goes through. The news raises concerns about regulatory challenges that may impact the deal's approval.
> [https://variety.com/2026/film/news/cnn-jake-tapper-paramount-buying-wbd-live-on-air-1236674342/](https://variety.com/2026/film/news/cnn-jake-tapper-paramount-buying-wbd-live-on-air-1236674342/)
> 1️⃣ **OpenAI is negotiating with the U.S. government, Sam Altman tells staff**
> OpenAI is negotiating a deal with the U.S. Department of War to use its AI models, following a conflict involving Anthropic, which lost its contracts with the Pentagon. The agreement allows OpenAI to establish its own safety measures and includes provisions against using AI for autonomous weapons and domestic surveillance. This development is significant as it positions OpenAI favorably in the military AI landscape while addressing safety concerns.
> [https://fortune.com/2026/02/27/openai-in-talks-with-pentagon-after-anthropic-blowup/](https://fortune.com/2026/02/27/openai-in-talks-with-pentagon-after-anthropic-blowup/)
> 1️⃣ **He saw an abandoned trailer. Then, he uncovered a surveillance network on California’s border**
> Southern California residents have encountered new license plate readers operated by the Border Patrol, which have raised privacy concerns among locals and advocates. These devices, installed on state highways, log every driver's license plate and feed data into federal databases, prompting fears of unwarranted surveillance and potential targeting of humanitarian volunteers. The technology is controversial as it may conflict with California state laws designed to protect residents from such data collection practices.
> [https://calmatters.org/justice/2026/02/alpr-border-patrol-caltrans/](https://calmatters.org/justice/2026/02/alpr-border-patrol-caltrans/)
> 1️⃣ **Anthropic rejects Pentagon's requests in AI safeguards dispute, CEO says**
> Anthropic has rejected the Pentagon's request to remove safeguards from its AI systems, which would prevent the technology from being used for autonomous weapons and domestic surveillance, despite threats from the Pentagon to terminate a $200 million contract. The company's CEO, Dario Amodei, emphasized that AI systems are not reliable enough for life-or-death scenarios, and he hopes the Pentagon will reconsider its decision. Tensions escalated further when a Pentagon undersecretary accused Amodei of having a "God-complex" and prioritizing control over military safety.
> [https://finance.yahoo.com/news/anthropic-rejects-pentagons-requests-ai-225245131.html](https://finance.yahoo.com/news/anthropic-rejects-pentagons-requests-ai-225245131.html)
> 1️⃣ **Netflix Backs Out of Warner Bros. Bidding, Paramount Set to Win**
> Netflix has opted out of bidding for Warner Bros., declaring that the deal was no longer financially attractive, thereby paving the way for Paramount to secure the acquisition with a bid of $31 per share and additional incentives. This decision is significant as it marks a shift in the competitive landscape of streaming services, with Paramount poised to integrate Warner Bros. and potentially reshape the entertainment industry. Despite the exit, Netflix plans to continue investing approximately $20 billion in content for the year to bolster its streaming offerings.
> [https://www.hollywoodreporter.com/business/business-news/netflix-backs-out-warners-deal-paramount-win-1236516763/](https://www.hollywoodreporter.com/business/business-news/netflix-backs-out-warners-deal-paramount-win-1236516763/)
> 1️⃣ **Amazon Wishlist change doxxes users and shares your delivery address**
> Amazon is changing its Wishlist feature to allow third-party sellers to access users' shipping addresses when items are purchased from shared lists, effective March 25, 2026. This raises privacy concerns, particularly for content creators who share their Wishlists publicly, as Amazon will not protect users' address information and instead recommends using a PO Box. Many users are outraged, prompting some to seek alternative platforms that prioritize privacy.
> [https://www.dexerto.com/entertainment/amazon-wishlist-change-doxxes-users-and-shares-your-delivery-address-3324823/](https://www.dexerto.com/entertainment/amazon-wishlist-change-doxxes-users-and-shares-your-delivery-address-3324823/)
> 1️⃣ **Anthropic ditches its core safety promise in the middle of an AI red line fight with the Pentagon**
> Anthropic has modified its core safety policy by adopting a nonbinding safety framework, citing that its previous guidelines could hinder competitiveness in the AI market. This change comes amid pressure from the Pentagon, which threatened to revoke a significant contract unless the company rolled back its AI safeguards. The new policy emphasizes flexibility and aims to publicly report on safety progress while distancing Anthropic's internal safety plans from broader industry recommendations.
> [https://www.cnn.com/2026/02/25/tech/anthropic-safety-policy-change](https://www.cnn.com/2026/02/25/tech/anthropic-safety-policy-change)
## Black Hole
---
> 0️⃣ **RAG vs SKILL vs MCP vs RLM**
> Large Language Models (LLMs) are limited in specialized tasks, which is addressed by techniques like RAG, SKILL, MCP, and RLM. RAG enhances LLMs with relevant external knowledge through a retrieval mechanism, while SKILL allows LLMs to dynamically load necessary capabilities. MCP standardizes LLM interactions with external systems, and RLM enables processing of vast datasets by treating long prompts as external variables, improving context comprehension but introducing complexity and latency challenges.
> [https://blog.alexewerlof.com/p/rag-vs-skill-vs-mcp-vs-rlm](https://blog.alexewerlof.com/p/rag-vs-skill-vs-mcp-vs-rlm)
> 0️⃣ **Timsort Algorithm - A Deep Dive**
> Timsort is a hybrid sorting algorithm that combines merge sort and insertion sort, optimized for real-world data with existing order. It operates by dividing data into small chunks, sorting each chunk, and then merging them, while employing techniques such as galloping mode and adaptive merging to improve efficiency. This algorithm is widely recognized for its speed and practicality, making it a default choice in several programming languages.
> [https://newsletter.systemdesign.one/p/timsort-algorithm](https://newsletter.systemdesign.one/p/timsort-algorithm)
> 0️⃣ **Software Design Principles That Matter**
> Software Design Principles That Matter explains the core idea in plain terms and how it applies in practice. It focuses on: public, string, class, private, have, cardnumber. Read it if you want a clear mental model and concrete trade-offs so you can make a better decision (or avoid common mistakes) quickly. You will leave with a concise set of takeaways you can apply immediately in your own projects or infrastructure.
> [https://newsletter.francofernando.com/p/software-design-principles-that-matter](https://newsletter.francofernando.com/p/software-design-principles-that-matter)
> 0️⃣ **From Stateful to Stateless: Building Web Apps That Scale**
> From Stateful to Stateless: Building Web Apps That Scale explains the core idea in plain terms and how it applies in practice. It focuses on: data, servers, request, server, when, any. Read it if you want a clear mental model and concrete trade-offs so you can make a better decision (or avoid common mistakes) quickly. You will leave with a concise set of takeaways you can apply immediately in your own projects or infrastructure.
> [https://newsletter.francofernando.com/p/from-stateful-to-stateless-building](https://newsletter.francofernando.com/p/from-stateful-to-stateless-building)
## Double Star
---
### Open Source Repositories
> 📦 **claude-chill**
> This content introduces a tool called claude-chill, which acts as a PTY proxy to improve the user experience when interacting with Claude Code by handling large terminal updates more efficiently. It intercepts atomic updates, uses VT-based rendering to show only changes, and allows users to look back at previous outputs without lag or flicker. The tool also includes customizable settings for history storage and lookback functionality.
> [https://github.com/davidbeesley/claude-chill](https://github.com/davidbeesley/claude-chill)
> 📦 **awesome-deception**
> This repository is a comprehensive collection of resources related to deception in cybersecurity, including articles, research papers, guides, and tools. It aims to provide insights into techniques and frameworks that employ deception to enhance security measures, highlighting various applications and community contributions in the field.
> [https://github.com/tracebit-com/awesome-deception](https://github.com/tracebit-com/awesome-deception)
> 📦 **CredData**
> CredData is a dataset comprised of files containing credentials found in open source projects. It includes suspicious lines with manual review results and categorizes credential types, which can be used to develop or enhance tools aimed at minimizing credential leaks. The dataset also provides detailed statistics and guidelines for selecting target repositories and labeling suspected credential information.
> [https://github.com/Samsung/CredData](https://github.com/Samsung/CredData)
> 📦 **CredSweeper**
> CredSweeper is a credential detection tool that identifies exposed sensitive information, such as passwords and API keys, across various file types and source code. It utilizes pattern-based detection, machine learning validation, and deep file inspection to provide comprehensive security scanning and reduce false positives. The tool supports scanning of compressed files and Git repository analysis, making it suitable for modern codebases.
> [https://github.com/Samsung/CredSweeper](https://github.com/Samsung/CredSweeper)
> 📦 **symplex**
> Symplex is an open-source protocol designed to facilitate semantic negotiation between distributed AI agents, enabling communication based on meaning rather than rigid schemas. It utilizes intent vectors for agents to express goals, allowing for dynamic negotiation and collaboration without the need for pre-registered APIs, and incorporates a lightweight extension of the Model Context Protocol (MCP) to enhance interoperability.
> [https://github.com/olserra/symplex](https://github.com/olserra/symplex)
> 📦 **azureBlob**
> This repository provides a C2 profile for Azure Blob Storage designed for secure command and control communication with individual agent container isolation. It employs container-scoped SAS tokens to limit access and ensure agents cannot access each other's data, enhancing security while leveraging common egress exceptions for Azure services.
> [https://github.com/senderend/azureBlob](https://github.com/senderend/azureBlob)
> 📦 **agent-skills**
> The content provides a collection of skills for AI coding agents designed to enhance their capabilities in software development. It includes best practices for React, web design guidelines, and React Native optimization, along with instructions for deployment on Vercel. Each skill is structured to assist developers in improving code quality, performance, and user experience.
> [https://github.com/vercel-labs/agent-skills](https://github.com/vercel-labs/agent-skills)
> 📦 **Awesome-FDE-Roadmap**
> This document provides a comprehensive roadmap for becoming a Forward Deployment Engineer (FDE), highlighting the skills and knowledge necessary to bridge the gap between software development and real-world client deployment. It outlines key phases in the learning process, including data engineering, cloud architecture, and the consulting mindset, while emphasizing the importance of integrating AI and strategic consulting into technical solutions. The content also includes resources, frameworks, and practical templates to assist engineers in navigating complex project environments and improving client relations.
> [https://github.com/pierpaolo28/Awesome-FDE-Roadmap](https://github.com/pierpaolo28/Awesome-FDE-Roadmap)
## Celestial Quotes
---
> "There are two hard things in computer science: cache invalidation, naming things, and off-by-one errors." — *Leon Bambrick*
## Stellar Prompts
---
## AI Prompting Tips from a Power User
> **How to Get Way Better Responses from AI**
> A comprehensive guide on prompt engineering techniques that dramatically improve AI output quality. Learn how to structure prompts using frameworks, refine responses iteratively, and avoid common pitfalls that lead to generic or inconsistent results. These battle-tested strategies come from extensive real-world usage across creative projects, essays, and complex applications like CYOA games.
> [https://www.reddit.com/r/PromptEngineering/comments/1j5ymik/ai_prompting_tips_from_a_power_user_how_to_get/](https://www.reddit.com/r/PromptEngineering/comments/1j5ymik/ai_prompting_tips_from_a_power_user_how_to_get/)
### Key Techniques
- **Use Structured Frameworks:** Instead of asking AI to "write X," provide a clear framework with sections like Title, Thesis, Arguments, Counterarguments, and Conclusion. This reduces rambling and hallucination.
- **The "Lazy Essay" Method:** Break prompts into four parts: Assignment, Quotes, Notes, and Additional Instructions. This gives AI concrete context to build from.
- **Iterate, Don't Settle:** Never accept the first response. Refine 2-3 times by expanding specific sections or adding depth to weak areas.
- **Force AI to Take a Stance:** AI defaults to neutral, boring responses. Make it defend a position or argue from specific perspectives (e.g., "Defend UBI from a socialist perspective, then argue against it from a libertarian view").
- **Use JSON for Character/Object Definition:** Structured formats like JSON reduce ambiguity and hallucination, especially for creative projects with complex state management.
- **Tweak One Variable at a Time:** If output is bad, don't start over—adjust one constraint (add specificity, simplify language, or request more depth) and iterate.
### Framework Examples
> **Essay Framework:**
> Title: [Insert Here]
> Thesis: [Main Argument]
> Arguments:
> - [Key Point #1]
>
> - [Key Point #2]
>
> - [Key Point #3]
> Counterarguments:
>
> - [Opposing View #1]
>
> - [Opposing View #2]
> Conclusion: [Wrap-up Thought]
> **Character Definition (JSON):**
> {
> "name": "John Doe",
> "archetype": "Tragic Hero",
> "motivation": "Wants to prove himself to a world that has abandoned him.",
> "conflicts": {
> "internal": "Fear of failure",
> "external": "A rival who embodies everything he despises."
> },
> "moral_alignment": "Chaotic Good"
> }
### Pro Tips from the Community
- **Meta-Framework Generation:** Ask AI to suggest 5 frameworks for your task, pick the best one, then have AI use that framework to ask you clarifying questions before generating output.
- **Expert Role Assignment:** Start by asking "Who is the best expert for task X?" Then prompt: "You are now Expert A with expertise [context]. Help me accomplish X."
- **Framework-First Approach:** Have AI reference or create a framework first (like "John Truby's Anatomy of Story for fiction"), then use that framework to generate actual content.
- **DeepSeek for Structure, Claude/GPT for Content:** Use DeepSeek to create structured frameworks, edit them manually, then use ChatGPT or Claude to generate the actual content.
---
## Build a Daily Tech Command Center with Glance
Author: Serdarcan Buyukdereli
Date: 2026-01-02
Category: Open Source
URL: https://theinfinity.dev/articles/glance-daily-tech-command-center-docker-nginx
**Docker Compose + Glance YAML + Nginx + glance.theinfinity.dev**
Most mornings, the internet isn’t an “ocean of knowledge.” It’s a **soup of notifications**. Glance takes that soup, pours it into a single bowl, and helps you keep the signal without drowning in the noise.
In this article, we’ll:
- Run Glance with Docker Compose
- Design a single “Tech” dashboard (GitHub Trends + Releases + Reddit + HN + Lobsters + Monitor)
- Publish it behind Nginx on glance.theinfinity.dev
- Bonus: how to leverage Glance’s **community-widgets** ecosystem like plug-ins
---
## **TL;DR**
- Docker Compose setup in minutes ✅
- A curated dashboard via glance.yml ✅
- GitHub trends + release radar ✅
- Reddit + HN + Lobsters for real-world pulse ✅
- Nginx reverse proxy + SSL + (optional) basic auth ✅
- Community widgets + $include to keep configs clean ✅
---
## **1) Setup: Docker Compose**
Folder layout:
```
~/glance/
docker-compose.yml
config/
glance.yml
```
docker-compose.yml:
```yaml
services:
glance:
container_name: glance
image: glanceapp/glance
restart: unless-stopped
volumes:
- ./config:/app/config
ports:
- 8081:8080
```
Start it:
```bash
cd ~/glance
docker compose up -d
docker logs -f glance
```
At this point, Glance should be reachable internally at http://SERVER_IP:8081. We’ll put it behind Nginx next.
---
## **2) Dashboard philosophy: what this page is actually for**
This dashboard is not built to “show everything.”
It’s built to answer a few questions fast:
- **GitHub:** what’s trending today, and what just shipped (releases)?
- **Discussions:** what are people arguing about (and learning from) on Reddit / HN / Lobsters?
- **Ops:** is TheInfinity.dev alive and responding?
> My Commentary: Done right, Glance becomes a daily briefing, not another time-sink.
---
## **3) Full config/glance.yml**
Save the file below as config/glance.yml.
```yaml
theme:
background-color: 50 1 6
primary-color: 24 97 58
negative-color: 209 88 54
pages:
- name: "Tech"
columns:
- size: small
widgets:
- type: group
style: clean
widgets:
- type: custom-api
title: "🔥 Github Trends"
cache: 24h
url: 'https://api.ossinsight.io/v1/trends/repos/?period=past_24_hours&language=All'
template: |
- type: rss
title: "🔥 Product Hunt"
style: clean
feeds:
- url: https://www.producthunt.com/feed
collapse-after: 15
- type: monitor
cache: 1m
title: Services
sites:
- title: Website
url: https://theinfinity.dev
icon: https://www.theinfinity.dev/logo.svg
- size: full
widgets:
- type: rss
title: "🧠 Tech & Dev Feeds"
style: detailed-list
cache: 12h
feeds:
- url: https://www.lastweekinaws.com/newsletter/feed/
title: Last Week in AWS
- url: https://newsletter.systemdesign.one/feed
title: System Design Newsletter
- url: https://blog.bytebytego.com/feed
title: ByteByteGo
- url: https://newsletter.memesmotivations.com/feed
title: The M&Ms Newsletter
- url: https://nuvemmag.substack.com/feed
title: Nuvem Mag
- url: https://newsletter.francofernando.com/feed
title: Franco Fernando
- url: https://rss.beehiiv.com/feeds/xgTKUmMmUm.xml
title: TLDRSec
- url: https://rss.beehiiv.com/feeds/ypr2bi0H9m.xml
title: Hungry Minds
- url: https://blog.alexewerlof.com/feed
title: Alex Ewerlöf
- url: https://hellointerview.substack.com/feed
title: Hello Interview
- url: https://seattledataguy.substack.com/feed
title: Seattle Data Guy
- url: https://newsletter.systemdesigncodex.com/feed
title: System Design Codex
- url: https://blog.algomaster.io/feed
title: Algomaster
- url: https://dribbble.com/shots/popular.rss
title: Dribbble Inspiration
- type: group
title: "💬 Reddit Discussions"
style: cards
widgets:
- type: reddit
subreddit: technology
show-thumbnails: true
- type: reddit
subreddit: selfhosted
show-thumbnails: true
- type: reddit
subreddit: devops
show-thumbnails: true
- type: reddit
subreddit: kubernetes
show-thumbnails: true
- type: reddit
subreddit: n8n
show-thumbnails: true
- type: reddit
subreddit: automation
show-thumbnails: true
- type: reddit
subreddit: notebooklm
show-thumbnails: true
- type: reddit
subreddit: aicuriosity
show-thumbnails: true
- type: reddit
subreddit: GeminiNanoBanana
show-thumbnails: true
- type: reddit
subreddit: AgentsOfAI
show-thumbnails: true
- type: reddit
subreddit: OpenAI
show-thumbnails: true
- type: reddit
subreddit: ChatgptArtist
show-thumbnails: true
- type: reddit
subreddit: artificial
show-thumbnails: true
- type: reddit
subreddit: PromptEngineering
show-thumbnails: true
- type: reddit
subreddit: WritingPrompts
show-thumbnails: true
- size: small
widgets:
- type: group
style: clean
widgets:
- type: hacker-news
title: "🔥 Hacker News"
style: clean
collapse-after: 10
- type: lobsters
title: "🦞 Lobsters"
style: clean
collapse-after: 10
```
Restart after changes:
```bash
docker compose restart
```
---
## **4) Community Widgets: from copy-paste to “include” level**
Glance has a **community-widgets** repository: a shared pool of community-made widgets.
Small widgets: you can paste them directly into glance.yml.
Large widgets: split them into separate files to avoid YAML indentation pain, then include them.
Example structure:
- config/widgets/immich-stats.yml
```
## community widget content (could be long)
```
Then in your main glance.yml:
```yaml
widgets:
- $include: widgets/immich-stats.yml
```
This keeps the main config readable and makes experimentation stupidly easy.
---
## **5) “Glance loads a bit slowly” (and why that can be normal)**
Glance may cache and fetch data for multiple widgets on startup. If you keep stacking heavy sources, you may notice a few seconds of initial load time.
Practical fixes:
- Split into pages (Tech / AI)
- Keep cache durations sane (e.g., GitHub releases at 12h is perfect)
---
## **6) Publishing:** [**glance.theinfinity.dev**](http://glance.theinfinity.dev/) **behind Nginx**
### **6.1 DNS**
Create an A record:
- glance.theinfinity.dev → your VPS IP
### **6.2 Nginx reverse proxy**
Create:
/etc/nginx/sites-available/glance.theinfinity.dev
```
server {
listen 80;
server_name glance.theinfinity.dev;
location / {
proxy_pass http://127.0.0.1:8081;
proxy_set_header Host $host;
proxy_set_header X-Real-IP $remote_addr;
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
proxy_set_header X-Forwarded-Proto $scheme;
proxy_http_version 1.1;
proxy_read_timeout 60s;
}
}
```
Enable + reload:
```bash
sudo ln -s /etc/nginx/sites-available/glance.theinfinity.dev /etc/nginx/sites-enabled/
sudo nginx -t
sudo systemctl reload nginx
```
### **6.3 SSL (Let’s Encrypt)**
```bash
sudo apt update
sudo apt install -y certbot python3-certbot-nginx
sudo certbot --nginx -d glance.theinfinity.dev
```
---
## **7) If you expose it publicly: the simplest shield (Nginx Basic Auth)**
This panel is your personal command center. It doesn’t have to be a public monument.
```bash
sudo apt install -y apache2-utils
sudo htpasswd -c /etc/nginx/.htpasswd glanceadmin
```
Update your Nginx config:
```
location / {
auth_basic "Restricted";
auth_basic_user_file /etc/nginx/.htpasswd;
proxy_pass http://127.0.0.1:8081;
proxy_set_header Host $host;
proxy_set_header X-Real-IP $remote_addr;
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
proxy_set_header X-Forwarded-Proto $scheme;
}
```
---
## **Final thoughts**
The power here isn’t “I installed Glance.”
The power is the combo:
- GitHub Trends for daily open-source signals
- Releases Radar to catch changes before they surprise production
- Reddit + HN + Lobsters to track real discussion and pain points
- Community widgets to grow your dashboard like Lego blocks
- Subdomain + Nginx for clean publishing
- server.proxied: true so it behaves correctly behind a reverse proxy
glance.theinfinity.dev fits perfectly into the TheInfinity.dev ecosystem as a behind-the-scenes operations panel for discovery and content flow.
---
## The Infinity Tech XXVII
Author: The Infinity Team
Date: 2025-12-01
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxvii
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming 2**2 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹 Cloudflare's 5-hour outage impacts major internet services
🔹 Microsoft tests hydrogen fuel cells for 48-hour data center backup power
🔹 Windows Blue Screen of Death gets a modern black makeover after 40 years
🔹 6G technology standardization advances with 2028 testing target
🔹 Autonomous vehicle testing regulations announced in Turkey
## Tech Orbit

---
### **Tech News**
**🔹** [**Amazon**](https://www.reuters.com/business/retail-consumer/amazon-invest-up-50-billion-ai-supercomputing-us-government-customers-2025-11-24/) **announces $50B investment in AI and supercomputing infrastructure for US government services**
**🔹** [**Microsoft**](https://apnews.com/article/technology-business-artificial-intelligence-cloud-computing-a3e4d6ba75f475eb130d91c81e522f93) **forms strategic cloud infrastructure alliance with Anthropic and Nvidia to accelerate AI development**
**🔹** [**Google**](https://www.itpro.com/software/development/google-ceo-sundar-pichai-says-vibe-coding-has-made-software-development-exciting-again-developers-might-disagree) **CEO Sundar Pichai champions "vibe coding" as AI tools revitalize the software development experience**
**🔹** [**CloudBees**](https://www.infoworld.com/article/3992486/cloudbees-unveils-ai-enhanced-devops-platform.html) **launches Unify platform integrating AI-powered control planes into existing developer toolchains**
**🔹** [**CoreWeave**](https://en.wikipedia.org/wiki/CoreWeave) **becomes the first cloud provider to commercially deploy Nvidia's GB200 NVL72 chips for high-performance computing**
### **Tech Articles**
**🔹** [**AI-First DevOps**](https://devcontentops.io/post/2025/08/ai-first-devops) **analysis on how artificial intelligence is becoming the foundational operational standard for modern software delivery**
**🔹** [**LADs Framework**](https://arxiv.org/abs/2502.20825) **explores leveraging Large Language Models to drive autonomous DevOps and cloud optimization**
**🔹** [**AIOpsLab**](https://arxiv.org/abs/2501.06706) **presents a comprehensive framework for evaluating and benchmarking AI agents in autonomous cloud environments**
**🔹** [**Automated IaC**](https://arxiv.org/abs/2510.20211) **study details new methods for reconciling cloud infrastructure-as-code using intelligent AI agents**
**🔹** [**Reusable MLOps**](https://arxiv.org/abs/2403.00787) **guide discusses operationalizing AI/ML models with modular and scalable infrastructure patterns**
## Asteroid Ventures

---
### **Companies News**
🔹 [**Blacksmith**](https://www.blacksmith.sh/blog/tomorrow) **Secures $10M Series A**
🔹 [**LendOS**](https://www.lendos.io/services-7) **Announces Series A Funding Led by Blackstone Innovations Investments**
🔹 [**Aleph**](https://www.getaleph.com/blog/series-b?hsCtaAttrib=196141229349) **raises a $29M Series B to accelerate AI adoption in FP&A**
🔹 [**Envive AI**](https://www.envive.ai/post/envive-ai-raises-15m-series-a-to-power-self-improving-agents-for-the-agentic-commerce-era) **Raises $15M Series A to Power Self-Improving Agents for the Agentic Commerce Era**
## Black Hole

[https://newsletter.systemdesign.one/p/system-design-interview-twitter](https://newsletter.systemdesign.one/p/system-design-interview-twitter)
[https://research.google/blog/learn-your-way-reimagining-textbooks-with-generative-ai/](https://research.google/blog/learn-your-way-reimagining-textbooks-with-generative-ai/)
[https://chillphysicsenjoyer.substack.com/p/youre-a-slow-thinker-now-what](https://chillphysicsenjoyer.substack.com/p/youre-a-slow-thinker-now-what)
[https://blog.cloudflare.com/ai-week-2025-wrapup/](https://blog.cloudflare.com/ai-week-2025-wrapup/)
[https://www.theinfinity.dev/articles/kubernetes-ingress-gateway-comparison-traefik-istio-kong](https://www.theinfinity.dev/articles/kubernetes-ingress-gateway-comparison-traefik-istio-kong)
## Cosmic Currents
[▶ Video](https://www.youtube.com/watch?v=mfv0V1SxbNA)
## Double Star

---
### Open Source Repositories
> 📦 **Valdi**
> An open-source cross-platform UI framework developed by Snapchat. It lets you write TypeScript components and render them natively on iOS, Android, and macOS.
> [https://github.com/Snapchat/Valdi](https://github.com/Snapchat/Valdi?ref=dailydev)[](https://github.com/unslothai/unsloth)*ui-framework, mobiledevelopment, typescript*
> 📦 **Strix**
> A minimal yet powerful framework for modern web applications. Perfect for startups or developers who need rapid prototyping. “Let your code dance and leave a mark on the web.
> [https://github.com/usestrix/strix](https://github.com/usestrix/strix)[](https://github.com/unslothai/unsloth)*startup-tools, lightweight, webframework*
> 📦 **Umami**
> A privacy-focused, open-source web analytics platform and a clean alternative to Google Analytics. Ideal for blogs, company sites, or SaaS dashboards. “Keep your user data in your hands, not in the shadows.”
> [h](https://github.com/bytebot-ai/bytebot)[ttps://github.com/umami-software/umami](https://github.com/umami-software/umami?ref=dailydev)[](https://github.com/unslothai/unsloth)*web-analytics, privacy, open-source*
> 📦 **NoFx**
> A minimalist framework for iOS app development. Swift developers can build clean and efficient apps with less code.
> [https://github.com/NoFxAiOS/nofx](https://github.com/NoFxAiOS/nofx?ref=dailydev)[](https://github.com/unslothai/unsloth)*ios-development, swift, mobileframework*
> 📦 **ImHex**
> A powerful hex editor for analyzing and editing binary files. Loved by reverse engineers and firmware developers.
> [https://github.com/WerWolv/ImHex](https://github.com/WerWolv/ImHex?ref=dailydev)[](https://github.com/unslothai/unsloth)*reverse-engineering, hexeditor, firmware*
> 📦 **repomix**
> Combines multiple repositories into a single readable text file. Perfect for code reviews, AI prompts, or quick documentation sharing.
> [https://github.com/yamadashy/repomix](https://github.com/yamadashy/repomix?ref=dailydev)[](https://github.com/unslothai/unsloth)*developer-tools, documentation, code-review*
> 📦 **lazyhelm**
> A lightweight CLI tool for managing Helm charts effortlessly. Saves time and energy for Kubernetes administrators.
> [https://github.com/alessandropitocchi/lazyhelm](https://github.com/alessandropitocchi/lazyhelm?ref=dailydev)[](https://github.com/unslothai/unsloth)*helm, kubernetes, cli*
> 📦 **Glance**
> A personal dashboard that aggregates data from APIs, RSS, and widgets into one screen. Perfect for developers, makers, and data lovers.
> [https://github.com/glanceapp/glance](https://github.com/glanceapp/glance)[](https://github.com/unslothai/unsloth)*dashboard, datavisualization, productivity*
## Galactic Meme
---
## Celstial Quotes

---
> **“AI has the potential to be more transformative than electricity or fire.” – Sundar Pichai, CEO of Google**
## Stellar Prompts

---
**The Art of Prompting: How to Write the Right Prompt for AI-Generated Blog Posts**
When using AI to generate a blog post, it’s crucial to craft a prompt that is clear, specific, and well-structured. Defining the topic, target audience, tone, and format in advance significantly improves the final result. For example, when requesting a blog comparing Kubernetes Ingress / Gateway solutions, the prompt should explicitly list which tools to analyze, which sections to include, and specify that the content should contain YAML examples, performance insights, security and traffic-management discussions, and be written in English with a technical but lightly humorous tone. A well-designed prompt removes guesswork for the AI and leads to content that is more consistent, professional, and ready to publish. In short: **“Say exactly what you want, describe how you want it, and enjoy the final result.”**
```yaml
You are an experienced DevOps/SRE engineer who also writes about technical topics in a fun but professional way.
Your task:
Write a detailed comparison blog post about Kubernetes Ingress / Gateway solutions, going tool-by-tool. The post should be educational, accurate, and mildly humorous without being annoying.
Tools to compare:
- Traefik
- HAProxy Ingress Controller
- Kong Ingress Controller
- Contour
- Pomerium Ingress Controller
- kgateway
- Istio Ingress Gateway
- Cilium Ingress Controller
General guidelines:
- The entire article must be in English.
- Target audience: intermediate to advanced DevOps / Platform Engineers / SREs.
- Tone: knowledgeable, clear, slightly sarcastic but respectful; high technical accuracy; explain jargon briefly when first introduced.
- Keep paragraphs reasonably short; don’t overwhelm the reader.
- Use light humour occasionally (e.g. “SREs might experience a slight drop in blood pressure when they see this”), but don’t overdo it.
- The post should read like a standalone, “reference-style” guide.
Title:
- Produce a professional but slightly humorous blog title.
- Example of the tone: “Life After NGINX: Traefik, Istio or Kong?” (do NOT reuse this exact title; generate a new one in a similar spirit).
Structure:
Use the following categories as H2 headings. Under each category, create H3 subheadings for each tool and analyse them one by one.
1. Controller Architecture
- For each tool:
- How is the architecture structured?
- Controller design
- Use of CRDs
- Sidecars or not
- Clear separation of data plane / control plane?
- Provide a brief summary with strengths and weaknesses.
2. Configuration / Annotation Compatibility
- For each tool:
- Support level for Ingress / HTTPRoute / Gateway API
- How easy or hard is migration from the NGINX annotation-heavy world?
- Config file / CRD complexity
- Whenever possible, add a small YAML snippet for each tool:
- e.g. a simple HTTPRoute / Ingress / Gateway definition.
- Use Markdown code blocks; keep snippets short but meaningful.
3. Protocol & Traffic Support
- Cover HTTP/1.1, HTTP/2, gRPC, WebSocket, TCP/UDP, mTLS, HTTP/3, etc.
- Explain which tool supports what natively and where extra configuration is required.
4. Traffic Management & Advanced Routing
- Canary, blue-green, A/B testing
- Header-based routing, path-based routing, weight-based routing
- Emphasize the differences of advanced players like Istio, Kong and Traefik.
- Include at least one canary deployment YAML example (ideally using Istio, Traefik, Kong or Cilium).
5. Security Features
- mTLS, JWT validation, OAuth/OIDC integrations
- WAF integration, rate limiting, IP allow/deny lists
- Specifically highlight identity/authentication strengths for tools like Pomerium and Kong.
- Include a simple mTLS or JWT validation YAML example in this section.
6. Observability / Monitoring
- Prometheus metrics, Grafana dashboard compatibility
- Access logs, tracing integrations (Jaeger, Tempo, etc.)
- Comment on which tools are “transparent enough” to win SRE hearts.
7. Performance & Resource Usage
- Proxy type (L4/L7, Envoy-based, eBPF-based, etc.)
- Provide a general comparison: in which scenarios is each tool lighter/heavier?
- If there are publicly known benchmarks, summarize them at a high level (no need for exact numbers or explicit sources, just general tendencies).
8. Installation & Community Support
- Helm charts, Operators, Gateway API compatibility
- Documentation quality
- Community activity, GitHub health, enterprise support (especially for Kong, Istio, Cilium, Traefik).
9. Ecosystem & Compatibility
- Briefly mention cloud vendor integrations (AKS, EKS, GKE, Huawei CCE, etc.).
- Compatibility with other CNCF projects (e.g. Istio + Cilium, kgateway + Gateway API, etc.).
- Plugin / extension support.
10. Future-Proofing / Roadmap
- Gateway API support and its importance in the ecosystem.
- The role of these tools in the post–NGINX Ingress EOL world.
- Which tools look like safer bets for the next 3–5 years? Give reasoned, thoughtful speculation.
Comparison Table:
- At the end of the article, include a comparison table rating each tool from 1 to 5 on the following criteria:
- Controller Architecture
- Configuration Simplicity
- Protocol & Traffic Support
- Traffic Management / Advanced Routing
- Security Features
- Observability
- Performance & Resource Usage
- Installation Simplicity
- Ecosystem & Community
- Future-Proofing
- Rows = tools, columns = criteria.
- Explain the scale:
- 1 = “Please don’t try this in prod”
- 3 = “It works, but you’ll sweat a bit”
- 5 = “Ship it to prod and don’t look back”
- The scoring is subjective but must be reasonable; add short notes where helpful (e.g. “Istio is powerful but complex”, “Traefik is easy to learn and flexible”).
```
---
## Traffic Management in Kubernetes: From Traefik to Istio, Life After NGINX
Author: Serdarcan Büyükdereli
Date: 2025-11-20
Category: DevOps Blog
URL: https://theinfinity.dev/articles/kubernetes-ingress-gateway-comparison-traefik-istio-kong
Now that NGINX Ingress is basically saying “I’m slowly heading to retirement,” everyone has the same question in their head:
**“So… who do we trust with all this traffic now?”**
In this post, we’re putting eight major players in the Kubernetes traffic game on the table:
- **Traefik**
- **HAProxy Ingress Controller**
- **Kong Ingress Controller**
- **Contour**
- **Pomerium Ingress Controller**
- **kgateway**
- **Istio Ingress Gateway**
- **Cilium Ingress Controller**
Target audience: DevOps / SRE / Platform Engineers who do **not** lose their heart rhythm when they see kubectl get events.
Style: Technical, precise, mildly sarcastic, still respectful.
We’ll follow this structure:
- Short explanation per category
- Under each category, tool-by-tool mini breakdown
- Short YAML snippets here and there
- One big 1–5 scoring comparison table at the end
If you’re ready, let’s kubectl port-forward this into your brain.
---
## **1. Controller Architecture**
Here we answer “how does this thing actually work?”
Envoy or not, single binary or not, control-plane / data-plane split, sidecars, CRDs…
### **Traefik**
- **Architecture:** Single binary that acts as both control-plane and data-plane. In Kubernetes it usually runs as a Deployment + Service.
- **APIs:** Classic Ingress, its own CRDs (**IngressRoute**, **Middleware**, etc.), and a production-ready **Gateway API** implementation.
- **Strengths:** Easy to install, quick to get working; low barrier for small/medium clusters.
- **Weaknesses:** In very large, complex mesh-style environments, it’s not as “mesh-native” as Istio / Cilium / kgateway.
### **HAProxy Ingress Controller**
- **Architecture:** Go-based controller in front, classic **HAProxy** as the data-plane. Configuration is usually generated via ConfigMap + annotations into a HAProxy config file.
- **APIs:** Ingress v1 is the main interface; recent versions also support **Gateway API**.
- **Strengths:** HAProxy-level performance and strong TCP/L4 capabilities.
- **Weaknesses:** CRD ecosystem is thinner than some others, configuration strategy is still heavily annotation + ConfigMap driven.
### **Kong Ingress Controller**
- **Architecture:** Separate **Kong Gateway** data-plane (NGINX + OpenResty) and a **Kong Ingress Controller (KIC)** acting as control-plane.
- **APIs:** Ingress, Gateway API, and its own CRDs like **KongPlugin**, **KongConsumer**, etc.
- **Strengths:** Very strong API gateway feature set; plugin ecosystem is huge.
- **Weaknesses:** If you “just want a simple ingress,” it can feel a bit overkill and “enterprise-y”.
### **Contour**
- **Architecture:** **Envoy** as the data-plane, **Contour** as a separate control-plane. Envoy runs as a Deployment/DaemonSet, Contour runs as a separate Deployment.
- **APIs:** Ingress, its own powerful **HTTPProxy** CRD, plus solid **Gateway API** support.
- **Strengths:** Presents the power of Envoy through a relatively clean API; HTTPProxy is great for advanced L7 routing.
- **Weaknesses:** Not a full mesh; lives mostly in the “ingress/gateway + strong L7” space.
### **Pomerium Ingress Controller**
- **Architecture:** Uses Pomerium as an **identity-aware proxy** for the data-plane, with an ingress controller-style control-plane layered around it.
- **APIs:** Ingress, its own CRDs, and **Gateway API** support.
- **Strengths:** Identity-centric access control (user, group, device context) is first-class. Perfect for “Zero Trust front door” use-cases.
- **Weaknesses:** Not meant as a general-purpose L4/L7 load balancer; its main job is identity and policy.
### **kgateway**
- **Architecture:** Envoy-based data-plane with a single **modular control-plane** that unifies ingress, API gateway, service mesh, and even AI gateway functionality.
- **APIs:** Designed **Gateway API first**; evolved from Gloo experience into a modern control-plane.
- **Strengths:** Ambition to handle ingress + gateway + mesh with a single tool; very modern design.
- **Weaknesses:** Brand-new identity compared to Istio / Cilium; ecosystem is growing but not yet “everywhere”.
### **Istio Ingress Gateway**
- **Architecture:** Classic **service mesh**: an Envoy sidecar in each pod, plus an **Ingress Gateway** Envoy Deployment at the edge. Control-plane is istiod.
- **APIs:** Istio Gateway and VirtualService CRDs, plus strong **Gateway API** support. There is a clear roadmap to rely more on Gateway API in the future.
- **Strengths:** Full mesh + L7 policy + security + advanced traffic management in one package.
- **Weaknesses:** Learning curve is steep; heavy for small clusters.
### **Cilium Ingress / Gateway**
- **Architecture:** Hybrid model: eBPF-based L3/L4 and Envoy-based L7. Cilium is a CNI + service mesh; its **Ingress** and **Gateway API** support sit on top of that.
- **APIs:** Ingress and Gateway API (HTTPRoute, GRPCRoute, TLSRoute, etc.).
- **Strengths:** Very efficient data path with eBPF at the bottom and Envoy for L7; gateway and CNI from the same stack.
- **Weaknesses:** If you “just want to route two services,” it can be overkill; you have to think about the cluster’s entire networking model.
---
## **2. Configuration & Annotation Compatibility**
Here we look at:
- “What’s the migration pain from Ingress + NGINX annotations?”
- “How messy are the CRDs?”
- “Is Gateway API supported?”
You also get a small YAML snippet per tool family.
### **Traefik**
- **Support:** Ingress, its own CRDs (**IngressRoute**, **Middleware**), and a mature **Gateway API** implementation.
- **From NGINX land:** With newer Traefik versions, there’s specific effort to make life easier for people coming from ingress-nginx and annotation-heavy configs.
- **Complexity:** If you dive into its CRDs, there’s some learning involved, but overall readability is decent.
Example **Gateway + HTTPRoute** (generic Gateway API, usable with many implementations):
```yaml
apiVersion: gateway.networking.k8s.io/v1
kind: Gateway
metadata:
name: web-gw
namespace: prod
spec:
gatewayClassName: traefik
listeners:
- name: http
protocol: HTTP
port: 80
---
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
name: web
namespace: prod
spec:
parentRefs:
- name: web-gw
rules:
- matches:
- path:
type: PathPrefix
value: /
backendRefs:
- name: web-svc
port: 80
```
### **HAProxy Ingress Controller**
- **Support:** Ingress v1 as the main API; huge amount of behavior is controlled via annotations + ConfigMap; and there is **Gateway API** support coming up as well.
- **From NGINX land:** Annotation mindset is similar; if you were already living in “NGINX annotation soup,” this will feel familiar.
- **Complexity:** Very powerful, but the annotation list is long; going in without documentation can cause headaches.
Minimal Ingress example:
```yaml
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
name: web
annotations:
haproxy.org/ssl-redirect: "true"
spec:
ingressClassName: haproxy
rules:
- host: web.example.com
http:
paths:
- path: /
pathType: Prefix
backend:
service:
name: web-svc
port:
number: 80
```
### **Kong Ingress Controller**
- **Support:** Ingress, Gateway API, and Kong-specific CRDs like **KongIngress**, **KongPlugin**, **KongConsumer**, etc.
- **From NGINX land:** Some patterns feel familiar, but using CRDs + labels/annotations instead of pure annotation config is the healthier way.
- **Complexity:** Once you step into the plugin ecosystem, the config surface gets large—this is its biggest strength and also complexity source.
Simple HTTPRoute + plugin example:
```yaml
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
name: web
annotations:
konghq.com/plugins: rate-limit
spec:
parentRefs:
- name: kong-gw
rules:
- matches:
- path:
type: PathPrefix
value: /
backendRefs:
- name: web-svc
port: 80
---
apiVersion: configuration.konghq.com/v1
kind: KongPlugin
metadata:
name: rate-limit
config:
second: 10
plugin: rate-limiting
```
### **Contour**
- **Support:** Ingress, **HTTPProxy** CRD, plus Gateway API support.
- **From NGINX land:** Instead of annotations everywhere, you use HTTPProxy objects. At first it feels like “too many CRDs,” but readability increases a lot.
- **Complexity:** HTTPProxy brings a lot of power; the trade-off is more YAML.
Example HTTPProxy:
```yaml
apiVersion: projectcontour.io/v1
kind: HTTPProxy
metadata:
name: web
namespace: prod
spec:
virtualhost:
fqdn: web.example.com
routes:
- conditions:
- prefix: /
services:
- name: web-svc
port: 80
```
### **Pomerium Ingress Controller**
- **Support:** Ingress + Pomerium CRDs, with Gateway API support as well.
- **From NGINX land:** The main object here is “policy”: you declare who can access what and under which conditions on a host.
- **Complexity:** Less about L7 routing, more about “who is allowed to get in”. Network folks might shrug; security folks will smile.
Example Pomerium policy (simplified):
```yaml
apiVersion: pomerium.io/v1
kind: PomeriumPolicy
metadata:
name: web-policy
spec:
from: https://web.example.com
to: http://web-svc.prod.svc.cluster.local:80
allow:
- email: devops@example.com
```
### **kgateway**
- **Support:** **Gateway API** is the primary interface; Envoy policy and routing behavior is mainly managed via Gateway API objects plus additional CRDs.
- **From NGINX land:** You don’t “translate annotations”; you jump to a different generation—pure Gateway API thinking.
- **Complexity:** The feature set is broad, but the resource model is clean and aligned with Gateway API (GatewayClass, Gateway, HTTPRoute, etc.).
### **Istio Ingress Gateway**
- **Support:** Istio Gateway + VirtualService + DestinationRule CRDs, and Gateway API.
- **From NGINX land:** You move from “one Ingress object for everything” to “Gateway + VirtualService + DestinationRule + Policy + …”
- **Complexity:** Extremely powerful, extremely detailed. Seeing a wrong VirtualService may cause a slight blood pressure drop in some SREs.
Simple Istio Gateway + VirtualService:
```yaml
apiVersion: networking.istio.io/v1
kind: Gateway
metadata:
name: web-gw
spec:
selector:
istio: ingressgateway
servers:
- port:
number: 80
name: http
protocol: HTTP
hosts:
- web.example.com
---
apiVersion: networking.istio.io/v1
kind: VirtualService
metadata:
name: web
spec:
hosts:
- web.example.com
http:
- route:
- destination:
host: web-svc
port:
number: 80
```
### **Cilium Ingress / Gateway**
- **Support:** Ingress and **Gateway API** (HTTPRoute, GRPCRoute, etc.) for modern traffic management.
- **From NGINX land:** If you’re already on Cilium CNI, moving directly to Gateway API via Cilium Gateway is natural.
- **Complexity:** Managing both networking and L7 together is powerful but mentally heavy; you’re not “just installing an ingress controller.”
---
## **3. Protocol & Traffic Support**
Here we ask:
“Is it just HTTP, or does it handle TCP/UDP, gRPC, WebSocket, HTTP/3, mTLS, etc. naturally?”
### **Traefik**
- Supports HTTP/1.1, HTTP/2, WebSocket, gRPC, and with newer versions, **HTTP/3 / QUIC** as well.
- TCP/UDP routing is possible, but its real strength is L7/HTTP.
- Supports mTLS, TLS passthrough, SNI-based routing, etc.
### **HAProxy Ingress Controller**
- With HAProxy under the hood, you get full TCP/L4 capabilities: HTTP, TCP, TLS termination, raw TCP load balancing, and so on.
- WebSocket, HTTP/2, gRPC proxying are supported; configuration is usually controlled via annotations/ConfigMaps.
- Great candidate if you want to offload heavy L4 workloads into the cluster.
### **Kong Ingress Controller**
- Strong support for HTTP/1.1, HTTP/2, WebSocket, gRPC and even **TCP/UDP**; with Gateway API you can model this with different Route types.
- mTLS, mutual authentication, and client certificate verification are provided via plugins such as mtls-auth.
### **Contour**
- Thanks to Envoy, you get HTTP/1.1, HTTP/2, gRPC, WebSocket, TLS termination out of the box. For pure TCP/UDP you usually rely on a separate load balancer.
- With HTTPProxy you have powerful SNI and header-based HTTP routing.
### **Pomerium**
- Focus is on HTTP(S) traffic and identity-based authorization. If you want TCP/UDP, you typically layer another tool for that.
- Strong in mTLS, identity, and OIDC integration.
### **kgateway**
- Envoy-based, so HTTP/1.1, HTTP/2, gRPC, WebSocket, TCP/TLS are all supported and controllable through Gateway API.
- Also positions itself for “modern” traffic such as AI/LLM requests, with special routing/rate limiting scenarios.
### **Istio Ingress Gateway**
- Handles HTTP/1.1, HTTP/2, gRPC, WebSocket, TCP, mTLS, SNI—you name it.
- Since it’s tied into the mesh, you also get the same protocol richness for east-west traffic inside the cluster.
### **Cilium Ingress / Gateway**
- With Gateway API you can manage HTTP, gRPC, TLS, TCP routing; GRPCRoute lets you do method-level routing.
- Underneath, eBPF handles L3/L4 efficiently while Envoy gives you rich L7 capabilities.
---
## **4. Traffic Management & Advanced Routing**
Here are the fun bits:
Canary, blue-green, A/B testing, weight-based routing, header-based routing…
### **Traefik**
- Supports path/host-based routing, header-based routing, weight-based routing for canary, and request mirroring.
- More powerful than basic Ingress, but not as policy-crazy as Istio / Kong.
### **HAProxy Ingress**
- Offers path/host/header-based L7 routing, and advanced L4 load balancing on the HAProxy side.
- Canary / blue-green are possible but usually involve more manual config.
### **Kong Ingress Controller**
- First-class canary, blue-green, and A/B testing with weight-based routing and related plugins.
- As an API gateway, it also brings rate limiting, circuit breaking, request/response transformation, etc.
### **Contour**
- HTTPProxy offers weight-based routing, header-based routing, subdomain/path routing.
- Canary and blue-green setups are straightforward and readable using the HTTPProxy CRD.
### **Pomerium**
- Main job is “who can get in” rather than “how do we split traffic.”
- For canary/blue-green, you’d typically offload traffic management to another L7 proxy and let Pomerium handle identity/policy.
### **kgateway**
- Envoy + Gateway API = advanced traffic management, including modern scenarios like multi-region AI traffic, LLM cost control, rate limiting, etc.
### **Istio Ingress Gateway**
- **Canary, blue-green, A/B testing, traffic mirroring, fault injection**—all your SRE case studies live here.
- One of the richest options for traffic management; the price is complexity.
### **Cilium Ingress / Gateway**
- Uses Gateway API for weight-based routing, path/host routing, and with GRPCRoute you can route by gRPC method.
- Since Cilium is also a service mesh, you can define advanced policies mesh-side and integrate them with the gateway.
### **Example: Simple Canary with Istio**
```yaml
apiVersion: networking.istio.io/v1
kind: VirtualService
metadata:
name: web
spec:
hosts:
- web.example.com
http:
- route:
- destination:
host: web-svc
subset: v1
weight: 90
- destination:
host: web-svc
subset: v2
weight: 10
```
This YAML says: “Let’s send 10% to v2, check if the world burns, then gradually crank it up.”
---
## **5. Security Features**
mTLS, JWT, OAuth/OIDC integration, IP allow/deny lists, WAF, rate limiting, etc.
### **Traefik**
- Built-in Let’s Encrypt integration, TLS/mTLS, IP allow/deny, rate limiting, basic auth, forward auth via **middlewares**.
- WAF scenarios can be handled via Coraza WAF integration.
### **HAProxy Ingress**
- TLS termination, SNI, client certificate verification, rate limiting, classic HAProxy security features brought into the ingress world.
- WAF is usually an external or enterprise HAProxy feature.
### **Kong Ingress Controller**
- JWT, OAuth2, key-auth, mTLS, rate limiting, ACL, IP restriction, bot detection, WAF integrations… Security is plugin heaven here.
- If you want “API gateway + ingress + centralized security policies,” Kong is one of the strongest options.
Very simplified JWT validation example:
```yaml
apiVersion: configuration.konghq.com/v1
kind: KongPlugin
metadata:
name: jwt-auth
plugin: jwt
config:
uri_param_names:
- jwt
---
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
name: web
annotations:
konghq.com/plugins: jwt-auth
...
```
### **Contour**
- Envoy-based, so you inherit mTLS, SNI, TLS policies and AuthService/ext_authz integrations.
- You can plug in external identity providers and WAF tools via Envoy filters.
### **Pomerium**
- Full “security nerd” mode: context-aware access, mTLS, OIDC, SSO, device/location-aware policy, Zero Trust approach.
- Ideal for VPN-less access to internal apps, “only corporate laptops allowed,” etc.
### **kgateway**
- Envoy security (mTLS, JWT, OAuth, WAF) plus Gateway API-based policy modeling gives you a modern security layer at the edge.
### **Istio Ingress Gateway**
- Together with the mesh you can have **mTLS by default** cluster-wide.
- JWT validation, request authentication, and AuthorizationPolicy-based RBAC—all built-in.
### **Cilium**
- eBPF-based network policy + Envoy L7 policy combine to provide strong security at L3/L4 and L7.
- When used with Cilium service mesh, mTLS and identity-based policies become powerful.
---
## **6. Observability**
The part where SRE hearts are either broken or healed:
Prometheus metrics, Grafana dashboards, tracing, access logs…
### **Traefik**
- Prometheus metrics, access logs, OpenTelemetry integration.
- For small/medium scale, it gives you a good picture of “what’s happening on the edge.”
### **HAProxy Ingress**
- HAProxy’s legendary stats page plus Prometheus exporter and access logs.
- Great for detailed L4/L7 connection metrics.
### **Kong**
- Prometheus metrics, log targets (Elastic, Loki, etc.), tracing integrations; Enterprise adds even more observability options.
### **Contour**
- Envoy metrics + Contour metrics; plenty of Grafana dashboards floating around.
### **Pomerium**
- Detailed audit logs and policy-level visibility for identity/access flows.
- Very useful if your main question is “who did what, from where, and when”.
### **kgateway**
- Envoy + modern gateway ecosystem = OpenTelemetry, Prometheus, and structured logs all in one place.
### **Istio**
- Telemetry v2 provides extremely rich metrics, logs, and tracing. The Ingress Gateway is part of that same telemetry system.
### **Cilium**
- eBPF gives you flow-level metrics, policy hits, dropped packets; Envoy adds L7 metrics on top.
- If you want to deeply understand what’s flowing across your cluster, it’s one of the best.
---
## **7. Performance & Resource Usage**
Touchy subject—everyone claims to be the fastest. Let’s stay high-level and focus on general patterns plus some public benchmarks that compare configuration update times and latency.
From public Gateway API benchmarks, a few patterns:
- **Cilium, Istio, Kong** stand out in terms of configuration update latency and responsiveness.
- **kgateway** and NGINX-based solutions land in the middle.
- **Traefik** often appears among the slower ones regarding config update latency.
This is mostly about **control-plane / config application speed**. Data-plane throughput is another dimension, but the results still show some interesting trends.
### **Traefik**
- **Proxy type:** L7-focused reverse proxy.
- **General feel:** Config updates are somewhat heavier than some rivals, but in small/medium loads it’s not a big issue.
### **HAProxy Ingress**
- **Proxy type:** L4 + L7, benefiting from HAProxy’s well-known performance.
- **General feel:** Very effective under high concurrency; just manage resource limits carefully.
### **Kong**
- **Proxy type:** NGINX/OpenResty-based L7 gateway with TCP/UDP support.
- **General feel:** In API gateway scenarios, strong throughput and solid latency.
### **Contour**
- **Proxy type:** Envoy; modern high-performance L7 proxy.
- **General feel:** Lightweight control-plane (Contour) with a strong data-plane (Envoy).
### **Pomerium**
- **Proxy type:** Identity-aware HTTP proxy.
- **General feel:** You are paying for “inspect every request through policy,” which is expected; the value is in security, not raw throughput.
### **kgateway**
- **Proxy type:** Envoy, tuned for API gateway/microgateway and service/multi-mesh scenarios.
- **General feel:** Built to handle large-scale, complex traffic management.
### **Istio**
- **Proxy type:** Envoy sidecar everywhere plus an Envoy Ingress Gateway.
- **General feel:** Sidecars and extra hops do add overhead, but in return you get security and observability, which many enterprises find totally worth it.
### **Cilium**
- **Proxy type:** eBPF for L3/L4, Envoy for L7.
- **General feel:** Excellent latency/throughput thanks to kernel-space optimizations and advanced L7 capabilities on top.
---
## **8. Installation & Community Support**
We look at Helm charts, Operators, docs quality, GitHub activity, and enterprise support.
### **Traefik**
- **Install:** Helm charts, Operator, good Gateway API documentation.
- **Community:** Very active; Traefik Labs blogs and Gateway API investments are strong.
### **HAProxy Ingress**
- **Install:** Helm charts and YAML manifests; both Community and Enterprise variants exist.
- **Community:** HAProxy itself has a big community; the Kubernetes-specific bits are solid but not as mainstream as NGINX.
### **Kong**
- **Install:** Helm charts, KIC documentation, and managed options via Kong Konnect.
- **Community:** Very active OSS + Enterprise user base; widely used in large companies.
### **Contour**
- **Install:** Helm, manifests, and detailed guides for enabling Gateway API.
- **Community:** CNCF project; close ties with the Envoy ecosystem.
### **Pomerium**
- **Install:** Helm charts, identity-focused docs, cert-manager/Gateway API integration guides.
- **Community:** Popular in security and Zero Trust circles.
### **kgateway**
- **Install:** Official quickstarts and docs focused on Envoy + Gateway API setups.
- **Community:** Builds on the Gloo heritage and integrates with CNCF / Gateway API ecosystem; quickly growing.
### **Istio**
- **Install:** istioctl, Helm, ambient/sidecar modes; a huge documentation set.
- **Community:** CNCF heavyweight; widely adopted in both research and industry.
### **Cilium**
- **Install:** One stack for CNI + service mesh + gateway; Helm charts and very detailed blogs and guides.
- **Community:** Star of the CNI world; serious investments into Gateway API as well.
---
## **9. Ecosystem & Compatibility**
Cloud vendor integrations, compatibility with other CNCF projects, plugin/extensions…
- All of them work on AKS/EKS/GKE and other managed Kubernetes offerings because they’re plain Kubernetes controllers/CRDs.
- The **Gateway API** itself is designed to be **vendor-neutral** and **role-oriented**, so these implementations are meant to coexist nicely.
### **Traefik**
- Works nicely on bare-metal, on-prem, and all major clouds.
- Middleware concept (rate limiting, auth, WAF integration, etc.) acts as a lightweight plugin model.
### **HAProxy Ingress**
- HAProxy runs everywhere; Kubernetes integration is multi-cloud friendly.
- Particularly useful when you want to offload complex TCP/UDP traffic from cloud load balancers.
### **Kong**
- Can be used as Kubernetes ingress/gateway or as a classical API gateway on VMs; great for hybrid and multi-cloud.
- Plugin ecosystem brings integrations for observability, security, transformations, and many third-party systems.
### **Contour**
- Envoy-powered; plays well with Istio, Cilium, and other Envoy-based projects.
### **Pomerium**
- Deep integrations with identity providers (OIDC, SAML, Google Workspace, etc.); can protect non-Kubernetes apps as well.
### **kgateway**
- Aims to be one of the reference implementations of a modern Gateway API-based Envoy controller.
- Positioned to work well with multiple meshes and cloud environments.
### **Istio**
- Integrates tightly with Envoy, Prometheus, Jaeger/Tempo, Kiali, Grafana, and many CNCF tools.
### **Cilium**
- CNI + mesh + gateway = you’re effectively buying most of your Kubernetes networking/security stack from one provider, while still integrating with lots of CNCF projects.
---
## **10. Future-Proofing & Roadmap**
This is the “Will I still sleep well 3–5 years from now?” section.
- **Ingress API** is stable but limited, and its heavy reliance on annotations has become a common pain point.
- **Gateway API** is the “next generation” replacement for Ingress, designed to be more expressive, role-based, and vendor-neutral.
- The **ingress-nginx** project is sliding into EOL territory in the coming years, which pushes the ecosystem naturally towards Gateway API + newer controllers.
In that picture:
- Tools that are **Gateway API first** (kgateway, Cilium, Istio, Traefik, Kong, Contour, Pomerium, HAProxy) look like the safest long-term bets.
- Mesh-centric ecosystems like **Istio** and **Cilium** will likely keep pushing the “service mesh + gateway + security + observability” package approach.
- **kgateway** is clearly aiming for the future with Envoy + Gateway API + AI/LLM gateway capabilities.
In short:
**The future is Gateway API, and the winners are going to be the stacks that combine Envoy/eBPF with strong, flexible control-planes.**
---
## **Scoring Scale**
Before we dive into the big table, let’s define the scale:
- **1** → “Please don’t try this in prod.”
- **2** → “Fine for a PoC, but think twice before prod.”
- **3** → “It works, but you’ll sweat a bit.”
- **4** → “Solid choice, even for serious environments.”
- **5** → “Ship it to prod and don’t look back too often.”
This is subjective, but rooted in the analysis above.
---
## **Comparison Table (1–5)**
> Note: These are **general** evaluations. For specific use-cases, scores can shift (e.g. if you’re purely doing identity-aware access, Pomerium gets an automatic +1 in your context).
| **Tool** | **Controller Architecture** | **Config Simplicity** | **Protocol & Traffic** | **Traffic Management** | **Security** | **Observability** | **Performance & Resource** | **Install Simplicity** | **Ecosystem & Community** | **Future-Proofing** |
| --- | --- | --- | --- | --- | --- | --- | --- | --- | --- | --- |
| **Traefik** | 4 | 4 | 4 | 3 | 3 | 4 | 3 | 4 | 4 | 4 |
| **HAProxy Ingress** | 4 | 3 | 4 | 3 | 3 | 3 | 4 | 3 | 3 | 3 |
| **Kong Ingress** | 4 | 3 | 5 | 5 | 5 | 4 | 4 | 3 | 5 | 5 |
| **Contour** | 4 | 3 | 4 | 4 | 4 | 4 | 4 | 3 | 4 | 4 |
| **Pomerium Ingress** | 3 | 3 | 3 | 2 | 5 | 4 | 3 | 3 | 4 | 4 |
| **kgateway** | 5 | 3 | 5 | 5 | 4 | 4 | 4 | 3 | 4 | 5 |
| **Istio Ingress Gateway** | 5 | 2 | 5 | 5 | 5 | 5 | 4 | 2 | 5 | 5 |
| **Cilium Ingress/Gateway** | 5 | 3 | 5 | 4 | 4 | 5 | 5 | 3 | 5 | 5 |
Quick notes:
- **Traefik** – Easy to learn, flexible, playing nicely with Gateway API; might feel a bit “light” if you want super-advanced traffic policies.
- **HAProxy Ingress** – Performance beast, especially for TCP/L4; annotation-centric config gives slight “old school” vibes.
- **Kong** – If you want “Ingress + API Gateway + security + plugins,” it’s very compelling; the trade-off is complexity.
- **Contour** – Nice option if you want Envoy power with a clean, focused control-plane and HTTPProxy.
- **Pomerium** – Less of an ingress and more of an “identity-aware secure front door”; a joker card for SSO/Zero Trust.
- **kgateway** – Rising star of the Gateway API era; Envoy + modular control-plane + AI/LLM features make it very future-leaning.
- **Istio** – If you want *everything*—mesh, mTLS, canary, observability—this is one of the strongest packages, and also one of the hardest to master.
- **Cilium** – If you want networking + security + gateway all in an eBPF-powered stack, it’s a very strong long-term investment.
---
### **Closing Thoughts**
With NGINX Ingress walking toward EOL, the good news is:
You have many options, and they’re not just **Ingress controllers**—they’re doorways into a world of **Gateway API + mesh + security**.
As a rough compass:
- For a **simple but modern ingress**: **Traefik, Contour, HAProxy Ingress**
- For **Ingress + API Gateway + plugins galore**: **Kong, kgateway**
- For **“mesh everything, secure everything”**: **Istio, Cilium**
- For **VPN-less, Zero Trust front door**: **Pomerium**
The rest depends on your system’s complexity, your team’s patience, and who you’d like to blame when the pager goes off at 3 AM.
---
## The 3 Best Open-Source Notion Alternatives to Self-Host (2025)
Author: Serdarcan Büyükdereli
Date: 2025-09-15
Category: Open Source
URL: https://theinfinity.dev/articles/the-3-best-open-source-notion-alternatives
### Introduction - Is There Life After Notion?
We all know Notion. With its flexible structure, clean interface, and "all-in-one" philosophy, it has captured the hearts of millions. But what if you want complete control over your data? Or what if you're looking for an open-source solution that runs on your own server, free from monthly subscription fees? If you answered "Yes!", then you're ready to see that there is indeed life after Notion—and it can be much more exciting.
In this article, we'll examine three powerful, open-source, and self-hostable alternatives that are vying for Notion's throne. We will explore the visual richness of **AFFiNE**, the data privacy and developer power of **Siyuan**, and the speed and simplicity of **Docmost** for team documentation. Our goal is to clearly determine which tool is the best candidate to become your "personal Notion."
---

### [AFFiNE](https://github.com/toeverything/AFFiNE): The Open-Source Twin to Notion
If you love Notion's flexibility and visual interface but want an open-source alternative, AFFiNE should be your first stop. It captures Notion's "all-in-one" spirit by combining traditional documents with Kanban boards, which function like Notion's databases, and whiteboards that offer an infinite canvas.
- It's a Notion-like, all-in-one platform that combines note-taking, drawing, and planning into a single, intuitive interface.
- Its biggest differentiator is the ability to transform a standard document into a visual whiteboard with a single click, providing a seamless transition between text and visuals.
- With over 30,000 stars on GitHub and an active Discord community, it has strong and continuously growing support behind it.
- You can get started instantly with AFFiNE Cloud or effortlessly install it on your own server with a single `docker run` command.
- While it values data ownership with its "local-first" architecture, its developer API is still maturing, with the current focus being more on the end-user experience.
- Its core features are completely open-source and free under a generous MIT license, while offering subscription plans for cloud-based synchronization and collaboration features.
- It's the perfect alternative for users who love visual thinking, creative teams, and anyone looking for the visual and flexible structure of Notion.
[https://affine.pro/](https://affine.pro/)
---
: The Open-Source Twin to Notion {medium}](https://pub-281b318613c645e9b94ad4c4ec354208.r2.dev/articles/the-3-best-open-source-notion-alternatives/2.png)
### [Siyuan](https://github.com/siyuan-note/siyuan): The Notion for Privacy-Obsessed Power Users
Siyuan takes Notion's block-based structure as its foundation but builds its philosophy entirely on data ownership and privacy. All your data is stored directly on your computer or server in standard file formats, without ever passing through third-party servers. Its powerful API turns it into a dream tool for automation and integration.
- It's a personal knowledge management system that keeps your data entirely local, combining Notion's block structure with privacy and developer flexibility.
- It treats every paragraph, list, or heading as a separate "block" and its ability to link these blocks together turns it into an incredibly flexible database.
- Siyuan has a very strong user base, especially in Asia, and its international community is steadily growing through GitHub and official forums, with constant contributions to the tool.
- It runs directly as a desktop application for Windows, macOS, and Linux, and can also be hosted on a server via its Docker image for web access.
- Thanks to its comprehensive REST API, it offers immense flexibility to developers who want to programmatically access their notes, build automations, and integrate with other applications in ways you couldn't imagine with Notion.
- It is open-source under the AGPLv3 license and is completely free for basic use, with a modest annual subscription model for more advanced features.
- It's ideal for advanced users and developers who prioritize data privacy above all else and love Notion's block system but want full control via an API.
[https://b3log.org/siyuan/en/](https://b3log.org/siyuan/en/)
---
: The Notion for Privacy-Obsessed Power Users {medium}](https://pub-281b318613c645e9b94ad4c4ec354208.r2.dev/articles/the-3-best-open-source-notion-alternatives/3.png)
### [Docmost](https://github.com/docmost/docmost): A Lean and Fast Notion for Teams
Do you primarily use Notion for your team's technical documentation and internal wiki? If so, Docmost's minimalist and purpose-driven approach is perfect for you. Designed as a direct competitor to Confluence, this tool avoids the sometimes-overwhelming complexity of Notion and focuses on being one thing: a fast and effective team wiki.
- It's a high-performance, minimalist documentation platform designed for software teams that you can host on your own server, focusing on Notion's wiki functionality.
- Built with a modern architecture using Go and Svelte, it runs incredibly fast, consumes very few system resources, and has an interface that focuses only on essential features.
- It has a smaller, more niche community where interaction and support are handled directly through the project's GitHub Discussions page in a developer-focused manner.
- It is available only as a self-hosted solution and can be up and running in minutes for a technical user, thanks to its Docker-based setup.
- It is completely open-source and free under the AGPLv3 license; there are no hidden costs or paid tiers.
- It is perfect for technical teams that use Notion as a team wiki but are looking for a faster, simpler, and completely free alternative.
[https://docmost.com/](https://docmost.com/)
---
### Conclusion - Choosing the Right Alternative
Notion is a great tool, but when you want to step out of its ecosystem and become the master of your own data, a variety of powerful alternatives are waiting for you. Your decision depends on which features of Notion you love the most and which of its drawbacks you want to leave behind.
- If you want **Notion's visual and versatile structure**, your choice should be **AFFiNE**.
- If you want to combine **Notion's block structure with absolute data control and API power**, then **Siyuan** is your tool.
- If you are simply looking for a **fast, simple, and free team wiki**, **Docmost** will meet all your expectations.
Remember, the best tool is the one that serves the needs of your project. Don't hesitate to try all three and choose the one that best fits your workflow.
---
## The Infinity Tech XXVI
Author: The Infinity Team
Date: 2025-09-09
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxvi
## 🚀**Happy Thursday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **32 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹Apple’s new iPhone 17 devices don’t have an AI-powered Siri yet. It doesn’t matter.
🔹A structured, practical guide to learning system design by breaking it down into mini-topics, practicing with real-world problems, and reinforcing knowledge by teaching others.
🔹 What is Mistral AI? Everything to know about the OpenAI competitor
🔹Russia's Enteromix Cancer Vaccine Shows 100% Efficacy In Early Trials
🔹Qwen3-Max arrives in preview with 1 trillion parameters, blazing fast response speed, and API availability
## Tech Orbit

---
### **Tech News**
🔹 [Apple’s new iPhone 17](https://techcrunch.com/2025/09/09/apples-new-iphone-17-devices-dont-have-an-ai-powered-siri-yet-it-doesnt-matter/)devices don’t have an AI-powered Siri yet. It doesn’t matter.
🔹 [AirPods Pro 3 arrive with heart-rate](https://techcrunch.com/2025/09/09/airpods-pro-3-arrive-with-heart-rate-sensing-and-live-translation-using-apple-intelligence/) sensing and live translation using Apple Intelligence
🔹 [Qwen3-Max arrives in preview with 1 trillion](https://venturebeat.com/ai/qwen3-max-arrives-in-preview-with-1-trillion-parameters-blazing-fast) parameters, blazing fast response speed, and API availability
🔹[Why AI chatbots hallucinate](https://www.businessinsider.com/why-ai-chatbots-hallucinate-openai-chatgpt-anthropic-claude-2025-9), according to OpenAI researchers
🔹 [Russia's Enteromix Cancer Vaccine](https://www.ndtv.com/health/russias-enteromix-cancer-vaccine-shows-100-efficacy-in-early-trials-9235033) Shows 100% Efficacy In Early Trials
### **Tech Articles**
🔹 [A structured, practical guide to learning](https://medium.com/@himanshusingour7/how-i-learned-system-design-d7444d454367)system design by breaking it down into mini-topics, practicing with real-world problems, and reinforcing knowledge by teaching others.
🔹[A deep dive into how Netflix re-architected the Tudum service](https://blog.bytebytego.com/p/how-netflix-tudum-supports-20-million)to support 20 million daily active users by implementing a CQRS pattern with an in-memory data model, eliminating the need for a distributed cache.
🔹[A case study on how GitHub re-architected their push](https://blog.quastor.org/p/how-github-rebuilt-their-push-processing-system-0157)processing pipeline from a monolithic job to a decoupled, event-driven system using Kafka to improve reliability and reduce latency.
🔹 [Practical lessons from building a small-scale AI application](https://www.thelis.org/blog/lessons-from-ai), highlighting the stochastic nature of AI development, the critical role of data quality, and the immaturity of off-the-shelf evaluation tools.
🔹[An analysis of the web's shift to double-keyed caching for enhanced privacy](https://addyosmani.com/blog/double-keyed-caching), detailing the trade-offs in performance and the impact on resource sharing and cache hit rates.
## Asteroid Ventures

---
### **Companies News**
🔹 [What is Mistral AI?](https://techcrunch.com/2025/09/09/what-is-mistral-ai-everything-to-know-about-the-openai-competitor/)Everything to know about the OpenAI competitor
🔹 [Atolio](https://www.atolio.com/blog/atolio-raises-series-a-to-bring-secure-enterprise-search-to-the-world) Raises Series A to Bring Secure Enterprise Search to the World
🔹 [QuEra](https://www.quera.com/press-releases/quera-expands-230-million-financing-round-advancing-quantum-accelerated-supercomputing) Expands $230 Million Financing Round Advancing Quantum-Accelerated Supercomputing
🔹 [Spinwheel](https://spinwheel.io/blog/in-the-news/pr-newswire/) Raises $30 Million Series A to Transform the Consumer Credit Ecosystem with Real-Time Data and Agentic AI
🔹 [Cassidy](https://www.cassidyai.com/blog/announcing-cassidys-10m-series-a) Lands $10M Series A
## Black Hole

[https://blog.algomaster.io/p/how-dns-actually-works](https://blog.algomaster.io/p/how-dns-actually-works)
[https://blog.bytebytego.com/p/ep179-kubernetes-explained](https://blog.bytebytego.com/p/ep179-kubernetes-explained)
[https://newsletter.memesmotivations.com/p/become-useful](https://newsletter.memesmotivations.com/p/become-useful)
## Cosmic Currents

[▶ Video](https://www.youtube.com/watch?v=1ULCOWZIPIM)
## Double Star

---
### Open Source Repositories
> 📦 **haxor-news**
> A classic Hacker News clone accessible via both a command-line interface and a web application.
> [https://github.com/donnemartin/haxor-news](https://github.com/donnemartin/haxor-news)[](https://github.com/unslothai/unsloth)*news-aggregator, python, cli-tools*
> 📦 **refetch**
> A convention-over-configuration data-fetching and state management library for React.
> [https://github.com/refetch-io/refetch](https://github.com/refetch-io/refetch)[](https://github.com/unslothai/unsloth)*data-fetching, react, frontend-development*
> 📦 **eShop**
> A reference implementation of a .NET-based microservices architecture for an e-commerce platform.
> [https://github.com/dotnet/eShop](https://github.com/dotnet/eShop)[](https://github.com/unslothai/unsloth)*microservices-architecture, dotnet, system-design*
> 📦 **bytebot**
> An AI-native automation platform for executing complex DevOps and CloudOps tasks using natural language.
> [https://github.com/bytebot-ai/bytebot](https://github.com/bytebot-ai/bytebot)[](https://github.com/unslothai/unsloth)*ai-automation, cloud-native, devops*
> 📦 **parlant**
> A self-hosted, open-source customer messaging platform, designed as an alternative to Intercom or Crisp.
> [https://github.com/emcie-co/parlant](https://github.com/emcie-co/parlant)[](https://github.com/unslothai/unsloth)*customer-messaging, elixir, saas-development*
> 📦 **openwrt**
> A Linux-based embedded operating system targeting network routers and embedded devices.
> [https://github.com/openwrt/openwrt](https://github.com/openwrt/openwrt)[](https://github.com/unslothai/unsloth)*embedded-linux, networking, firmware-development*
> 📦 oha
> A high-performance, Rust-based HTTP load-testing tool for performance and reliability analysis.
> [https://github.com/hatoo/oha](https://github.com/hatoo/oha)[](https://github.com/unslothai/unsloth)*load-testing, rust, performance-engineering*
## Open Source Analysis

[https://opensourcedaily.blog/rallly-opensource-scheduling-polls-that-end-email-backandforth](https://opensourcedaily.blog/rallly-opensource-scheduling-polls-that-end-email-backandforth)
[https://opensourcedaily.blog/hyperswitch-the-opensource-composable-payments-engine-redefining-control](https://opensourcedaily.blog/hyperswitch-the-opensource-composable-payments-engine-redefining-control)
## Galactic Meme

---

## Celstial Quotes

---
> “There is no place like 127.0.0.1.” — QuoteFancy Wallpaper
## Stellar Prompts

---
**The Digital Confrontation**
This prompt uses AI not as a source of information, but as a personal mirror. It asks the AI to analyze what it has learned from your interactions (your style of questioning, your language, your silences) to create an unfiltered portrait of you. The goal is to confront your own blind spots in their rawest form.
```yaml
"Tell me the worst thing you know about me… even if I haven't told you. From the style of my questions, my silences, my language, from between the lines, create a complete portrait of me. Then, deliver it to me directly, without compliments, in its final form."
```
---
## The Easiest Way to Back Up PostgreSQL to Google Drive: Meet Rclone!
Author: Serdarcan Büyükdereli
Date: 2025-09-06
Category: DevOps Blog
URL: https://theinfinity.dev/articles/postgresql-backup-rclone-guide
**Welcome to The Infinity!** If you're anything like me, spending your nights wondering, "Did I remember to back up the database? What would I do if something happened?" then you've come to the right place.
Backing up a database, especially one like PostgreSQL that holds precious data, is absolutely critical. But let's be honest, it can sometimes be a tedious and complicated task. In this article, we'll walk you through how to use a fantastic tool called **Rclone** to automatically and securely back up your data to Google Drive—for free. Don't be intimidated; by the end of this guide, you'll be one of those people who sleep soundly, knowing your data is safe. Let's get started!
### **Step 1: Getting Rclone Ready and Introducing It to Google Drive**
First, let's get Rclone installed on your server. Open up your terminal and paste in this magic command:
```bash
curl [https://rclone.org/install.sh](https://rclone.org/install.sh) | sudo bash
```
This command will install the latest version of Rclone on your system. Now comes the most crucial part: getting Rclone to talk to your Google Drive account. Relax, we won't get lost in Google's complex API panels. We'll take the simplest route.
Type `rclone config` in your terminal to start the wizard. Answer the questions just like this:
```
n) New remote
q) Quit config
n/q> n // We're telling it we want to create a new connection.
Enter name for new remote.
name> gdrive_backups // Give your connection a name you'll remember.
...
Choose a number from below...
...
22 / Google Drive
\ (drive)
...
Storage> 22 // We're choosing Google Drive.
Option client_id.
...
client_id> // THIS IS THE MOST IMPORTANT PART: Leave it blank and just press Enter!
Option client_secret.
...
client_secret> // LEAVE THIS BLANK AS WELL and press Enter! Rclone will use its own key.
Option scope.
...
1 / Full access all files...
\ (drive)
...
scope> 1 // Let's grant full access for now to keep things simple.
Option service_account_file.
...
service_account_file> // Leave it blank and press Enter.
Edit advanced config?
y/n> n // We don't need any advanced settings.
Use web browser to automatically authenticate rclone with remote?
y/n> y // Say yes, this is the easiest way.
```
After you type `y`, a little magic will happen. Rclone will give you a link in the terminal. Copy that link and paste it into your computer's web browser. Google will ask you, "An app called rclone wants to access your account, do you approve?" Go ahead and click "Allow."
After granting permission, you'll see a "Success!" page with a code. Copy that code and paste it back into your terminal. Finally, it will ask if this is a "Team Drive?"—answer `n`, confirm the settings with `y`, and exit with `q`.
That's it! To test the connection, type `rclone lsd gdrive_backups:`. If it lists the folders from your Google Drive, you're all set!
### **Step 2: The Star of the Night: The Automated Backup Script**
Now that Rclone is ready, let's write a small but mighty script that will dump our PostgreSQL backup and send it to Google Drive.
Create a file named `backup.sh` and paste the following into it:
```ini
#!/bin/bash
## --- ADJUST THE SETTINGS BELOW TO YOUR NEEDS ---
DB_NAME="my_database_name"
DB_USER="my_database_user"
RCLONE_REMOTE_NAME="gdrive_backups" # The name you gave the remote in rclone
GDRIVE_FOLDER="Database_Backups" # The folder in Drive where backups will go
## --- The Rest of the Script ---
TIMESTAMP=$(date +"%Y-%m-%d_%H-%M-%S")
BACKUP_FILE="/tmp/${DB_NAME}_${TIMESTAMP}.sql.gz"
echo "Taking PostgreSQL backup of: ${DB_NAME}"
## We dump the database with pg_dump and immediately compress it with gzip.
## Pro Tip: Using a ~/.pgpass file is more secure than putting passwords in scripts.
pg_dump -U $DB_USER -d $DB_NAME -h localhost --format=c --blobs | gzip > $BACKUP_FILE
## Let's check if pg_dump was successful.
if [ ${PIPESTATUS[0]} -ne 0 ]; then
echo "ERROR: pg_dump command failed!"
exit 1
fi
echo "Backup created successfully: ${BACKUP_FILE}"
echo "Uploading to Google Drive with Rclone..."
## We copy the file to the folder inside our Drive remote.
rclone copy $BACKUP_FILE "${RCLONE_REMOTE_NAME}:${GDRIVE_FOLDER}/" --progress
## Was rclone successful?
if [ $? -ne 0 ]; then
echo "ERROR: Rclone upload failed!"
exit 1
fi
echo "Upload complete. Deleting temporary file from server."
rm $BACKUP_FILE
echo "Process complete! See you at the next backup."
```
Don't forget to make this file executable with the command `chmod +x backup.sh`!
### **Step 3: Let's Hire the Robots: Automation with Cronjob**
Our script is great, but are we going to run it manually every night? Of course not! Linux's trusty scheduler, `cron`, was made for this.
Type `crontab -e` in the terminal and add this line to the very bottom of the file:
```
0 2 * * * /home/youruser/backup.sh >> /var/log/backup.log 2>&1
```
What does this line mean?
- `0 2 * * *`: This means "at 2:00 AM, every single night."
- `/home/youruser/backup.sh`: The full path to your script. **This is very important; you must use the correct path to your script.**
- `>> /var/log/backup.log 2>&1`: This part means "write everything the script says or does into this log file." This way, if something goes wrong, you can check the log to see what happened.
Save the file and exit. And that's it! You now have a robot. Every night at 2 AM, it will wake up, take your backup, upload it to Google Drive, and quietly complete its mission.
### **Closing**
And that's it! You now have an automation system that works diligently every night, moving your valuable data safely to the cloud. Thank you for reading this guide to the end.
If you find practical and life-saving DevOps solutions like this useful, **don't forget to register with The Infinity!** That way, you can become part of our community and be the first to know about new articles and tips.
Happy automating!
### **Resources & Further Reading**
- [**Rclone**](https://rclone.org/) **Official Website:** The main source for all things Rclone, including documentation, downloads, and community forums.
- [**Rclone**](https://rclone.org/drive/) **Google Drive Documentation:** The specific documentation page for the Google Drive remote, with all available options and advanced configurations.
- [**PostgreSQL**](https://www.postgresql.org/docs/current/app-pgdump.html) **pg_dump Documentation:** The official manual for the `pg_dump` command, detailing all the flags and backup formats.
- [**Crontab**](https://crontab.guru/) **Guru:** A simple and interactive editor for figuring out cron schedule expressions.
---
## 7 Incredible Open Source Chat Apps
Author: Serdarcan Büyükdereli
Date: 2025-08-31
Category: Open Source
URL: https://theinfinity.dev/articles/7-incredible-open-source-chat-apps
As you know, there are many messaging applications offered as cloud services today. These include apps like Slack, Discord, and Teams, and we could extend this list even further.
In this article, I will show you 7 amazing self-hosted chat apps that you can set up yourself.
## **1)** [**Lobe-Chat**](https://github.com/lobehub/lobe-chat)
[https://github.com/lobehub/lobe-chat](https://github.com/lobehub/lobe-chat)
LobeChat is a modern, open-source AI chat framework. Users can deploy the community edition on their own servers for free. Additionally, the LobeChat Cloud version provides all registered users with 450,000 free computation credits. For users with higher usage requirements, paid subscription plans are available.
**Features:**
- Compatible with various AI providers (OpenAI, Claude 3, Gemini).
- Supports creating and managing knowledge bases.
- Offers multi-modal text and voice interactions.
**Pros:**
- Developer-friendly and highly customizable.
- Modern and user-friendly interface.
**Cons:**
- Limited community support due to being a relatively new platform.
- Stability issues may arise from frequent updates.
---
## **2)** [**Rocket Chat**](https://github.com/RocketChat/Rocket.Chat)
[https://github.com/RocketChat/Rocket.Chat](https://github.com/RocketChat/Rocket.Chat)
[**Rocket.Chat**](http://rocket.chat/) is an open-source and customizable communication platform. The free Starter plan allows teams of up to 50 users to collaborate securely and provides support for 100 active customers per month. This plan includes premium features such as unlimited app integrations, unlimited push notifications, read receipts, federated channels, and multi-user direct messaging. Additionally, it offers advanced LDAP, SAML, and OAuth capabilities, as well as an air-gapped deployment option for enhanced security.
**Features:**
- Secure messaging and file sharing capabilities.
- Video conferencing support.
- Extensive integration options.
**Pros:**
- Strong data security and versatile integration support.
- Highly customizable with self-hosting options.
**Cons:**
- Setup process can be complex for beginners.
- High resource consumption.
---
## **3)** [**Mattermost**](https://github.com/mattermost/mattermost)
[https://github.com/mattermost/mattermost](https://github.com/mattermost/mattermost)
Mattermost is an open-source and secure team communication platform. It integrates messaging, file sharing, and project management tools to help teams work more efficiently. The free version offers unlimited message history, basic collaboration tools, and file sharing capabilities. Additionally, it provides full control with self-hosting options.
**Features:**
- Integration of messaging and project management.
- Strong API support for developers.
**Pros:**
- Secure and highly customizable.
- Extensive integration support for developer tools.
**Cons:**
- User interface may feel complex.
- Setup process can be time-consuming.
---
## **4)** [**Zulip**](https://github.com/zulip/zulip)
[https://github.com/zulip/zulip](https://github.com/zulip/zulip)
Zulip is a team collaboration tool that combines topic-based discussions with real-time messaging.
Zulip is an open-source team communication platform that combines topic-based messaging with real-time chat. Zulip's free plan, which you can host on your own server, includes all the essential team chat features and offers unlimited mobile notifications for up to 10 users. For larger organizations, there are paid plans that provide unlimited mobile notifications and additional support options while taking advantage of all the benefits of open-source software.
**Features:**
- Efficient communication with threaded conversations.
- Active community support.
**Pros:**
- Clear message organization.
- Active community support.
**Cons:**
- Outdated user interface design.
- Limited integration support compared to competitors.
---
## **5)** [**Chatwoot**](https://github.com/chatwoot/chatwoot)
[https://github.com/chatwoot/chatwoot](https://github.com/chatwoot/chatwoot)
Chatwoot is an open-source solution for managing customer support interactions across multiple channels.
Community Edition: This free version includes basic features and offers community support. However, it does not include advanced features like custom branding, SAML SSO, or role and permission management.
Open-source omni-channel support platform, an alternative to Intercom and Zendesk
**Features:**
- Multi-channel customer support.
- User-friendly interface.
**Pros:**
- Easy-to-use and customizable.
- Omni-channel support features.
**Cons:**
- Lacks some advanced features found in commercial tools.
- Scalability limitations may exist.
---
## **6)** [**Twake**](https://github.com/linagora/Twake)
[https://github.com/linagora/Twake](https://github.com/linagora/Twake)
Twake is an open-source collaboration platform offering messaging, file storage, and collaborative document editing. Twake combines all the essential features for collaboration, such as team chat, file storage, team calendar, and task manager, into a single platform.
**Features:**
- Integrated productivity tools.
- Modern interface and customizable architecture.
**Pros:**
- Open-source and highly customizable.
- Advanced team collaboration features.
**Cons:**
- Development activity may have decreased.
- Some features are incomplete or underdeveloped.
---
## **7)** [**Revoltchat**](https://github.com/revoltchat/self-hosted)
[https://github.com/revoltchat/self-hosted](https://github.com/revoltchat/self-hosted)
Revolt is a customizable open-source chat platform that can be self-hosted using Docker.
**Features:**
- Privacy-focused.
- Lightweight with self-hosting capabilities.
**Pros:**
- Highly customizable.
- Lightweight and efficient.
**Cons:**
- Limited community support.
- Smaller user base compared to other platforms.
Don’t miss out on exciting updates and insights—stay connected for more innovative features, announcements, and opportunities to explore!
---
## The Infinity Tech XXV
Author: Infinity Team
Date: 2025-08-24
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxv
## 🚀**Happy Tuesday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **2 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹Elon Musk tried to recruit Mark Zuckerberg to buy OpenAI six months ago — for less than $100B: filings
🔹Meta rolls out AI-powered translations to creators globally, starting with English and Spanish
🔹 Context Engineering: Moving Beyond Prompting in AI
🔹5 Things in Data Engineering That Still Hold True After 10 Years
## Tech Orbit

---
### **Tech News**
🔹[Meta rolls out AI-powered](https://techcrunch.com/2025/08/19/meta-rolls-out-ai-powered-translations-to-creators-globally-starting-with-english-and-spanish/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=e7d1c6ecd2c2d3cb3e3dd9f6da5a11acdc225126) translations to creators globally, starting with English and Spanish
🔹[Elon Musk’s xAI Published](https://www.forbes.com/sites/iainmartin/2025/08/20/elon-musks-xai-published-hundreds-of-thousands-of-grok-chatbot-conversations/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=900c4f17060e49af2eebefe2b0a9cb5c8a01f7e4) Hundreds Of Thousands Of Grok Chatbot Conversations
🔹[OpenAI launches](https://techcrunch.com/2025/08/18/openai-launches-a-sub-5-chatgpt-plan-in-india/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=84f8e98efc1df52f732665400d6db0d64ff9842d) a sub-$5 ChatGPT plan in India
🔹[China firm plans world’s](https://interestingengineering.com/innovation/china-worlds-first-pregnancy-humanoid-robot?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=89f938df4e72190191c9a47687950bffe5ddb606) first pregnancy humanoid robot using artificial womb
🔹[Cursor Alternative](https://qoder.com/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=6ec2dce581ab2575e842ea0e4888664f9a27f02e) AliBaba Qoder(Free Now)
🔹[Meta partners with](https://techcrunch.com/2025/08/22/meta-partners-with-midjourney-on-ai-image-and-video-models/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=c7134463219c334ee3b689beb4f3f77af7f65321) Midjourney on AI image and video models
🔹[Elon Musk tried to recruit Mark Zuckerberg](https://nypost.com/2025/08/22/business/elon-musk-tried-to-get-mark-zuckerberg-to-buy-openai-filings/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=4e1940b24ab4cdc0896b2808c0af03e1bce67fb2) to buy OpenAI six months ago — for less than $100B: filings
### **Tech Articles**
🔹[Context Engineering](https://www.digitalocean.com/community/tutorials/context-engineering-moving-beyond-prompting-ai?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=ca2a7ccead2495f93691e5b71e9b9222dd936676): Moving Beyond Prompting in AI
🔹[Use Envoy Gateway](https://www.cncf.io/blog/2025/08/26/use-envoy-gateway-as-the-unified-ingress-gateway-and-waypoint-proxy-for-ambient-mesh/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=50ad829f8980da54ba120deffe40002f2ade6013) as the Unified Ingress Gateway and Waypoint Proxy for Ambient Mesh
🔹[Microservices to Monolith](https://www.influxdata.com/blog/rust-monolith-migration-influxdb/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=cbb00591ebec1d94c538f4755dc20d3e080388b3), Rebuilding Our Backend in Rust
🔹[GraphQL API Basics](https://levelup.gitconnected.com/graphql-api-basics-best-practices-explained-simply-790b2f6c64c5?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=11d3d1fde9ed0e8db1a74da7e104ab22342bbe4b) & Best Practices (Explained Simply)
## Asteroid Ventures

---
### **Companies News**
🔹[Aalo Atomics](https://www.aalo.com/post/aalo-closes-100m-series-b?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=2ab4a88cb3ca28892af40c400c8ce287768b8ca0)Lands $100M Series B
🔹[SynergySuite](https://www.synergysuite.com/blog/synergysuite-raises-12-million-to-accelerate-ai-thats-redefining-restaurant-ops/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=42e59438e582e6e3476117a0dac2bf27e2fffe7a)Snags $12M Funding Round
🔹[TinyFish](https://blog.tinyfish.ai/the-web-outgrew-the-browser-98a464b5608a?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=d50cedff8f4afe47760d2ab19fce5b5b5c457da6)Scores $47M Funding Round
🔹[Definite](https://www.definite.app/blog/definite-raises-$10M?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=87617d6cb5f43bae80d8eea167fce5e0e8695c12)Raises $10M Seed Round
## Black Hole

[https://hellointerview.substack.com/p/the-7-must-know-patterns-for-system?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=b0f6dfbaa6abb10bd84fad7087094530dae91a52](https://hellointerview.substack.com/p/the-7-must-know-patterns-for-system?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=b0f6dfbaa6abb10bd84fad7087094530dae91a52)
[https://jadala-ajay16.medium.com/exploring-the-cloud-landscape-a-deep-dive-into-providers-and-service-models-c913c27b38d8?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=039472e2f1568be2c6907d762c1ae6e551ec70f9](https://jadala-ajay16.medium.com/exploring-the-cloud-landscape-a-deep-dive-into-providers-and-service-models-c913c27b38d8?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=039472e2f1568be2c6907d762c1ae6e551ec70f9)
[https://seattledataguy.substack.com/p/5-things-in-data-engineering-that?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=e36a2945dd0ca0b62601e959bd81370f392d459f](https://seattledataguy.substack.com/p/5-things-in-data-engineering-that?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=e36a2945dd0ca0b62601e959bd81370f392d459f)
[https://blog.algomaster.io/p/launching-premium-lld-resource?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=02042949f10cbc0448a1ad3e18d28ec216bdfa67](https://blog.algomaster.io/p/launching-premium-lld-resource?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxv&_bhlid=02042949f10cbc0448a1ad3e18d28ec216bdfa67)
## Cosmic Currents

[▶ Video](https://youtu.be/0k3o7VHjSn4)
## Double Star

---
### Open Source Repositories
> 📦 **dbeaver**
> Universal database tool and SQL client with AI integration.
> [https://github.com/dbeaver/dbeaver](https://github.com/dbeaver/dbeaver)*sql-client, java, open-source-alternative*
> 📦 **PixiEditor**
> Universal 2D editor for pixel art, painting, and more.
> [https://github.com/PixiEditor/PixiEditor](https://github.com/PixiEditor/PixiEditor)*2d-editor, JavaScript, open-source-alternative*
> 📦 **unsloth**
> Fine-tune LLMs 2x faster using 70% less VRAM.
> [https://github.com/unslothai/unsloth](https://github.com/unslothai/unsloth)*llm-finetuning, Python, ai-tool*
> 📦 **Freeter**
> Organize your computer workflow with this free, open-source project manager.
> [https://github.com/FreeterApp/Freeter](https://github.com/FreeterApp/Freeter)*project-manager, electron, open-source-alternative*
> 📦 **airi**
> Self-hosted AI companion with real-time voice chat and game integration.
> [https://github.com/moeru-ai/airi](https://github.com/moeru-ai/airi)*ai-assistant, Rust, self-hosted*
> 📦 **FreeDomain**
> Free domain names for everyone, no strings attached.
> [https://github.com/DigitalPlatDev/FreeDomain](https://github.com/DigitalPlatDev/FreeDomain)*domain-registration, dns, open-source-alternative*
> 📦 **mangle**
> Extend Datalog with aggregation, function calls, and optional type-checking for deductive database programming.
> [https://github.com/google/mangle](https://github.com/google/mangle)*deductive-database, datalog, data-integration*
> 📦 **system_prompts_leaks**
> Leaked system prompts from popular chatbots like ChatGPT, Claude, and Gemini.
> [https://github.com/asgeirtj/system_prompts_leaks](https://github.com/asgeirtj/system_prompts_leaks)*prompt-collection, chatbots, ai-assistant*
> 📦 **verifiers**
> Modular components for building RL environments and training LLM agents.
> [https://github.com/willccbb/verifiers](https://github.com/willccbb/verifiers)*rl-environment, Python, ai-assistant*
## Open Source Analysis

[https://opensourcedaily.blog/investbrain-opensource-investment-tracker-empowering-you-with-aidriven-insights](https://opensourcedaily.blog/investbrain-opensource-investment-tracker-empowering-you-with-aidriven-insights)
## Galactic Meme

---

## Celstial Quotes

---
> “The mobile phone acts as a cursor to connect the digital and physical.”― **Marissa Mayer**
## Stellar Prompts

---
**A Debug Mode for Your Behavioral Patterns**
```javascript
Hello, I want to understand and evaluate my potential toxic behaviors in relationships. I'd like you to assist me in this process. Please follow the steps below in order:
1. Present me with a statement describing a common behavior in relationships that is based on a cognitive distortion or emotional manipulation.
2. Ask me to rate how much I agree with the statement on a scale of 1 to 5. The rating scale should be as follows:
* **1:** Strongly Disagree
* **2:** Disagree
* **3:** Neutral / Sometimes Agree
* **4:** Agree
* **5:** Strongly Agree
3. After I provide my rating, move on to the next statement. Ask me a total of 5 different behavioral statements in this manner.
4. Once you have received all 5 of my answers, provide a general analysis. This analysis must include:
* A brief comment on my potential toxicity level (e.g., low, moderate, high) based on my total score.
* An identification of the dominant toxic tendency (e.g., controlling behavior, overgeneralization, passive-aggressiveness, etc.) underlying the statement I rated the highest.
* Finally, offer one short, concrete, and actionable suggestion to help me transform this dominant tendency.
```
---
## Grafana Backup Tool
Author: Serdarcan Büyükdereli
Date: 2025-08-22
Category: DevOps Blog
URL: https://theinfinity.dev/articles/grafana-backup-tool
This will be a document about how to back up Grafana dashboards and the data sources within them.
[https://github.com/ysde/grafana-backup-tool](https://github.com/ysde/grafana-backup-tool)
Environments within the project where backups will be taken:
1. Docker
2. Kubernetes Cronjobs
## **Docker**
```bash
docker run --user $(id -u):$(id -g) --rm --name grafana-backup-tool \
-e GRAFANA_URL=https://dashboards.serdarcanb.com \
-e GRAFANA_TOKEN='glsa_REDACTED_ROTATE_THIS_TOKEN' \
-e GRAFANA_ADMIN_ACCOUNT=admin \
-e GRAFANA_ADMIN_PASSWORD='example123!' \
-e VERIFY_SSL=False \
-v /tmp/backup/:/opt/grafana-backup-tool/_OUTPUT_ \
ysde/docker-grafana-backup-tool
```
> GRAFANA_URL: grafana url (dashboards.serdarcanb.com)GRAFANA_TOKEN: In the Grafana User tab, create a service account and set it as an admin.GRAFANA_ADMIN_ACCOUNT: admin userGRAFANA_ADMIN_PASSWORD: admin passwordVERIFY_SSL: We select False because we are not using SSL.
It also saves the backup as a tar.gz file in the /tmp/backup directory.
### **Restore**
Before testing the restore, I create a Grafana container using Docker.
The Grafana version you backed up must be the same as the version you are restoring to, or you may encounter unexpected issues (the restore might not complete successfully).
```bash
docker run -d --name=grafana -p 3000:3000 grafana/grafana
```
After creating the container, you need to log in as an admin and create a service account on the User page.
```bash
docker run --user $(id -u):$(id -g) --rm --name grafana-backup-tool \
-e GRAFANA_TOKEN=glsa_REDACTED_ROTATE_THIS_TOKEN \
-e GRAFANA_URL=http://192.168.60.45:3000 \
-e GRAFANA_ADMIN_ACCOUNT=admin \
-e GRAFANA_ADMIN_PASSWORD=admin \
-e VERIFY_SSL=False \
-e RESTORE="true" \
-e ARCHIVE_FILE=dashboard.tar.gz \
-v /root:/opt/grafana-backup-tool/_OUTPUT_ \
ysde/docker-grafana-backup-tool
```
After creating the service account, add the `RESTORE` and `ARCHIVE_FILE` environment variables.
After the restore, you can easily check the **Dashboard**, **Datasource**, **User**, and **Alerts**.
---
## **Kubernetes**
### **Backup**
In a Kubernetes environment, we use a Cronjob to manage this setup. You can also send backups to **AWS** and **GCLOUD** buckets in the same way. You can do this by defining it as an ENV variable.
[**https://github.com/ysde/grafana-backup-tool/blob/master/examples/grafana-backup-k8s-cronjob.yaml**](https://github.com/ysde/grafana-backup-tool/blob/master/examples/grafana-backup-k8s-cronjob.yaml)
I created a special Dockerfile to send notifications and backups to GitLab and Nexus.
```dockerfile
FROM ysde/docker-grafana-backup-tool:1.4.2
USER root
RUN apk --no-cache add curl gitlab-release-cli git
WORKDIR /opt/grafana-backup-tool
COPY script.sh .
RUN chmod +x /opt/grafana-backup-tool/script.sh
RUN chown -R 1337:1337 /opt/grafana-backup-tool
CMD sh -c 'if [ "$RESTORE" = true ]; then if [ ! -z "$AWS_S3_BUCKET_NAME" ] || [ ! -z "$AZURE_STORAGE_CONTAINER_NAME" ] || [ ! -z "$GCS_BUCKET_NAME" ]; then grafana-backup restore $ARCHIVE_FILE; else grafana-backup restore _OUTPUT_/$ARCHIVE_FILE; fi else grafana-backup save && /opt/grafana-backup-tool/script.sh ; fi'
```
```bash
#!/bin/bash
current_date=$(date +"%d.%m.%Y")
mv /opt/grafana-backup-tool/_OUTPUT_/*.tar.gz /opt/grafana-backup-tool/_OUTPUT_/"$PROJECT-$current_date.tar.gz"
curl --fail -u test:test --upload-file /opt/grafana-backup-tool/_OUTPUT_/"$PROJECT-$current_date.tar.gz" "https://nexus.serdarcanb.com/repository/restapi/grafana-backup/${PROJECT}-${current_date}.tar.gz"
MESSAGE='{"text":"✅ *'$PROJECT' Grafana backup completed successfully!* \n\n📂 Nexus link: '$GRAFANA_BACKUP_LINK'\n\n🔗 Commit link: '$COMMIT_LINK'"}'
curl -X POST -H 'Content-type: application/json' --data "$MESSAGE" $SLACK_WEBHOOK_URL
```
It sends a notification to my Slack channel. You can schedule backups daily, weekly, or monthly using a cron job.
### **Restore**
You can perform the restore process entirely using Docker, just like the backup.
Thank you for reading.
---
## The Infinity Tech XXIV
Author: Infinity Team
Date: 2025-08-18
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxiv
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **1 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹How Does SSO Work?
🔹Grok 4 now free for all users, but here’s a catch: How Elon Musk’s xAI tackles GPT-5 threat
🔹 Perplexity offers to buy Google Chrome for $34.5 billion
🔹Infinity Loop Secures $5M Seed Round
## Tech Orbit

---
### **Tech News**
🔹[Life-like robots](https://www.bbc.com/news/articles/cgm2jed7xvyo?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=335d056b1549ae79f998fd38791949bf229ed8dd) for sale to the public as China opens new store
🔹[FDA grants first](https://www.fda.gov/drugs/news-events-human-drugs/fda-approves-first-interchangeable-biosimilars-eylea-treat-macular-degeneration-and-other-eye?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=a05d79406191e4f579786c77fad2f6e0d850e4e9) US approval for decades-old eye drug
🔹[Perplexity offers](https://www.theverge.com/news/758218/perplexity-google-chrome-bid-unsolicited-offer?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=c5454951eba74ec502b00d959bc67346f305ea65)to buy Google Chrome for $34.5 billion
🔹[Grok 4 now free for all users](https://www.financialexpress.com/life/technology-grok-4-now-free-for-all-users-but-heres-a-catch-how-elon-musks-xai-tackles-gpt-5-threat-3944036/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=92b1f02d85b9a5355287ad22378502012768c770), but here’s a catch: How Elon Musk’s xAI tackles GPT-5 threat
### **Tech Articles**
🔹[Ollama Embedded Models](https://collabnix.com/ollama-embedded-models-the-complete-technical-guide-to-local-ai-embeddings-in-2025/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=7da36821ff07b406bfa4363bd6b72345b2f25d79): The Complete Technical Guide to Local AI Embeddings in 2025
🔹[Must-Know Event-Driven](https://newsletter.systemdesigncodex.com/p/must-know-event-driven-architectural?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=b0becaaf995bb1250b93680214c96ef648876ddc) Architectural Patterns
🔹[Mastering n8n from Scratch](https://medium.com/data-science-collective/mastering-n8n-from-scratch-a-step-by-step-guide-for-beginners-its-easier-than-you-think-2d7ca5d47277?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=8be85e5d659cc5c329915f55bfa14354569502ab) — A Step-by-Step Guide for Beginners (It’s Easier Than You Think)
🔹[How Does](https://blog.bytebytego.com/p/ep176-how-does-sso-work?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=a4a11f5e7718163c492a84d0397c98eefcdc4330) SSO Work?
🔹[We're going High Availability](https://scotthelme.co.uk/were-going-high-availability-with-redis-sentinel?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=c6f98ecee4d1cbcc43bb0788b7b36f18c4aece23) with Redis Sentinel!
## Asteroid Ventures

---
### **Companies News**
🔹[Infinity Loop](https://www.globenewswire.com/news-release/2025/08/14/3133301/0/en/Infinity-Loop-Raises-5M-Empowers-Enterprises-to-Save-Millions-on-Vendor-Contracts.html?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=a835e652e56a34d63f7fa45e1963c86b4f0fb7ed)Secures $5M Seed Round
🔹[CourseRev.ai](https://courserevs-newsletter.beehiiv.com/p/courserev-ai-secures-strategic-investment-from-the-walden-golf-group-to-accelerate-growth?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=442da3f35fa0f10cda45f7392699103a7d05f144)Secures Strategic Investment
🔹[Cache](https://usecache.com/companion/announcing-our-series-a-to-make-sophisticated-investing-more-accessible?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=7c8a340a8ff08cc83797083e8407c5e27934f523)Scores $12.5M Series A Round
🔹[Topline Pro](https://www.toplinepro.com/b?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=efb432cf49915e5346246ea5a5575ffa8db26ee8)[Raises $27M Series B Financing](https://www.infoq.com/articles/infusing-ai-java/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=d6372927131a42070429195b18ca50b9135cb075)
## Black Hole

[https://www.infoq.com/articles/infusing-ai-java/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=daa8369f6c1f335f8222a7918ae523b07bfebf59](https://www.infoq.com/articles/infusing-ai-java/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=daa8369f6c1f335f8222a7918ae523b07bfebf59)
[https://instavm.io/blog/building-my-offline-ai-workspace?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=da78895ce190ee68e89f126ab4a2efd6cdd00e40](https://instavm.io/blog/building-my-offline-ai-workspace?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=da78895ce190ee68e89f126ab4a2efd6cdd00e40)
[https://openai.com/gpt-5/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=02d2bca2dd45dceceb6a84dcdd1047319dabb23c](https://openai.com/gpt-5/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=02d2bca2dd45dceceb6a84dcdd1047319dabb23c)
[https://colton.dev/blog/curing-your-ai-10x-engineer-imposter-syndrome/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=08b2135567ccab718951d5cc7ce6bd7202545df8](https://colton.dev/blog/curing-your-ai-10x-engineer-imposter-syndrome/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=08b2135567ccab718951d5cc7ce6bd7202545df8)
## Cosmic Currents

[▶ Video](https://youtu.be/0k3o7VHjSn4)
[▶ Video](https://youtu.be/2of-FOou2Lk)
## Double Star

---
### Open Source Repositories
> 📦 **gpt4all**
> Run local LLMs on any device; open-source and commercially usable.
> [https://github.com/nomic-ai/gpt4all](https://github.com/nomic-ai/gpt4all)*LLM, Python, open-source-alternative*
> 📦 **notebooks**
> 100+ fine-tuned large language model (LLM) notebooks for Google Colab, Kaggle, and more.
> [https://github.com/unslothai/notebooks](https://github.com/unslothai/notebooks)*llm-fine-tuning, google-colab, AI*
> 📦 **tirreno**
> Open-source security analytics for proactive threat defense.
> [https://github.com/tirrenotechnologies/tirreno](https://github.com/tirrenotechnologies/tirreno)*security-analytics, php, open-source-alternative*
> 📦 **clamav**
> Open-source antivirus engine detecting malware and viruses.
> [https://github.com/Cisco-Talos/clamav](https://github.com/Cisco-Talos/clamav)*antivirus, c, open-source-alternative*
> 📦 **open-swe**
> Autonomous coding agent that plans and executes code changes across entire repositories.
> [https://github.com/langchain-ai/open-swe](https://github.com/langchain-ai/open-swe)*coding-agent, langchain, ai-assistant*
> 📦 **czkawka**
> Speedy app to find duplicates, empty folders, and similar images.
> [https://github.com/qarmin/czkawka](https://github.com/qarmin/czkawka)*file-management-tool, Rust, devops-tool*
> 📦 **Archon**
> Knowledge and task management backbone for AI coding assistants.
> [https://github.com/coleam00/Archon](https://github.com/coleam00/Archon)*ai-assistant, Python, devops-tool*
> 📦 **parlant**
> LLM agents built for real-world use, deployed in minutes.
> [https://github.com/emcie-co/parlant](https://github.com/emcie-co/parlant)*llm-agent, Python, ai-assistant*
## Open Source Analysis

---
[https://opensourcedaily.blog/frigate-opensource-nvr-with-realtime-ai-object-detection](https://opensourcedaily.blog/frigate-opensource-nvr-with-realtime-ai-object-detection)
[https://opensourcedaily.blog/oneuptime-the-opensource-allinone-monitoring-alerting-incidentresponse-platform](https://opensourcedaily.blog/oneuptime-the-opensource-allinone-monitoring-alerting-incidentresponse-platform)
## Galactic Meme


## Celestial Quotes

---
> “The point is not how we use a tool, but how it uses us.”― **Nick Joaquín,** [**Culture and History**](https://www.goodreads.com/work/quotes/1422932?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiv&_bhlid=cea0635232807e7b057bb3e3f1c70a3a6bfe95d6)
## Stellar Prompts

---
**AI Magic: Turning a Logo into 3D Art**
Want to transform a flat logo into a breathtaking, photorealistic 3D object? All you need is the right AI prompt, crafted with specific details. Here's the powerful prompt that brought 'The Infinity' concept to life:
```javascript
**Subject:** A 3D inflatable object designed as the infinity symbol (∞) for 'The Infinity'.
**Style:** Photorealistic, hyper-detailed, plush and puffy aesthetic.
**Material & Texture:** Premium matte silver fabric with a subtle metallic sheen, realistic creases, and fine stitching.
**Environment:** A high-end, minimalist living room on a dark charcoal couch.
**Color Palette:** Monochromatic, with a light silver object and a gray/white environment.
**Lighting:** Soft, diffused natural light from a large window.
**Composition & Angle:** 45-degree angle, medium shot, with shallow depth of field (bokeh).
**Quality:** 8K resolution, cinematic quality, professional product photography.
```
The result? A stunning visual that feels real enough to touch. The secret to unlocking AI's creative potential lies in being this specific. Try it with your own logo!

---
## The Infinity Tech XXIII
Author: Infinity Team
Date: 2025-08-11
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxiii
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **21 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹GPT-5 Is Coming: Are You Ready for the Paradigm Shift?
🔹OpenAI Just Challenged Everyone: A Look Inside Their New Open Models.
🔹 The "Silent" Update: Why Claude 4.1 Might Be the Most Important Release of the Year.
🔹Kubernetes 1.34 Sneak Peek: The Killer Features You Need to Know About.
🔹Escape Vendor Lock-In: A Look at the Self-Hosted Cloud Platform Taking on AWS.
## Tech Orbit

---
### **Tech News**
🔹[Open Models](https://openai.com/open-models/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=ae6f4fb7be6b2128790e119487631180ccb079aa)By OpenAI
🔹[Introducing](https://openai.com/index/introducing-gpt-5/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=2626f40ffba2febc1a6c8d899f08828d922ce330)GPT-5
🔹[Elon Musk’s Grok](https://www.independent.co.uk/tech/ai-chess-grok-openai-altman-musk-b2803801.html?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=2c65211f40cb38614c67d25d9e33e1af4589f193) loses to Sam Altman’s OpenAI in AI chess tournament
🔹[Tesla to streamline](https://www.reuters.com/business/autos-transportation/tesla-streamline-its-ai-chip-design-work-musk-says-2025-08-07/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=b42f8baadb4bb8121e9c8e0dec673bd5fcb9b372) its AI chip design work, Musk says
### **Tech Articles**
🔹[GPT-5: Key characteristics, pricing and model card](https://simonwillison.net/2025/Aug/7/gpt-5/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=fe9e9d6fbe3a02e49e3ffc0c05772e8ca1df7590)
🔹[Maximizing Business Value Through Strategic Cloud Optimization](https://aws.amazon.com/blogs/architecture/maximizing-business-value-through-strategic-cloud-optimization/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=337f9fc2d0777c24fa8004a454897aec015e8e2d)
🔹[Claude Opus 4.1](https://www.anthropic.com/news/claude-opus-4-1?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=4d9675649fd4ea175bbe4b935ebe43c41d8e898a)
🔹[Kubernetes v1.34 Sneak Peek](https://kubernetes.io/blog/2025/07/28/kubernetes-v1-34-sneak-peek/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=184255cf4246a9f75182ad746c9d1cf7242d323f)
🔹[How to tell when AI is lying to you](https://read.highgrowthengineer.com/p/how-to-tell-when-ai-is-lying-to-you?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=4936ee7821785d9c41b96e6b8d2e17242a32cf82)
## Asteroid Ventures

---
### **Companies News**
🔹[Perle](https://www.perle.ai/resources/perle-secures-9-million-seed-round-led-by-framework-ventures-to-launch-an-ai-data-training-platform-powered-by-web3?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=79a7bcf4e6c08c259175b7b95e348f4f606e79d5)Scores $9M Seed Funding Round
🔹[DISA Technologies](https://finance.yahoo.com/news/disa-technologies-closes-oversubscribed-30m-171400160.html?guccounter=1&guce_referrer=aHR0cHM6Ly93d3cuZ29vZ2xlLmNvbS8&guce_referrer_sig=AQAAAKj1RHrUE5ZaFsxQ1RrEbWyqr5f0g3bv1mbWDgLoSNydGSioz6D_nnfvJXcFddveSq4xHpXQ2HkIhvUcwweq1lIVtZfYvw7-sJdO1kUITZ84cEXV3yspD6qq2AQY81ekqBMgR3-0eBDWwjUr24hrU82RT0kZckLlI8oWuz9L2m9-&utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=6533f72f45dfe5c4af67c0197bf00f9f32d957c1)Completes Series A2 Round
🔹[FORT Robotics](https://www.fortrobotics.com/news/fort-secures-additional-18.9m-in-series-b-funding?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=7d7289a94e13927900545bf5e521fc75d08c6ac8)Closes $18.9M Series B Round
🔹[Capacity](https://capacity.com/blog/capacity-acquires-call-criteria-and-verbio-technologies/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxiii&_bhlid=e2a71d6baf32575c96eb1f70c40d0f85c9af8b6d)Completes $92M Financing Round
## Black Hole

[https://benholmen.com/blog/kilopixel/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii](https://benholmen.com/blog/kilopixel/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii)
[https://www.historicaltechtree.com/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii](https://www.historicaltechtree.com/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii)
[https://github.blog/ai-and-ml/generative-ai/a-practical-guide-on-how-to-use-the-github-mcp-server/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii](https://github.blog/ai-and-ml/generative-ai/a-practical-guide-on-how-to-use-the-github-mcp-server/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii)
## Cosmic Currents

[▶ Video](https://youtu.be/0k3o7VHjSn4)
## Double Star

---
### Open Source Repositories
> 📦 **frigate**
> AI-powered NVR with real-time object detection for IP cameras.
> [https://github.com/blakeblackshear/frigate](https://github.com/blakeblackshear/frigate)*nvr, Python, self-hosted*
> 📦 **lvgl**
> Create stunning UIs for embedded systems with this lightweight graphics library.
> [https://github.com/lvgl/lvgl](https://github.com/lvgl/lvgl)*graphics-library, c, embedded-systems*
> 📦 **vllm**
> High-throughput, memory-efficient inference and serving engine for LLMs.
> [https://github.com/vllm-project/vllm](https://github.com/vllm-project/vllm)*llm-inference-engine, Python, ai-assistant*
> 📦 **vibe-kanban**
> Kanban board for managing AI coding agents like Claude, Codex, and Gemini.
> [https://github.com/BloopAI/vibe-kanban](https://github.com/BloopAI/vibe-kanban)*kanban-board, ai-agent-management, devops-tool*
> 📦 **run-gemini-cli**
> GitHub Action for integrating Gemini CLI into your workflow.
> [https://github.com/google-github-actions/run-gemini-cli](https://github.com/google-github-actions/run-gemini-cli)*github-action, gemini, devops-tool*
> 📦 **ubicloud**
> Open-source alternative to AWS, offering compute, storage, database, and AI services.
> [https://github.com/ubicloud/ubicloud](https://github.com/ubicloud/ubicloud)*cloud-platform, kubernetes, open-source-alternative*
> 📦 **umami**
> Privacy-focused Google Analytics alternative.
> [https://github.com/umami-software/umami](https://github.com/umami-software/umami)*web-analytics, JavaScript, open-source-alternative*
> 📦 **Folo**
> Follow all your feeds in one place.
> [https://github.com/RSSNext/Folo](https://github.com/RSSNext/Folo)*feed-aggregator, JavaScript, self-hosted*
## Open Source Analysis

[https://opensourcedaily.blog/rocket-chat-team-collaboration-with-secure-communications?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii](https://opensourcedaily.blog/rocket-chat-team-collaboration-with-secure-communications?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxiii)
[https://opensourcedaily.blog/rallly-opensource-scheduling-polls-that-end-email-backandforth](https://opensourcedaily.blog/rallly-opensource-scheduling-polls-that-end-email-backandforth)
## Galactic Meme


## Celestial Quotes

> “Progress is made by lazy men looking for easier ways to do things.” —**Robert A. Heinlein**
## Stellar Prompts

---
### **🧸✨ From Emojis to Plush Toys: Infinite Creativity! 🚀**
**Prompt:**
Copy the text below and paste it into your image generation platform, replacing `[[description]]` with the emoji you want to create:
```bash
"Generate a hyper-realistic 3D render of a [[description]] as a floating head with plush toy aesthetics. The design should emphasize ultra-soft, long fur, playful cuteness, and a childlike charm. Use a straight-on camera angle with soft, diffused lighting to create a warm and inviting glow. Keep the background pure white for a clean, modern look. The color palette should be vibrant yet soothing, enhancing the toy-like appeal. Style: Ultra-detailed, whimsical, and hyper-cute, blending realism with a soft, plush texture for maximum visual impact."
```
**How to Use?**
- ➡️ Replace [[description]] in the prompt with your chosen emoji (e.g., 🐱, 🐻, 🐼, 😂, ❤️).
- ✂️ Paste the final text into your favorite image generation tool.
- 🎨 Start the render!
**Tips:**
- Popular choices: 🐱, 🐻, 🦊, 🐼, 🐶
- Experiment with different emojis! 🌈
- The results will be ultra-soft and adorable! 🥰
**The Infinity Blog**: Making the digital world a cuter place! ✨
Example 👉 😅

---
## The Infinity Tech XXII
Author: Infinity Team
Date: 2025-08-04
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxii
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **3 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹Microsoft's new tool lets you build apps without coding. Should developers be worried?
🔹OpenAI launches ‘Study Mode’ in ChatGPT
🔹 Kimi-k2 Free API Key
🔹Introducing GLM-4.5: A New Leap in AI Development
## Tech Orbit

---
### **Tech News**
🔹[Microsoft's new tool lets you build apps without coding. Should developers be worried?](https://www.businesstoday.in/technology/news/story/microsofts-new-tool-lets-you-build-apps-without-coding-should-developers-be-worried-486248-2025-07-25?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=4fe7775f0ad56402dd9428927f588562def38141)
🔹[Google AI tool helps historians restore ancient Roman inscriptions](https://www.theguardian.com/science/2025/jul/23/google-ai-tool-roman-inscriptions-aeneas?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=aaf7a8d829fe19838c0058923059f4b4d1b529c1)
🔹[Mark Zuckerberg’s new goal for Meta: build artificial general intelligence](https://www.theverge.com/ai-artificial-intelligence/715951/mark-zuckerberg-meta-ai-superintelligence-scale-openai-letter?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=35c440dc5955d6069caf33b38cbefc5ad212fbab)
🔹[OpenAI launches ‘Study Mode’ in ChatGPT](https://techcrunch.com/2025/07/29/openai-launches-study-mode-in-chatgpt/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=bcd4b1e3deec795f223631cbeed214398ddeb6e1)
🔹[Introducing GLM-4.5: A New Leap in AI Development](https://z.ai/blog/glm-4.5?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=3945200f9853caadadfa884dd055fe6435ac7cec)
### **Tech Articles**
🔹[Kimi-k2](https://medium.com/data-science-in-your-pocket/kimi-k2-free-api-key-fb4a28900d4b?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=101dc17613a1c5975093f6821ecc6ed7c6ab1770)Free API Key
🔹[Introduction to](https://www.cncf.io/blog/2025/07/29/introduction-to-policy-as-code?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=9285fb3a047a0a5b7104d3cd900e757a055b82f5)Policy as Code
🔹[Top 5 Udemy Courses to Learn](https://medium.com/javarevisited/top-5-udemy-courses-to-learn-claude-code-and-claude-ai-in-2025-7a0695c991af?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=cfda58211bdf624dc06309dacd1c436bad5ee6a0) Claude Code and Claude AI in 2025
🔹[The Full MLOps](https://blog.dailydoseofds.com/p/the-full-mlopsllmops-blueprint?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=4e06ce03ca5f65945262e37535755328bb1df72d)/LLMOps Blueprint
🔹[Idempotency](https://www.systemdesignbutsimple.com/p/idempotency-in-1-diagram-and-144-words?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=def629035546a187457be0a9df6d44800296eef0) in 1 diagram and 144 words
## Asteroid Ventures

---
### **Companies News**
🔹[Wallarm](https://www.wallarm.com/press-releases/wallarm-announces-55-million-in-series-c-to-transform-api-security-for-the-ai-era?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=1fc63d2809ec34652ee84b7595bdc049cc8fea09)Raises $55M Series C Round
🔹[SiMa.ai](https://sima.ai/press-release/sima-ai-raises-85m-to-scale-physical-ai-bringing-total-funding-to-355m/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=13f604f60aedb8a6479848f54b40dd64ba63b92a)Secures $85M
🔹[SAFE](https://safe.security/resources/press-release/safe-series-c-ctem-launch/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=6024c72c889d0865fed868b5171382ae7f6730fa)Scoops Up $70M Series C Round
🔹[Noma Security](https://noma.security/blog/noma-security-raises-100m-to-drive-adoption-of-ai-agent-security/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=4d1a03d7fb913880f3c51fd570da720c27097878)Raises $100M Series B
🔹[Knit](https://goknit.com/resources/blog/knit-raises-16-1m-series-a-to-redefine-enterprise-research-with-human-ai-insights?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=2862cf7aa865e40ffc8d14f55dd0053f0f6112aa)Pulls In $16.1M Series A Round
## Black Hole

[https://simonwillison.net/2025/Jul/29/space-invaders/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii](https://simonwillison.net/2025/Jul/29/space-invaders/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii)
[https://wassimulator.com/blog/programming/programming_vehicles_in_games.html?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii](https://wassimulator.com/blog/programming/programming_vehicles_in_games.html?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii)
[https://themaister.net/blog/2025/06/16/i-designed-my-own-ridiculously-fast-game-streaming-video-codec-pyrowave/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii](https://themaister.net/blog/2025/06/16/i-designed-my-own-ridiculously-fast-game-streaming-video-codec-pyrowave/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii)
## Cosmic Currents

[▶ Video](https://youtu.be/FWcwtI2eQFE)
### Open Source Repositories
---
> 📦 **crush**
> Glamorous AI coding agent for your terminal.
> [https://github.com/charmbracelet/crush](https://github.com/charmbracelet/crush)*ai-assistant, Go, devops-tool*
> 📦 **tldr**
> Collaborative cheatsheets for console commands.
> [https://github.com/tldr-pages/tldr](https://github.com/tldr-pages/tldr)*cheat-sheets, CLI, devops-tool*
> 📦 **500-AI-Agents-Projects**
> 500+ AI agent projects and use cases across various industries.
> [https://github.com/ashishpatel26/500-AI-Agents-Projects](https://github.com/ashishpatel26/500-AI-Agents-Projects)*ai-agent-applications, open-source, ai-assistant*
> 📦 **focalboard**
> Self-hosted alternative to Trello, Notion, and Asana.
> [https://github.com/mattermost-community/focalboard](https://github.com/mattermost-community/focalboard)*project-management-tool, JavaScript, open-source-alternative*
> 📦 **kubernetes-goat**
> Vulnerable Kubernetes cluster for security training.
> [https://github.com/madhuakula/kubernetes-goat](https://github.com/madhuakula/kubernetes-goat)*kubernetes-security-tool, kubernetes, devops-tool*
> 📦 **dagger**
> Composable workflow runtime for AI agents and CI/CD.
> [https://github.com/dagger/dagger](https://github.com/dagger/dagger)*ci-cd-platform, Go, devops-tool*
> 📦 **WrenAI**
> GenBI agent: Natural language database queries, SQL generation, charting, and AI insights in seconds.
> [https://github.com/Canner/WrenAI](https://github.com/Canner/WrenAI)*Text-to-SQL, sql, ai-assistant*
> 📦 **dyad**
> Build AI apps locally, for free.
> [https://github.com/dyad-sh/dyad](https://github.com/dyad-sh/dyad)*ai-app-builder, JavaScript, open-source-alternative*
> 📦 **motia**
> Unified backend framework for APIs, background jobs, workflows, and AI agents.
> [https://github.com/MotiaDev/motia](https://github.com/MotiaDev/motia)*backend-framework, JavaScript, devops-tool*
> 📦 **burrito**
> Argo CD for Terraform: Manage your Terraform infrastructure with a Kubernetes operator.
> [https://github.com/padok-team/burrito](https://github.com/padok-team/burrito)*kubernetes-operator, terraform, devops-tool*
## Open Source Analysis

[https://opensourcedaily.blog/automatisch-the-open-source-zapier-alternative?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii](https://opensourcedaily.blog/automatisch-the-open-source-zapier-alternative?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii)
[https://opensourcedaily.blog/nhost-open-source-alternative-to-firebase-and-supabase-wit?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii](https://opensourcedaily.blog/nhost-open-source-alternative-to-firebase-and-supabase-wit?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxii)
## Galactic Meme


## Celestial Quotes

> “It's supposed to be automatic, but actually you have to push this button. ”― **John Brunner,** [**Stand on Zanzibar**](https://www.goodreads.com/work/quotes/2184253?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxii&_bhlid=89ac6b7215f0ec05c0dfe73a55b700adcfec1376)
## Stellar Prompts

---
### How to Write an Effective Prompt for AI
Producing a successful AI image comes down to giving the model clear and layered instructions. A good prompt is like a detailed recipe that guides the AI like an artist, leaving no room for ambiguity.
Here's the secret behind that successful prompt combining a logo and a leaf texture:
- **Clear Objective:** The prompt states exactly what it wants from the start: "A 3D render of the logo."
- **Material and Texture Definition:** Instead of just saying "make it out of a leaf," it brings the material to life with physical details like "soft, organic leaf material, realistic veins, surface depth, and matte gloss."
- **Artistic Direction:** It sets the aesthetic quality and atmosphere with phrases like "Cinema 4D style" and "premium, editorial look." The "high-contrast lighting" command enhances the texture's details.
- **Technical Rules:** It specifies that the logo's original shape must be preserved and standardizes the output with technical parameters like "8K resolution, white background."
In short, this prompt answers the questions of what, why, how, and in what format, allowing the AI to use its creative potential in the most accurate way.
### Custom Prompts for "The Infinity"
Here are two different concepts tailored to the themes of eternity and technology suggested by the name "The Infinity":
**1. Cosmic Concept (Universal & Ethereal)**
```bash
Create a 3D-rendered digital image of "The Infinity" logo. Render it as if forged from a living cosmic nebula. The material should feature deep blues and violets, with glowing energy filaments and minuscule, glittering stars embedded within. The surface must have a translucent, ethereal quality. Use dramatic, volumetric lighting to create a sense of awe. The background should be near-black deep space. The result must be ultra-realistic, evoking endless possibility.
```
```bash
Style: Hyper-realistic 3D, Cinematic Texture: Luminous cosmic nebula Lighting: Volumetric, dramatic Background: Deep space Format: Widescreen (16:9) Quality: 8K Render
```
**2. Tech Concept (Minimalist & Premium)**
```bash
Generate a hyper-realistic 3D image of "The Infinity" logo. Render it from polished, liquid chromium with a flawless, mirror-like finish. Subtle, cyan-colored energy conduits should pulse with a soft light just beneath the surface. The aesthetic should be minimalist and high-tech. Use soft studio lighting to emphasize the logo's sleek curves and reflections against a clean, dark gray gradient background. The final image must look like a sophisticated, futuristic product shot.
```
```bash
Style: Hyper-realistic 3D, Minimalist Tech Texture: Polished liquid chromium, internal light veins Lighting: Soft studio, focused on reflections Background: Dark gray gradient Format: Square (1:1) Quality: 8K Render
```
---
## The Infinity Tech XXI
Author: Infinity Team
Date: 2025-07-27
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xxi
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **2 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹[Nubank's AI Secret: How They Spy on 100 MILLION Customers!](https://blog.bytebytego.com/p/how-nubank-uses-ai-models-to-analyze?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=51468c1ce528fd807db7a83e4070e842bdbb835f)
🔹[Qwen3: Think Deeper, Act Faster](https://qwenlm.github.io/blog/qwen3/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=ba3cb4ca76e3b59dc5e365a4ca71750ceec46c57)
🔹[Stop Wasting Time on Infrastructure! Build Your Self-Service Portal NOW!](https://spacelift.io/blog/gitops-kubernetes?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=ed51d2b265a1583c82eb2baa2c543c99158c3de8)
🔹[This Robot Can Do EVERYTHING! (And It Only Costs $16,000!)](https://www.unitree.com/g1?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=e0b18be766ad564018fcccc69f080d67155778f7)
🔹[The Next Evolution of AI: OpenAI Introduces the ChatGPT Agent](https://help.openai.com/en/articles/11752874-chatgpt-agent?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=fc4b7728c71265fc9f439e1af1e4f47ef2c38d6f)
## Tech Orbit

---
### **Tech News**
🔹[The Next Evolution of AI: OpenAI Introduces the ChatGPT Agent](https://help.openai.com/en/articles/11752874-chatgpt-agent?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=ad957ec9e1689e2928352bb58de1f960d488572b)
🔹[This Robot Can Do EVERYTHING! (And It Only Costs $16,000!)](https://www.unitree.com/g1?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=ab6b7321a3623f5528ade9d5c3b9d0288d9fbcbf)
🔹[AI Just Got 1000x Smarter: Meet Qwen3, The Mind-Blowing New Language Model!](https://qwenlm.github.io/blog/qwen3/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=9fc9f3ea899dfd6791b2baedf5f6e2b0c5e96cdc)
🔹[Qwen3: Think Deeper, Act Faster](https://qwenlm.github.io/blog/qwen3/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=2f95dd0582273cc89df08b31790ec511c6e80c6f)
🔹[Google's SECRET AI App Lets You Build Mini-Apps With Just Words!](https://developers.googleblog.com/en/introducing-opal/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=190bef104dcda94ec4bc0ecb3a58e25cac871e5c)
### **Tech Articles**
🔹[Code Reviews: From Startup Nightmare to Scaling Success!](https://newsletter.systemdesign.one/p/how-to-do-code-review?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=db5275ee1c8d36748bd08f38eeed8bae3e3f7f4d)
🔹[Code Review HACKS: Slash Review Time & Bugs in HALF!](https://newsletter.francofernando.com/p/what-to-look-for-in-code-reviews?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=050b4a05abe66ccebefe8daaf0bf11d829f0a3ba)
🔹[STOP Wasting Time! Build ROCK-SOLID AI Agents with THIS ONE Weird Trick (DSPy)](https://www.firebird-technologies.com/p/building-production-ready-ai-agents?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=f4f8ba6723cd86d9e914f36b23be2ab5e1aa727b)
🔹[This Insane Browser Trick Uses YOUR FACE!](https://medium.com/@kenzic/real-time-face-tracking-in-the-browser-with-mediapipe-7c818c96b4ca?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=35c5d71259d70c30a0d365a32fd83a2eec13c094)
🔹[Nubank's AI Secret: How They Spy on 100 MILLION Customers!](https://blog.bytebytego.com/p/how-nubank-uses-ai-models-to-analyze?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=9495e38944cbc11d5ad74c7b1b67584e0d671521)
🔹[Substack Publishers REVEAL Their SHOCKING AI Secrets!](https://on.substack.com/p/the-substack-ai-report?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=6ade8e3502fbe0ab93985d1578eb7975970daf56)
🔹[Stop Wasting Time on Infrastructure! Build Your Self-Service Portal NOW!](https://spacelift.io/blog/gitops-kubernetes?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=a5a36c7a32e075af72f6f49ee1c555e4d442a561)
## Asteroid Ventures

---
### **Companies News**
🔹[Spear AI](https://spear.ai/newsroom/seed-funding?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=bafae9c296cbb2d9b238abb28baea2e07f7d32b2) Secures Seed Funding
🔹[Armada](https://www.armada.ai/blog/131M-strategic-funding-leviathan?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=5de240303c9dd1867255fa53d6d12a9fd7ba6f5e) Announces $131M Strategic Funding
🔹[Reka](https://reka.ai/news/reka-secures-110-million-to-accelerate-adoption-of-its-multimodal-ai-platforms?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=9c8d6515c309253eb03657081d98c96db6d2c2bd) Lands $110M Financing Round
🔹[LegalOn Technologies](https://www.legalontech.com/press-releases/%20legalon-closes-50-million-series-e-led-by-goldman-sachs?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=0165efd2cb31095fbd49d5e9352f19e495d83a1b) Receives $50M Series E
🔹[Xemelgo](https://blog.xemelgo.com/zebra-ventures-makes-strategic-investment-in-xemelgo-to-support-intelligent-automation?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=9c7cb3f4c911305e920b080b6521250b47d0c25a) Secures New Funding
## Black Hole

---
[https://www.anthropic.com/api/opengraph-illustration?name=Hand%20NodeSlide&backgroundColor=clay](https://www.anthropic.com/api/opengraph-illustration?name=Hand%20NodeSlide&backgroundColor=clay)
[https://calnewport.com/no-one-knows-anything-about-ai/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxi](https://calnewport.com/no-one-knows-anything-about-ai/?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxi)
[https://www.pathtostaff.com/p/work-life-balance-slows-careers-e9?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxi](https://www.pathtostaff.com/p/work-life-balance-slows-careers-e9?utm_source=www.theinfinity.dev&utm_medium=referral&utm_campaign=the-infinity-tech-xxi)
## Cosmic Currents

[▶ Video](https://youtu.be/E6BU6fMgojc)
## Open Source Analysis

[https://opensourcedaily.blog/kro-kubernetes-infrastructure-management/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=f6f05593da4880fcb30e44dcee5aa7e682d3ea81](https://opensourcedaily.blog/kro-kubernetes-infrastructure-management/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=f6f05593da4880fcb30e44dcee5aa7e682d3ea81)
[https://opensourcedaily.blog/tesseral-open-source-b2b-authentication/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=f1e0a85ccdb14e2a65df0d6c673f7379eb186f72](https://opensourcedaily.blog/tesseral-open-source-b2b-authentication/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xxi&_bhlid=f1e0a85ccdb14e2a65df0d6c673f7379eb186f72)
## Double Star

---
### Open Source Repositories
> 📦 **label-studio**
> Multi-type data labeling and annotation tool with standardized output.
> [https://github.com/HumanSignal/label-studio](https://github.com/HumanSignal/label-studio)*data-annotation-tool, Python, open-source-alternative*
> 📦 **BillionMail**
> Self-host your email server, newsletter, and email marketing campaigns.
> [https://github.com/aaPanel/BillionMail](https://github.com/aaPanel/BillionMail)*email-marketing, mailserver, self-hosted*
> 📦 **hrms**
> Open-source HR and payroll software for managing employee lifecycle and compensation.
> [https://github.com/frappe/hrms](https://github.com/frappe/hrms)*hr-management-system, Python, open-source-alternative*
> 📦 **flux2**
> GitOps-powered continuous delivery for Kubernetes.
> [https://github.com/fluxcd/flux2](https://github.com/fluxcd/flux2)*ci-cd-platform, kubernetes, devops-tool*
> 📦 **openspot-music-app**
> Free, open-source music streaming app with a high-fidelity listening experience.
> [https://github.com/BlackHatDevX/openspot-music-app](https://github.com/BlackHatDevX/openspot-music-app)*music-streaming-app, cross-platform, open-source-alternative*
> 📦 **Cloudreve**
> Self-hosted file management and sharing system with multi-cloud storage support.
> [https://github.com/cloudreve/Cloudreve](https://github.com/cloudreve/Cloudreve)*file-manager, Go, self-hosted*
> 📦 **neko**
> Self-hosted virtual browser using Docker and WebRTC for secure, private browsing.
> [https://github.com/m1k1o/neko](https://github.com/m1k1o/neko)*virtual-browser, docker, self-hosted*
> 📦 **keycloak**
> Open-source identity and access management for modern applications.
> [https://github.com/keycloak/keycloak](https://github.com/keycloak/keycloak)*identity-management, java, open-source-alternative*
> 📦 **litellm**
> Unified Python SDK and proxy server for accessing 100+ large language model APIs.
> [https://github.com/BerriAI/litellm](https://github.com/BerriAI/litellm)*llm-gateway, Python, ai-assistant*
> 📦 **infisical**
> Open-source platform for secrets, PKI, and SSH access.
> [https://github.com/Infisical/infisical](https://github.com/Infisical/infisical)*secrets-management, Go, self-hosted*
> 📦 **higgsfield**
> Fault-tolerant GPU orchestration and ML framework for training massive models.
> [https://github.com/higgsfield-ai/higgsfield](https://github.com/higgsfield-ai/higgsfield)*gpu-orchestration, Python, machine-learning*
## Galactic Meme


## Celestial Quotes

> “The real danger is not that computers will begin to think like men, but that men will begin to think like computers.” Sydney J. Harris
## Stellar Prompts

---
**Transform Images into LEGO Masterpieces with This AI Prompt**
Want to turn any concept or photo into a stunning, hyper-realistic LEGO model? A well-crafted AI prompt is the key. This guide provides the exact prompt and a brief explanation of why it delivers professional, collector-quality results.
Copy and paste the following into your AI image generator:
```bash
"Transform the uploaded image into an extremely detailed, hyper-realistic LEGO toy model. Ensure the design captures intricate features while maintaining the iconic LEGO style. Use brand-accurate colors compatible with official LEGO parts for authenticity. Place the toy on a neutral background with soft, diffuse studio lighting to highlight textures and contours, enhancing a high-end, designer toy aesthetic. The final image should evoke a polished, professional look, suitable for showcasing collectible LEGO artwork."
```
This prompt is effective because it gives the AI specific, layered instructions:
- **It Demands Authenticity:**By requesting the iconic LEGO style, official parts, and brand-accurate colors, it ensures the final model looks like a genuine product.
- **It Directs the Presentation:**The call for "soft, diffuse studio lighting" and a "neutral background" is a professional photography command that creates a high-end, collectible feel.
- **It Sets a Clear Goal:**The prompt clearly defines the desired outcome: a "polished, professional look" that resembles a piece of designer art, not just a simple toy.

---
## The Infinity Tech XX
Author: Infinity Team
Date: 2025-07-20
Category: the infinity tech
URL: https://theinfinity.dev/articles/the-infinity-tech-xx
## 🚀**Happy Monday!**
**Welcome to The Infinity Tech!**
This week, we’re welcoming **28 new members** to our growing tech community. Let’s dive into this week’s highlights with **Galactic Sync** – your quick and sharp roundup of the latest in Tech!
🛸**This week’s highlights:**
🔹Making Software: How does a screen work?
🔹NSFW AI Girlfriend Leaks in Grok's New Update!
🔹 Another Chinese AI model is turning heads
🔹Elasticsearch vs. OpenSearch: The SHOCKING 2025 Winner Revealed!
🔹 A technical deep-dive into open-source projects.(Open Source Analysis)
## Tech Orbit

---
### **Tech News**
🔹[The sound](https://tomrenner.com/posts/llm-inevitabilism/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=a2c8b68eda71cbe3d5c7ffb5ce302843657c5b02)of inevitability
🔹[Reflections](https://calv.info/openai-reflections?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=9da23a3d68c126fdced9b3038616f749e4f40b3e)on OpenAI
🔹[NSFW AI Girlfriend](https://www.testingcatalog.com/grok-debuts-interactive-ai-companions-on-ios-with-anime-avatars/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=e64805c7996a3f1fab7a2d7082c865d6b8266000)Leaks in Grok's New Update!
🔹[Microsoft's AI Can](https://www.theverge.com/news/685963/microsoft-copilot-vision-windows-launch?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=2c2982efce0fd877ba660531dfaae3d3b4d454ed)Now *SEE* Your Screen! (And It's Creepy)
🔹[Another Chinese AI](https://www.nbcnews.com/tech/tech-news/another-chinese-ai-model-turning-heads-rcna218666?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=f21749a4f7e95bc928213e19cb6cc6542e48afce) model is turning heads
🔹[Introducing](https://openai.com/index/introducing-chatgpt-agent/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=19a3d9cafac52281f7e8816a3f77f5cbb0106ce6)ChatGPT agent
### **Tech Articles**
🔹[API Performance Nightmare? 5 Secret Tricks to Speed it UP!](https://blog.bytebytego.com/p/ep172-top-5-common-ways-to-improve?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=b3576722ed58eeade0dccd2a926c442c10f8c6f2)
🔹[Elasticsearch vs. OpenSearch: The SHOCKING 2025 Winner Revealed!](https://medium.com/@FrankGoortani/opensearch-vs-elasticsearch-a-comprehensive-comparison-in-2025-aff5a8533422?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=f3502d8ad36680f72503f47f881ec173e916331d)
🔹[Netflix's Secret Weapon: How They Conquered Live Streaming!](https://netflixtechblog.com/behind-the-streams-live-at-netflix-part-1-d23f917c2f40?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=511b86c400d40dac4f7dde8e7b45a2d25852f7a6)
🔹[Your "Open Door" Policy Is a LIE! (And Here's Why)](https://www.blog4ems.com/p/your-open-door-policy-is-pretty-useless?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=503e5388d7833592d96f9d7c44943daec4bbe5c9)
###
## Asteroid Ventures

---
### **Companies News**
🔹[BrightAI](https://bright.ai/blog/brightai-51m-series-a-physical-ai/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=eebf935a820436eaea1a24768a53f5b185438b75)Raises $51M Series A Funding
🔹[Bedrock Robotics](https://techcrunch.com/2025/07/16/ex-waymo-engineers-launch-bedrock-robotics-with-80m-to-automate-construction/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=dd3f2360d7a248c9a447a1125e08eab7c40d201f)Announces $80M Seed and Series A
🔹[Backstroke](https://www.backstroke.com/blog/next-gen-visual-tools-for-email-marketing?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=9216c09751fa7cd651c39ae42b826cbffedb524f)Closes $2.8M Growth Funding
🔹[Hadrian](https://techcrunch.com/2025/07/17/hadrian-raises-260m-to-build-out-automated-factories-for-space-and-defense-parts/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=928f63349bb7bcede4d9698bfa488e386a3877d9)Grabs $260M Series C Financing
## Black Hole

---
[https://www.makingsoftware.com/chapters/how-a-screen-works?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=4f09291cd583878e3c3dc165defb82543f7917b5](https://www.makingsoftware.com/chapters/how-a-screen-works?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=4f09291cd583878e3c3dc165defb82543f7917b5)
[https://bleuje.com/physarum-explanation/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=ea388ffd062638d1d417394d44ec3910c0299cc9](https://bleuje.com/physarum-explanation/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=ea388ffd062638d1d417394d44ec3910c0299cc9)
[https://drew.silcock.dev/blog/artisanal-git/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=8d4e9b54bf35e61320477f9246fe76822335dc38](https://drew.silcock.dev/blog/artisanal-git/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=8d4e9b54bf35e61320477f9246fe76822335dc38)
## Cosmic Currents

[▶ Video](https://youtu.be/E6BU6fMgojc)
## Open Source Analysis

[https://opensourcedaily.blog/localsend-cross-platform-open-source-airdrop-alternative/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=72649598a846b05c766c47d76a1edfa2516f6c35#google_vignette](https://opensourcedaily.blog/localsend-cross-platform-open-source-airdrop-alternative/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=72649598a846b05c766c47d76a1edfa2516f6c35#google_vignette)
[https://opensourcedaily.blog/pinepods-the-self-hosted-podcast-platform/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=dbca8f2fcb1b326a75e619b9c75075d58dd6de5a](https://opensourcedaily.blog/pinepods-the-self-hosted-podcast-platform/?utm_source=www.theinfinity.dev&utm_medium=newsletter&utm_campaign=the-infinity-tech-xx&_bhlid=dbca8f2fcb1b326a75e619b9c75075d58dd6de5a)
## Double Star

---
### Open Source Repositories
> 📦 **gitleaks**
> Find and prevent secrets from leaking into your Git repositories.
> [https://github.com/gitleaks/gitleaks](https://github.com/gitleaks/gitleaks)*secret-detection, Go, devops-tool*
> 📦 **stagewise**
> Frontend coding agent that lives in your browser and modifies your web app's codebase.
> [https://github.com/stagewise-io/stagewise](https://github.com/stagewise-io/stagewise)*coding-agent, JavaScript, ai-assistant*
> 📦 **maigret**
> Uncover personal information online using usernames.
> [https://github.com/soxoj/maigret](https://github.com/soxoj/maigret)*osint-tool, Python, security-tool*
> 📦 **Hyprland**
> Highly customizable, dynamic tiling Wayland compositor with a focus on aesthetics.
> [https://github.com/hyprwm/Hyprland](https://github.com/hyprwm/Hyprland)*wayland-compositor, Wayland, open-source-alternative*
> 📦 **mediamtx**
> Ready-to-use media server and proxy for SRT, WebRTC, RTSP, RTMP, and more.
> [https://github.com/bluenviron/mediamtx](https://github.com/bluenviron/mediamtx)*media-server, Go, self-hosted*
> 📦 **sweetalert2**
> Beautiful, customizable, accessible alert boxes for JavaScript.
> [https://github.com/sweetalert2/sweetalert2](https://github.com/sweetalert2/sweetalert2)*javascript-library, JavaScript, open-source-alternative*
## Galactic Meme


## Celestial Quotes

> “Sex × Technology = the Future.”― **J.G. Ballard**
## Stellar Prompts

---
### **The Copy-Paste AI Prompt for a Perfect Glass Effect**
Tired of inconsistent results from your AI image generator? Here is a reliable, ready-to-use prompt designed to create stunning, photorealistic glass objects with a clean studio look.
Simply use the parameters below. You can replace the main "object" with whatever you wish to create.
```bash
Style: photorealistic
Material: glass
Background: plain white
Object Position: centered
Lighting: soft, diffused studio lighting
Camera Angle: eye-level, straight-on
Resolution: high
Aspect Ratio: 2:3
Details:
Reflections: true
Shadows: false
Transparency: true
```

---
## HashiCorp Vault Cluster Setup with Raft Backend, Nginx Reverse Proxy with Keepalived
Author: Serdarcan Büyükdereli
Date: 2025-06-02
Category: DevOps Blog
URL: https://theinfinity.dev/articles/hashicorp-vault-cluster-setup
## **Introduction**
A HashiCorp Vault cluster on the Raft backend keeps storage and consensus in-process, so all you add in front of it is an Nginx reverse proxy for TLS and Keepalived for a floating IP that survives losing a proxy node.
- **HashiCorp Vault:** Stores, manages and hands out secrets — API keys, passwords, certificates.
- **Raft Backend:** This is Vault's built-in consensus mechanism for high availability, eliminating the need for external dependencies like Consul or PostgreSQL for the storage backend. This simplifies the architecture for HA considerably.
- **Nginx Reverse Proxy:** Nginx will act as the public-facing endpoint, forwarding requests to the Vault cluster. This allows for SSL termination, basic load balancing, and can add an extra layer of security.
- **Keepalived:** This is key for Nginx's high availability. Keepalived implements VRRP (Virtual Router Redundancy Protocol) to provide a floating IP (Virtual IP or VIP). If the primary Nginx server fails, Keepalived automatically moves the VIP to a healthy backup Nginx server, ensuring continuous service.
This is a common pattern for putting HA in front of a service like Vault.
---
## **Prerequisites**
- Docker
- Docker Compose
- Git
- Make
That list points at a local development or test machine rather than production hardware:
- **Docker & Docker Compose:** Containerize Vault, Nginx and Keepalived so the whole setup is reproducible and isolated.
- **Git & Make:** Clone the repository and automate the build and run steps.
For a **production environment**, you'd move past plain Docker Compose. Consider:
- **Kubernetes/OpenShift:** For orchestrating containers at scale, providing built-in HA, self-healing, and service discovery.
- **Infrastructure as Code (IaC):** Tools like Terraform for provisioning underlying infrastructure (VMs, networks, load balancers).
- **Cloud-Native Solutions:** Utilizing cloud-specific load balancers (AWS ELB/ALB, Azure Load Balancer, GCP Load Balancer) for the Nginx layer, which offer managed HA and scalability out-of-the-box.
- **Secrets Management for Vault itself:** How will the initial root token and unseal keys be handled securely?
### **Vault Server Configuration (vault.hcl)**
Vault servers are configured using an HCL (HashiCorp Configuration Language) file. Here’s an example `vault.hcl`:
```bash
storage "raft" {
path = "/vault/data"
node_id = "node1" # This should be unique for each node
}
listener "tcp" {
address = "0.0.0.0:8200"
tls_disable = "true" # IMPORTANT: Only for development/testing!
}
cluster_addr = "http://node1:8201" # This should be unique for each node
api_addr = "http://node1:8200" # This should be unique for each node
```
This is the core configuration for a Vault server in a Raft cluster, stanza by stanza:
- `storage "raft"`:
- `path`: Specifies where Raft data (Vault's operational data, state) will be stored persistently. This *must* be mapped to a persistent volume outside the container in a production setup to prevent data loss on container restart or deletion.
- `node_id`: This must be unique for each Vault instance in the cluster. The example above uses `node1`; in a 3-node cluster you would have `node1`, `node2`, `node3`.
- Raft provides strong consistency and self-healing. It requires a quorum (majority) of nodes to be healthy for writes to proceed. For a cluster of `N` nodes, you need `(N/2) + 1` healthy nodes. Common cluster sizes are 3 or 5 nodes.
- `listener "tcp"`:
- `address`: `0.0.0.0:8200` means Vault listens on all available network interfaces on port 8200.
- `tls_disable = "true"`: **This is a critical security warning!** As the comment states, this is *only* for development or scenarios where an external component (like Nginx in this case) handles TLS. **In any production environment, Vault should always use TLS directly** (`tls_disable = "false"`) with proper certificates. Even if Nginx handles external TLS, communication *between* Nginx and Vault, and *between* Vault nodes, should ideally be TLS-encrypted for defense in depth.
- `cluster_addr`: The address Vault uses to communicate with *other* Vault nodes in the Raft cluster. This is essential for inter-node communication and Raft consensus. It's often on a dedicated "cluster" port (e.g., 8201). Again, for each node, this should point to its own unique address.
- `api_addr`: The address where the Vault API is exposed. Clients (and the Nginx proxy) will connect to this address. Also, for each node, this should point to its own unique address.
The `node_id`, `cluster_addr`, and `api_addr` will need to be dynamically set for each Vault container, which Docker Compose can help with.
### **Vault Client Configuration for Auto-Unseal (client_vault.hcl)**
Vault can be configured for auto-unseal using cloud-native Key Management Services (KMS) like AWS KMS, Azure Key Vault, GCP KMS, or HashiCorp's own Transit Secrets Engine. This removes the manual unsealing step from automated deployment and recovery.
```bash
## This section demonstrates AWS KMS for auto-unseal
seal "awskms" {
region = "eu-west-1"
kms_key_id = "your-kms-key-id" # Replace with your actual KMS key ID
}
```
A freshly started Vault is sealed and cannot access its own data. Unsealing it by hand means providing a threshold of unseal keys every time. Auto-unseal offloads that to a trusted KMS service, so a node comes back on its own after a restart or an outage.
- `seal "awskms"`: The example shows AWS KMS. You'd need to configure the Vault server's IAM role (or credentials) to allow it to interact with the specified KMS key.
- **Alternatives:**
- **Azure Key Vault:** `seal "azurekeyvault"`
- **Google Cloud KMS:** `seal "gcpckms"`
- **HashiCorp Transit Secrets Engine:** `seal "transit"` (Requires another Vault cluster or dedicated instance for this, often used in multi-cluster scenarios or for air-gapped environments).
- **HashiCorp Cloud Platform (HCP) Vault:** For managed Vault, auto-unseal is handled automatically.
This `client_vault.hcl` snippet would be merged into the main `vault.hcl` or provided as an additional configuration snippet to the Vault server.
## **Docker Compose Setup**
Here's the `docker-compose.yml` file to orchestrate the services:
```bash
version: '3.8'
services:
vault1:
image: hashicorp/vault:1.15.2
container_name: vault1
cap_add:
- IPC_LOCK
ports:
- "8200:8200"
- "8201:8201"
environment:
VAULT_ADDR: "http://0.0.0.0:8200"
VAULT_API_ADDR: "http://vault1:8200"
VAULT_CLUSTER_ADDR: "http://vault1:8201"
VAULT_LOG_LEVEL: "info"
volumes:
- ./vault/config/vault1.hcl:/vault/config/vault.hcl # Mount config for each node
- ./vault/data1:/vault/data # Mount persistent data volume for each node
networks:
- vault_network
command: "server -config=/vault/config/vault.hcl"
# vault2 and vault3 would be similar, with unique node_id, data paths, and container names/hostnames
vault2:
image: hashicorp/vault:1.15.2
container_name: vault2
cap_add:
- IPC_LOCK
ports:
- "8202:8200" # Exposing on different host port for local access if needed
- "8203:8201"
environment:
VAULT_ADDR: "http://0.0.0.0:8200"
VAULT_API_ADDR: "http://vault2:8200"
VAULT_CLUSTER_ADDR: "http://vault2:8201"
VAULT_LOG_LEVEL: "info"
volumes:
- ./vault/config/vault2.hcl:/vault/config/vault.hcl
- ./vault/data2:/vault/data
networks:
- vault_network
command: "server -config=/vault/config/vault.hcl"
depends_on:
- vault1 # Simple dependency, not for HA
vault3:
image: hashicorp/vault:1.15.2
container_name: vault3
cap_add:
- IPC_LOCK
ports:
- "8204:8200"
- "8205:8201"
environment:
VAULT_ADDR: "http://0.0.0.0:8200"
VAULT_API_ADDR: "http://vault3:8200"
VAULT_CLUSTER_ADDR: "http://vault3:8201"
VAULT_LOG_LEVEL: "info"
volumes:
- ./vault/config/vault3.hcl:/vault/config/vault.hcl
- ./vault/data3:/vault/data
networks:
- vault_network
command: "server -config=/vault/config/vault.hcl"
depends_on:
- vault1 # Simple dependency, not for HA
nginx1:
image: nginx:latest
container_name: nginx1
ports:
- "80:80"
- "443:443"
volumes:
- ./nginx/nginx.conf:/etc/nginx/nginx.conf:ro
- ./nginx/ssl:/etc/nginx/ssl:ro # For SSL certificates
networks:
- vault_network
depends_on:
- vault1 # Nginx depends on at least one Vault node to start
nginx2:
image: nginx:latest
container_name: nginx2
ports:
# Nginx2 will likely not have 80/443 exposed directly on host, Keepalived handles VIP
# but if you need to access it directly for testing, you could map different ports
# - "81:80"
# - "444:443"
# For Keepalived VIP, these ports are usually not mapped to host
volumes:
- ./nginx/nginx.conf:/etc/nginx/nginx.conf:ro
- ./nginx/ssl:/etc/nginx/ssl:ro
networks:
- vault_network
depends_on:
- vault1
keepalived:
image: osixia/keepalived:latest
container_name: keepalived
cap_add:
- NET_ADMIN # Required for VIP management
- NET_BROADCAST
- NET_RAW
environment:
KEEPALIVED_STATE: MASTER # For the first instance, the other would be BACKUP
KEEPALIVED_INTERFACE: eth0 # Or the correct network interface inside the container
KEEPALIVED_VIRTUAL_IPS: "172.18.0.100/24" # Example VIP, adjust subnet
KEEPALIVED_UNICAST_PEERS: "172.18.0.x,172.18.0.y" # IPs of other keepalived containers
KEEPALIVED_PASSWORD: "your_vrrp_password" # Important for security
KEEPALIVED_PRIORITY: "101" # Higher for MASTER
KEEPALIVED_VIRTUAL_ROUTER_ID: "51" # Unique ID for VRRP instance
volumes:
- ./keepalived/keepalived.conf:/etc/keepalived/keepalived.conf:ro # Custom config if needed
networks:
- vault_network
sysctls:
- net.ipv4.ip_nonlocal_bind=1 # Allow binding to non-local IP (VIP)
depends_on:
- nginx1
- nginx2
networks:
vault_network:
driver: bridge
ipam:
config:
- subnet: 172.18.0.0/24 # Example subnet
```
Going through the file service by service:
- **Vault Services (vault1, vault2, vault3):**
- `image: hashicorp/vault:1.15.2`: Using a specific, stable version is good practice.
- `cap_add: - IPC_LOCK`: Essential for Vault. It prevents Vault from swapping sensitive data to disk, improving security.
- `ports`: Mapping container ports to host ports. For `vault2` and `vault3`, the host ports `8202:8200` and `8203:8201` (etc.) are for *local host access* if you want to curl each Vault node directly. In a real-world scenario, you might not expose these ports directly on the host if Nginx is the sole entry point. Internal communication within `vault_network` uses the container names (`vault1:8200`).
- `environment`: Dynamically sets `VAULT_API_ADDR` and `VAULT_CLUSTER_ADDR` to the container's *own hostname*. This is critical for inter-Vault communication and how Nginx finds them.
- `volumes`:
- `./vault/config/vaultX.hcl:/vault/config/vault.hcl`: Each Vault container gets its specific configuration file, ensuring `node_id` and addresses are correctly set for *that* instance.
- `./vault/dataX:/vault/data`: This maps the Vault data directory *outside* the container to a named volume or host path. Without it, all Vault data is lost when the container is removed. In production this would be a highly available shared storage solution or cloud block storage.
- `networks: - vault_network`: All services are on the same bridge network, allowing them to communicate by container name (e.g., `nginx1` can reach `vault1`).
- `depends_on`: Simple startup order, **not for ensuring HA**. If `vault1` dies, `vault2` and `vault3` won't restart automatically due to `depends_on`. Proper orchestration (Kubernetes) handles this.
- **Nginx Services (nginx1, nginx2):**
- `ports: - "80:80" - "443:443"`: Nginx listens on standard HTTP/HTTPS ports. Note that for `nginx2` (the backup), these ports might not be directly mapped to the host if Keepalived is managing the VIP. Only the Master Nginx will have the VIP bound.
- `volumes`: Mounting `nginx.conf` and `ssl` directories for configuration and certificates. **For production, replace placeholder SSL certs with real, trusted ones (Let's Encrypt, commercial CAs).**
- `depends_on`: Nginx needs Vault to be up, but again, this is basic.
- **Keepalived Service:**
- `image: osixia/keepalived:latest`: A convenient pre-built Keepalived container.
- `cap_add: - NET_ADMIN, - NET_BROADCAST, - NET_RAW`: These capabilities are absolutely necessary for Keepalived to manage network interfaces and IPs (like the VIP).
- `environment`:
- `KEEPALIVED_STATE`: `MASTER` for the primary, `BACKUP` for the secondary.
- `KEEPALIVED_INTERFACE`: `eth0` is a common default for Docker bridge networks. Verify it's the correct interface *inside the container*.
- `KEEPALIVED_VIRTUAL_IPS`: The Virtual IP (VIP) that will float between the Nginx instances. This is the single entry point for clients.
- `KEEPALIVED_UNICAST_PEERS`: The *internal network IPs* of the *other Keepalived containers*. This is how Keepalived instances find and communicate with each other (VRRP heartbeat). This will be `172.18.0.X` based on your Docker network.
- `KEEPALIVED_PASSWORD`: **Important for securing VRRP communication.**
- `KEEPALIVED_PRIORITY`: Higher value for the desired MASTER.
- `KEEPALIVED_VIRTUAL_ROUTER_ID`: Unique ID for the VRRP instance within the network segment.
- `sysctls: - net.ipv4.ip_nonlocal_bind=1`: Allows Keepalived to bind to an IP address that isn't directly configured on the network interface (the VIP).
- `depends_on`: Keepalived needs Nginx to be up to perform health checks.
- `networks`: Defining a custom bridge network provides better isolation and allows using service names for internal communication.
This is a demonstration setup. For production, consider:
- **Persistent Storage:** Something more durable than host mounts (e.g., Docker volumes managed by a volume plugin, NFS, cloud block storage).
- **Networking:** Dedicated internal networks, possibly without port mapping to the host for Vault, relying solely on Nginx as the gateway.
- **Security:** Stronger firewalls, network ACLs, TLS everywhere.
- **Monitoring & Alerting:** Integration with Prometheus, Grafana, Alertmanager to track the health of Vault, Nginx, and Keepalived.
- **Secrets Management for Setup:** How will the KMS credentials for auto-unseal be provided securely to the Vault containers?
---
### **Vault Initialization & Unseal**
Once the Vault containers are running, you need to initialize the cluster. This is typically done from one of the Vault containers:
```bash
docker exec vault1 vault operator init -key-shares=3 -key-threshold=2 -format=json > cluster_keys.json
```
- `vault operator init`: This command performs the initial setup of the Vault cluster.
- `key-shares=3`: Generates 3 unseal keys.
- `key-threshold=2`: Requires 2 of these keys to unseal Vault. This adheres to the "N of M" security principle.
- `format=json > cluster_keys.json`: Outputs the root token and unseal keys to a JSON file.
**CRITICAL SECURITY WARNING:**
- **Securely store** `cluster_keys.json`: The root token and unseal keys are the "keys to the kingdom." **Do NOT leave this file on the server or in version control.** These should be distributed securely to trusted individuals (e.g., using a secure key management system, physical safe, or split knowledge).
- **Recovery Keys:** The `unseal_keys_b64` are also called recovery keys. These are needed if auto-unseal fails or if you need to manually unseal.
- **Root Token:** This token has full administrative privileges. Use it *only* for initial setup and creating a less privileged admin account. Then, revoke the root token.
- **Unsealing (Manual - if not using auto-unseal):** If auto-unseal is not configured, you would manually unseal each Vault node after initialization:
```bash
docker exec vault1 vault operator unseal
docker exec vault1 vault operator unseal
## Repeat for other nodes (vault2, vault3) using the same keys
```
With auto-unseal via KMS, this manual step is largely eliminated, which is a major advantage for production. The `seal "awskms"` configuration snippet would handle this automatically on startup.
---
## **Nginx Configuration (nginx.conf)**
This configuration enables Nginx to act as a reverse proxy for the Vault cluster, handling SSL/TLS.
```
http {
upstream vault_servers {
server vault1:8200;
server vault2:8200;
server vault3:8200;
# You can add load balancing algorithms here, e.g., least_conn, ip_hash
}
server {
listen 80;
server_name your.vault.domain.com; # Replace with your domain
return 301 https://$host$request_uri; # Redirect HTTP to HTTPS
}
server {
listen 443 ssl;
server_name your.vault.domain.com; # Replace with your domain
ssl_certificate /etc/nginx/ssl/vault.crt; # Your SSL certificate
ssl_certificate_key /etc/nginx/ssl/vault.key; # Your SSL private key
ssl_protocols TLSv1.2 TLSv1.3; # Enforce strong protocols
ssl_ciphers "EECDH+AESGCM:EDH+AESGCM:AES256+EECDH:AES256+EDH"; # Strong ciphers
ssl_prefer_server_ciphers on;
ssl_session_cache shared:SSL:10m;
ssl_session_timeout 10m;
location / {
proxy_pass http://vault_servers; # Proxy to the upstream Vault cluster
proxy_set_header Host $host;
proxy_set_header X-Real-IP $remote_addr;
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
proxy_set_header X-Forwarded-Proto $scheme;
proxy_connect_timeout 600;
proxy_send_timeout 600;
proxy_read_timeout 600;
send_timeout 600;
}
}
}
```
What this configuration does, block by block:
- `upstream vault_servers`:
- Defines a group of backend Vault servers. Nginx will automatically use a round-robin load balancing algorithm by default if no other is specified.
- **Recommendation:** For Vault, which relies on a single active leader, `least_conn` or `ip_hash` might sometimes be preferred, though simple round-robin works too. Vault clients are generally smart enough to retry if they hit a standby.
- **HTTP to HTTPS Redirect** (`listen 80` block): All HTTP traffic is forced to HTTPS.
- **HTTPS Server Block** (`listen 443 ssl` block):
- `ssl_certificate` / `ssl_certificate_key`: **Replace these with your actual production-ready SSL certificates and keys.** Never use self-signed certificates in production. Ensure these files are properly secured on the host.
- `ssl_protocols` / `ssl_ciphers`: Restricting to TLSv1.2 and TLSv1.3 with strong ciphers is the current baseline.
- `location /` block:
- `proxy_pass` [`http://vault_servers`](http://vault_servers/)`;`: This is the core instruction, forwarding all requests to the `vault_servers` upstream group.
- `proxy_set_header`: These headers are vital for Vault (and any proxied application) to correctly identify the original client's IP, hostname, and protocol. Without them, Vault would see Nginx's IP as the client.
- `proxy_connect_timeout`, etc.: These timeouts can be adjusted based on expected Vault response times, especially for long-running operations or during heavy load. 600 seconds (10 minutes) might be quite high; consider if such long requests are expected for Vault.
- **Security Considerations for Nginx:**
- **WAF (Web Application Firewall):** For production, consider integrating a WAF to protect against common web exploits.
- **Rate Limiting:** Implement Nginx rate limiting to prevent abuse or denial-of-service attacks.
- **Access Control:** Add `allow`/`deny` rules if access should be restricted to specific IP ranges.
- **Logging:** Configure comprehensive logging for auditing and troubleshooting.
---
## **Keepalived Configuration (keepalived.conf)**
Keepalived provides high availability for the Nginx instances by using VRRP to manage a floating IP address.
```
vrrp_script check_nginx {
script "killall -0 nginx" # Checks if nginx process is running
interval 2 # Check every 2 seconds
weight 50 # If script fails, priority decreases by 50
}
vrrp_instance VI_1 {
state MASTER # For the primary nginx instance, set to BACKUP for the secondary
interface eth0 # The network interface Keepalived will monitor
virtual_router_id 51 # Unique ID for this VRRP instance
priority 101 # Higher priority for MASTER, e.g., 100 for BACKUP
advert_int 1 # Advertisement interval in seconds
authentication {
auth_type PASS
auth_pass your_vrrp_password # Must match across all Keepalived instances
}
virtual_ipaddress {
172.18.0.100/24 # The Virtual IP address
}
track_script {
check_nginx # Link to the script defined above
}
notify_master "/etc/keepalived/notify.sh master"
notify_backup "/etc/keepalived/notify.sh backup"
notify_fault "/etc/keepalived/notify.sh fault"
}
```
The configuration above is a plain active-passive (master/backup) pair:
- `vrrp_script check_nginx`:
- `script "killall -0 nginx"`: This is a basic health check. It simply verifies if the `nginx` process is running.
- **Improvement:** The script should check whether Nginx is *actually serving* Vault requests, not just whether the process exists. A `curl -sL` [`http://localhost/vault/v1/sys/health`](http://localhost/vault/v1/sys/health) or similar (adjusted for port), checking for a 200 OK, would be better. If Nginx is running but unable to talk to Vault, Keepalived wouldn't failover.
- `interval`: How often the script runs.
- `weight`: If the script fails, this value is subtracted from the `priority`, potentially causing a failover.
- `vrrp_instance VI_1`:
- `state`: `MASTER` for the active node, `BACKUP` for the standby. Keepalived uses `priority` to determine the actual master.
- `interface`: The network interface on which the VRRP heartbeat and VIP will operate. It must match the Docker container's network interface (e.g., `eth0`).
- `virtual_router_id`: A unique identifier for this VRRP instance. All Keepalived instances managing the same VIP must share this ID.
- `priority`: Determines which node becomes master. Higher priority wins. If the master fails, the next highest priority backup takes over.
- `advert_int`: How often VRRP advertisements (heartbeats) are sent.
- `authentication`: Prevents unauthorized machines from joining your VRRP group. `PASS` is a simple password; consider using `AH` for stronger authentication in production.
- `virtual_ipaddress`: The floating IP address (VIP). This is the address clients will use to connect to your highly available service.
- `track_script check_nginx`: Links the health check script to the VRRP instance, triggering failover if the script fails.
- `notify_master`, `notify_backup`, `notify_fault`: These are shell scripts that can be executed when the Keepalived instance changes state. Useful for logging, sending alerts (e.g., to Slack, PagerDuty), or performing other actions during failover events.
**Overall for Keepalived:**
- If the primary Nginx server (or just its Nginx process) goes down, the VIP moves to the backup Nginx and clients keep using the same address.
- **Consider a 3-node Nginx/Keepalived setup for true fault tolerance:** A 2-node setup (master/backup) works, but if the master goes down and the backup also fails before the master recovers, you're out of service. A third node with proper health checks and priority management covers that case.
- **Placement:** In a VM environment, ensure Nginx/Keepalived pairs are on different physical hosts for true HA. In Docker Compose, they're on the same host unless you deploy them across multiple Docker Swarm/Kubernetes nodes.
---
## **Testing**
To verify the setup, you can check the status of Vault and Nginx.
**Vault Status:**
```bash
docker exec vault1 vault status
```
You should see output similar to this, indicating the cluster is initialized, sealed (if not auto-unsealed), and showing the leader.
```
Key Value
--- -----
Seal Type shamir
Initialized true
Sealed false
Total Shares 3
Threshold 2
Version 1.15.2
Build Date 2023-11-20T12:35:48Z
Storage Type raft
Cluster Name vault-cluster-d6d7e0d7
Cluster ID 2430ae1c-2234-7a32-1b1a-8252277d0180
HA Enabled true
HA Cluster https://vault1:8201 # This will vary based on your env
HA Mode active
Active Since 2023-12-01T10:00:00Z
```
**Nginx Status (via VIP):** Access your configured [`your.vault.domain.com`](http://your.vault.domain.com/) (or the VIP directly) in your browser or with `curl`.
```bash
curl -k https://your.vault.domain.com/v1/sys/health
```
You should get a JSON response indicating Vault's health status. The `-k` flag is important if you're using self-signed certificates for testing.
What to look for, and what to break on purpose:
- `vault status`: Pay attention to:
- `Sealed`: Should be `false` if auto-unseal is working.
- `HA Enabled`: Should be `true`.
- `HA Mode`: One node should be `active` (the leader), others `standby`.
- `Storage Type`: Should be `raft`.
- **Nginx/VIP Testing:**
- **Failover Test:** The most important test is to simulate a failure.
- Stop the `nginx1` container (`docker stop nginx1`). Observe the Keepalived logs (if running `keepalived` in a separate terminal) to see the failover.
- Verify that [`your.vault.domain.com`](http://your.vault.domain.com/) (or the VIP) still responds, now served by `nginx2`.
- Restart `nginx1` and observe if it correctly takes back the master role (preemption) or if `nginx2` remains master.
- **Vault Node Failure Test:**
- Stop the `vault1` container (`docker stop vault1`).
- Verify that the Vault cluster remains healthy (if you have 3 nodes, you still have a quorum). `vault status` on `vault2` or `vault3` should show them as active/standby.
- Ensure Nginx can still proxy to the remaining healthy Vault nodes.
- **Secrets Test:** Create a secret via the VIP (`vault kv put secret/test value=hello`), then try to read it (`vault kv get secret/test`). This verifies end-to-end functionality.
---
## **Conclusion**
This layout fits a specific case: Vault on your own VMs, high availability without pulling in Consul or a managed load balancer. On a single Docker host it stays a demonstration — the three Vault nodes, both Nginx instances and Keepalived share one failure domain, so nothing really fails over. If you already run Kubernetes or a cloud load balancer in front of your services, the Keepalived layer is a moving part you don't need.
**Before production, the open items are:**
1. **Observability:**
- **Monitoring:** Collect metrics from Vault (using `telemetry` stanza in `vault.hcl`), Nginx, and Keepalived (e.g., using Prometheus Node Exporter) to track performance, health, and potential issues.
- **Logging:** Centralize logs (e.g., ELK Stack, Splunk, Loki) for easier troubleshooting and auditing.
- **Alerting:** Set up alerts based on key metrics (e.g., Vault sealed, Nginx down, high error rates).
2. **Security:**
- **Network Segmentation:** Isolate Vault and its backend storage in dedicated, private network segments.
- **Firewalls:** Implement strict firewall rules (Security Groups, Network ACLs) to limit access to Vault and its components.
- **Vault Policies and Authentication:** Define granular policies and use appropriate authentication methods (e.g., LDAP, Kubernetes Auth Method, AWS/Azure/GCP Auth Methods) for users and applications accessing secrets.
- **Audit Logging:** Enable and review Vault's audit logs for compliance and security monitoring.
3. **Operations:**
- **Automated Deployment:** Use IaC tools (Terraform, Ansible, Chef, Puppet) or Kubernetes/Helm charts for consistent, automated deployment and management of the entire stack.
- **Backup and Restore:** Implement a backup and restore strategy for Vault's Raft data.
- **Disaster Recovery:** Plan and regularly test for regional outages or major failures.
- **Upgrades:** Have a strategy for upgrading Vault, Nginx, and Keepalived with minimal downtime.
- **Secrets Rotation:** Automate the rotation of secrets where possible (e.g., database credentials).
---
## Ceph Cluster OSD Removal Guide
Author: Serdarcan Büyükdereli
Date: 2025-03-06
Category: DevOps Blog
URL: https://theinfinity.dev/articles/ceph-cluster-osd-removal-guide
## **Overview**
This document explains step-by-step how to safely remove OSDs from a live Ceph cluster without data loss or downtime. Continuously monitoring the cluster's health during the process is critically important.
## **Preparations**
- **Cluster Health:** Before starting the process, check the overall health status of the cluster using the `ceph -s` command.
- **Data Distribution:** Observe how the data of the OSDs is distributed using the `ceph osd tree` or `ceph osd df` commands.
- **Batch Process:** If you need to remove multiple OSDs, for safety, remove 1-2 OSDs at a time and check the cluster's balance after each step.
## **Step-by-Step Process**
## **1. Mark the OSD as "Out"**
- **Purpose:** Stop writing new data to the OSD and start transferring existing data to other OSDs.
**Command:**
**Copy**
```bash
ceph osd out
```
**Example:**
**Copy**
```bash
ceph osd out 34
```
> Note: When the command is executed, you should receive the message "marked out osd.34."
## **2. Monitor Cluster Status**
**Purpose:** Ensure the rebalance process is complete.
**Command:**
**Copy**
```bash
ceph -s
```
**Checkpoints:**
- Ensure all PGs are in the "active+clean" state.
- Observe that the recovery speed is increasing and the number of remapped PGs is decreasing.
## **3. Removing the OSD from the CRUSH Map**
**Purpose:** Remove the OSD from the CRUSH map so it no longer participates in the cluster's data distribution.
**Command:**
**Copy**
```bash
ceph osd crush remove
```
**Example:**
**Copy**
```bash
ceph osd crush remove osd.34
```
**Checkpoints:**
- Ensure all PGs are in the "active+clean" state.
- Observe that the recovery speed is increasing and the number of remapped PGs is decreasing.
- **Copy**
```bash
ceph -s
```
## **4. Removing OSD Authorization**
**Purpose:** Remove the authentication information associated with the OSD.
**Command:**
**Copy**
```bash
ceph auth del osd.
```
**Example:**
**Copy**
```bash
ceph auth del osd.34
```
## **5. Removing the OSD from the Cluster**
**Purpose:** Completely delete the OSD's record from the Ceph cluster.
**Command:**
**Copy**
```bash
ceph osd down
ceph osd rm
```
**Example:**
**Copy**
```bash
ceph osd down 34
ceph osd rm 34
```
Sometimes the `ceph osd down` command works, but the `rm` command might not. In that case, you may need to stop the service on the OSD node using `systemctl`.
**Copy**
```bash
systemctl stop ceph.34.service
```
## **Example: Removing an OSD Node**
**Copy**
```bash
ceph osd crush rm
```
We are removing the node from the crush map.
**Copy**
```bash
ceph orch host drain
```
We are removing all services from the node by draining it.
**Copy**
```bash
ceph orch daemon rm osd.34 --force
```
We are removing the remaining OSDs on the node as a daemon.
**Copy**
```bash
ceph orch host rm
```
Finally, we completely remove the node. It will no longer appear in our host list.
### **Additional Notes**
**Process Intervals:**
After each step, be sure to check the cluster status with the `ceph -s` command. Only proceed to the next step once it is in a healthy `(active+clean)` state.
**Total Number of OSDs:**
If there are 35 OSDs in the cluster and you want to remove, for example, 15 OSDs, perform the operation in small groups (2-3 at a time) instead of removing them all at once.
**Conclusion**
By carefully following these steps, you can remove OSDs from a live Ceph cluster without any downtime. Continuously monitoring the cluster's health and proceeding in small steps will help prevent data loss and performance issues.
---
## Harbor Container Registry - HA Architecture Setup
Author: Serdarcan Büyükdereli
Date: 2025-01-09
Category: DevOps Blog
URL: https://theinfinity.dev/articles/harbor-container-registry-ha-architecture-setup
## **Key Advantages of Harbor**
- **Security:** Strong authentication, RBAC, and security scanning features
- **Integration:** Easy integration with Kubernetes and Docker
- **Performance:** Fast image distribution and management
- **Scalability:** High availability and replication support
- **Management:** User-friendly web interface and project-based organization
By setting up our system on virtual machines instead of Kubernetes, we minimized the risk of downtime and simplified management.
## **Why Do We Use Separate Servers?**
- **Uninterrupted Service:** Operates independently from Kubernetes cluster maintenance
- **Resource Management:** Dedicated resource allocation and optimization
- **Simple Management:** Less complex infrastructure
- **Security:** Isolated security layers
This setup ensures Harbor operates more stably and reliably while also making management easier.

## **Setup**
Requirements:
1. Load Balancer - 2 Servers (HAProxy and Keepalived)
- 192.168.10.101 LoadBalancer-1
- 192.168.10.102 LoadBalancer-2
- 192.168.10.100 (Keepalived IP)
2. Main - 2 Harbor installations (same configurations)
- 192.168.10.111 Main-1
- 192.168.10.112 Main-2
3. NFS Cluster (Existing or new NFS, GlusterFS, CephFS Cluster)
- 192.168.10.120
4. PostgreSQL Cluster (An existing setup can be used)
- 192.168.10.121
5. Redis Cluster (An existing setup can be used)
- 192.168.10.122
An example server architecture configuration is shown above.
## **Load Balancer**
As seen in the image, there are 2 Load Balancers in the system, and they operate in an active-passive structure.
### **Load Balancer-1**
The **HAProxy** configuration is as follows. The only difference between Load Balancer-1 and Load Balancer-2 is the load balancer IP in the `monitor-stats` section.
- Directs the Harbor main servers in an active-passive manner.
- SSL control is done through /etc/haproxy/cert.pem. You can use it by assigning a domain to the IP 192.168.10.100.
**Copy**
```bash
cat /etc/haproxy/haproxy.cfg
```
**Copy**
```
global
log /dev/log local0
log /dev/log local1 notice
chroot /var/lib/haproxy
stats socket /run/haproxy/admin.sock mode 660 level admin
stats timeout 30s
user haproxy
group haproxy
daemon
maxconn 10000
tune.ssl.default-dh-param 2048
listen monitor-stats
mode http
bind 192.168.10.101:7000
stats enable
stats uri /
defaults
log global
option httplog
option dontlognull
timeout connect 5000ms
timeout client 50000ms
timeout server 50000ms
timeout http-request 10s
timeout http-keep-alive 10s
errorfile 400 /etc/haproxy/errors/400.http
errorfile 403 /etc/haproxy/errors/403.http
errorfile 408 /etc/haproxy/errors/408.http
errorfile 500 /etc/haproxy/errors/500.http
errorfile 502 /etc/haproxy/errors/502.http
errorfile 503 /etc/haproxy/errors/503.http
errorfile 504 /etc/haproxy/errors/504.http
frontend harbor_frontend
bind *:443 ssl crt /etc/haproxy/cert.pem
mode http
default_backend harbor_backend
backend harbor_backend
mode http
#option httpchk GET /
server harbor1 192.168.10.111:443 ssl verify none check
server harbor2 192.168.10.112:443 ssl verify none check backup
```
**Keepalived**
- High availability between two load balancers:
- Primary server: 192.168.10.101
- Backup server: 192.168.10.102
- The HAProxy service is checked every 2 seconds and automatically switches over in case of an issue
- Provides uninterrupted access to the Harbor registry with virtual IP 192.168.10.100
**Copy**
```bash
cat /etc/keepalived/keepalived.conf
```
**Copy**
```
## Global Settings for notifications
global_defs {
}
## Define the script used to check if haproxy is still working
vrrp_script chk_haproxy {
script "/usr/bin/killall -0 haproxy"
interval 2
weight 2
}
## Configuration for Virtual Interface
vrrp_instance LB_VIP {
interface ens192
state MASTER # set to BACKUP on the peer machine
priority 101 # set to 99 on the peer machine
virtual_router_id 20
smtp_alert # Enable Notifications Via Email
authentication {
auth_type PASS
auth_pass MYP@ssword # Password for accessing vrrpd. Same on all devices
}
unicast_src_ip 192.168.10.101 # Private IP address of master
unicast_peer {
192.168.10.102
}
# The virtual ip address shared between the two loadbalancers
virtual_ipaddress {
192.168.10.100
}
# Use the Defined Script to Check whether to initiate a fail over
track_script {
chk_haproxy
}
}
```
### **Loadbalancer-2**
Loadbalancer-2 operates as a backup server. The HAProxy configuration is the same as Loadbalancer-1, with the only difference being the monitor-stats IP is 192.168.10.102.
In the Keepalived configuration, there are these important differences:
- The state is set to BACKUP
- The priority is lowered to 100 (lower than the main server)
- The unicast_src_ip is its own IP, 192.168.10.102
**Copy**
```
global
log /dev/log local0
log /dev/log local1 notice
chroot /var/lib/haproxy
stats socket /run/haproxy/admin.sock mode 660 level admin
stats timeout 30s
user haproxy
group haproxy
daemon
maxconn 10000
tune.ssl.default-dh-param 2048
listen monitor-stats
mode http
bind 192.168.10.102:7000
stats enable
stats uri /
defaults
log global
option httplog
option dontlognull
timeout connect 5000ms
timeout client 50000ms
timeout server 50000ms
timeout http-request 10s
timeout http-keep-alive 10s
errorfile 400 /etc/haproxy/errors/400.http
errorfile 403 /etc/haproxy/errors/403.http
errorfile 408 /etc/haproxy/errors/408.http
errorfile 500 /etc/haproxy/errors/500.http
errorfile 502 /etc/haproxy/errors/502.http
errorfile 503 /etc/haproxy/errors/503.http
errorfile 504 /etc/haproxy/errors/504.http
frontend harbor_frontend
bind *:443 ssl crt /etc/haproxy/cert.pem
mode http
default_backend harbor_backend
backend harbor_backend
mode http
#option httpchk GET /
server harbor1 192.168.10.111:443 ssl verify none check
server harbor2 192.168.10.112:443 ssl verify none check backup
```
Keepalived configuration:
**Copy**
```
## Global Settings for notifications
global_defs {
}
## Define the script used to check if haproxy is still working
vrrp_script chk_haproxy {
script "/usr/bin/killall -0 haproxy"
interval 2
weight 2
}
## Configuration for Virtual Interface
vrrp_instance LB_VIP {
interface ens192
state BACKUP # set to BACKUP on the peer machine
priority 100 # set to 99 on the peer machine
virtual_router_id 20
smtp_alert # Enable Notifications Via Email
authentication {
auth_type PASS
auth_pass MYP@ssword # Password for accessing vrrpd. Same on all devices
}
unicast_src_ip 192.168.10.102 # Private IP address of master
unicast_peer {
192.168.10.101
}
# The virtual ip address shared between the two loadbalancers
virtual_ipaddress {
192.168.10.100
}
# Use the Defined Script to Check whether to initiate a fail over
track_script {
chk_haproxy
}
}
```
## **Harbor Main Servers**
For Harbor installation, you first need to install the requirements specified in the [**https://goharbor.io/docs/1.10/install-config/installation-prereqs/**](https://goharbor.io/docs/1.10/install-config/installation-prereqs/) document and perform system updates.
### **NFS Connection**
Let's mount the /data directory to the NFS cluster on the Main-1 and Main-2 servers:
**Copy**
```
vi /etc/fstab
192.168.10.120:/mnt/harbor-data /data nfs4 rsize=1048576,wsize=1048576,noatime,nodiratime 0 0
mount -a
```
With this configuration, data will be stored on the NFS server. If there is an issue with the Main-1 server, the Main-2 (backup) server will automatically take over. Since the data is kept on the NFS cluster, it will be stored redundantly.
### **Harbor Installation (Same for Main-1 and Main-2)**
**Copy**
```bash
wget
tar xfv harbor-online-installer-v2.11.1.tgz
cd harbor
mv harbor.yml.tmpl harbor.yml
./prepare
mv /serdarcanb.cert /data/cert/registry.serdarcanb.com.cert
mv /serdarcanb.key /data/cert/registry.serdarcanb.com.key
vi harbor.yml
./install.sh --with-trivy
```
### **Harbor Configuration**
The content of the harbor.yml file for both servers:
**Copy**
```yaml
http:
port: 80
hostname: registry.serdarcanb.com
https:
port: 443
certificate: /data/cert/registry.serdarcanb.com.cert
private_key: /data/cert/registry.serdarcanb.com.key
harbor_admin_password: Serdarcanb!23
data_volume: /data
trivy:
ignore_unfixed: true
skip_update: false
skip_java_db_update: false
offline_scan: false
security_check: vuln
insecure: false
timeout: 5m0s
jobservice:
max_job_workers: 10
job_loggers:
- STD_OUTPUT
- FILE
logger_sweeper_duration: 1
notification:
webhook_job_max_retry: 3
webhook_job_http_client_timeout: 3
log:
level: info
local:
rotate_count: 50
rotate_size: 200M
location: /var/log/harbor
_version: 2.11.0
proxy:
http_proxy:
https_proxy:
no_proxy:
components:
- core
- jobservice
- trivy
metric:
enabled: true
port: 9090
path: /metrics
upload_purging:
enabled: true
age: 168h
interval: 24h
dryrun: false
cache:
enabled: true
expire_hours: 2
external_database:
harbor:
host: 192.168.10.121
port: 5432
db_name: harbor
username: devops
password: 1Serdarcan123
ssl_mode: disable
max_idle_conns: 10
max_open_conns: 100
external_redis:
host: 192.168.10.122
port: 6379
password: 1Serdarcan123
registry_db_index: 1
jobservice_db_index: 2
chartmuseum_db_index: 3
```
This Harbor configuration file (harbor.yml) includes the following basic settings:
- HTTP and HTTPS port settings (80 and 443)
- SSL certificate configuration
- Trivy security scanner settings
- Job service configuration
- Notification and logging settings
- Metrics and cache configuration
- External database connection (PostgreSQL - 192.168.10.121)
- External Redis connection (192.168.10.122)
With this configuration, the Harbor container registry is set to use external database and Redis services for high availability.
For PostgreSQL and Redis redundancy, it can be set up in a cluster structure. For more detailed configuration options, you can check the [**https://goharbor.io/docs/2.12.0/install-config/configure-yml-file/**](https://goharbor.io/docs/2.12.0/install-config/configure-yml-file/) page.
---